Women Architects and World Fairs

Author: Caroline Fenstermacher (Page 1 of 2)

Crowdsourcing and Games in the Museum

Throughout this semester, we have discussed several practical digital methods to make data visualization more accessible to greater audiences using timelines, charts, networks, maps, three-dimensional modeling, and more comprehensive, freely available metadata. This past week, we analyzed how crowdsourcing, volunteer, and collaborative-centered processes can be positive ways in which institutions enact these digital methods.

            One of the biggest crowdsourced resources available thanks to the advent of the Internet is Wikipedia. Wikipedia allows any user to freely edit and create Wikipedia pages while editors ensure that information is accurate with appropriate references. This framework is not perfect, though. Incorrect or biased information may escape editors’ notice just as much as honest information may be deleted or flagged as plagiarism. The overwhelming use of Wikipedia for daily reference by people worldwide, however, still makes it an incredibly powerful resource and useful for institutions that want to provide the best information about their collections.

GLAMwiki Heading, screenshot from Wikipedia site, https://en.wikipedia.org/wiki/Wikipedia:GLAM/Contribute.

GLAMwiki is an initiative by Wikipedia focusing on galleries, libraries, archives, and museums. It allows these institutions to create projects for pages that they would like to be created or updated. These projects are collaborative and provide editors with a specific collection or pages to begin editing. Institutions like the Smithsonian Archives of American Art and the British Museum have even had designated “Wikipedians in Residence” to either work directly with curators and museum experts to accurately convey information about their collections or by piloting community-based “edit-a-thon” events. The goal of GLAMwiki projects is to accurately inform Wikipedia users about objects in their collections, not as a promotional tool for the museum itself—although increased traffic to an institutions’ own website may be an added benefit. GLAMwiki utilizes the same collaborative, low-cost, crowdsourced framework as Wikipedia in general, but focuses particularly on these collections-based institutions.

Edit-a-thon events can be particularly helpful for institutions not only as a low-cost initiative to produce accurate information about their collections but also to include editors with diverse perspectives into this knowledge production process.  The Art + Feminism initiative sponsored edit-a-thon events to increase representation of women in Wikipedia pages. Institutions may host edit-a-thon events as a form of community engagement, allowing people with different perspectives to come together in a physical space to share research and information. These edit-a-thons may focus on a single collection or a broader effort, like creating and updating more pages related to marginalized people like women, queer people, or racially diverse groups.

Jessica BrodeFrank writes in “Crowdsourcing Metadata in Museums: Expanding Descriptions, Access, Transparency, and Experience” that crowdsourcing can produce a sense of community and ownership over the metadata and collections in a museum. Crowdsourcing gives the communities that museums serve the opportunity to contribute to the production of metadata. BrodeFrank uses the Adler Planetarium project Tag Along with the Adler as a case study to examine this crowdsourced approach in action. The project used another crowdsourcing recruitment site, Zooniverse, to practically implement the program. A survey that BrodeFrank conducted indicated that the majority of participants were white, female, and under 30 with the most participants still in middle and high school. While crowdsourcing the metadata tagging sought to diversify the perspectives contributing to its metadata, it was still found that the majority of participants were white while the integration of the project into middle and high school classrooms suggests a reason for the young ages of the participants.

I think that it would be worth it for any small cultural institution or museum to create a GLAMwiki project simply to extend research and visibility of an institution beyond a likely small staff.  Organizations like the Pennsylvania German Cultural Heritage Center in Kutztown, Pennsylvania or the Preservation Society of Newport County in Rhode Island would stand to benefit from creating a GLAMwiki project. I use these two examples simply because I have interned with them in the past, but I believe that this could be applied to any other small, local institutions. I am not sure if there are certain requirements that must be met to be added to the list of GLAMwiki projects. I could envision that there may be certain requirements that these small institutions may not be able to meet, but I believe that creating a crowdsourced project may help these institutions inform a broader public about their collections.

Museum Fun: Games and Humor

The museum’s primary objective since its inception is to educate and provide a space where its visitors can contemplate, reflect, and learn about the art, objects, or artifacts that it displays. Since Enlightenment and nationalist efforts of the late eighteenth to nineteenth centuries that established museums to create educated citizens, people began to treat the museum as a leisure activity. In the 21st century, museums’ challenge is to find a balance between leisure and accessible education without confining the museum to another form of entertainment in the modern attention economy. Despite a desire not to be just another contributor to the attention economy void, it is also important for museums and cultural institutions to not take themselves so seriously that it alienates them from broader society. The goal of the museum should be to connect to a wide audience, not just academics or museum professionals.

Screenshot of Anthropeum Game, https://anthropeum.com/.

The most successful museum “games” or educational programming are those that invite close-looking or segue neatly into formal analysis. A person does not need to be a student or expert of art history to look closely. This may be as simple as a scavenger hunt in the museum or an interactive tour where a docent asks visitors to describe the art in front of them. Virtual games are also a beneficial way to connect with an audience outside of the museum space. Activities like Anthropeum’s time period and geographical guessing game is an especially great example of a game that is both fun and informative, although it does require some knowledge of art and art history to play successfully. During our discussion after playing the Google Arts and Culture games, we determined that the most engaging games had scoring systems, virtually recreated an artistic process, and interacted with the art beyond superficially including it as an image with a caption. Games have the potential to be fun, engage visitors, and encourage close-looking, but they should be thoughtfully implemented to successfully enhance visitor understanding rather than be a distraction.

3D Modeling: A New Frontier in the Field of Digital Art History

Three-dimensional modeling is a relatively recent addition to the field of digital art history that include a range of experiences like creating facsimiles of objects or mirroring embodied experiences with virtual reality. Amy Jeffs and Sarah Kenderdine explain these new frontiers in their respective articles, “Digital 3D Modeling for the History of Art” and “Embodiment, Entanglement, and Immersion in Digital Cultural Heritage.”  Three-dimensional models are also a fun and interactive method of displaying objects in a collection, which we can see in the Smithsonian’s X3D collection. Finally, I learned how to create these digital three-dimensional models using photogrammetry with the platforms AgiSoft and Sketchfab.

Beyond being a more interesting method to interact with digital objects in a collection, three-dimensional models also provide greater access to an object. In class, we looked at at an Apollo 11 space suit in the Smithsonian Museum’s X3D collection. The viewer can look at the suit from all different angles, including areas concealed in a typical gallery exhibit. For example, the user could manipulate the view of the model with the mouse to see the back of the suit and even the soles of the boots. It was also helpful to zoom in to read notes stitched into the arm of the spacesuit. In this sense, it gave the viewer greater access to the object than just a few standard photographs that museums typically use for their digital collections.

Jeffs expands on this idea that three-dimensional models can enhance art history education and object-based analysis. She uses the example of a project concerning the reproduction of miniature pilgrimage tokens to explain how the photogrammetric models can communicate important information about their production. The actual data required for photogrammetry, the geospatial data collected by the photographs required to perform photogrammetry, document important information that may be used to identify other historical works cast from the same model. Pedagogically, the reproduction of these tokens also recreates how they would be handled, touched, and experienced by medieval pilgrims—a beneficial, interactive educational experience.

The interactive New York Times article from 2018 written by Melena Ryzik exhibited some of David Bowie’s most memorable outfits using three-dimensional modeling. Ryzik and the producers’ effectively used three-dimensional modeling techniques to communicate to the viewer how these spectacular outfits would have fit Bowie. The 360-degree view of the outfit communicated a sense of embodiment beyond two-dimensional pictures in a catalogue. The viewer cannot interact with the three-dimensional model beyond the path of the article, however, meaning that the model can only be viewed within the prescribed path of rotation. The three-dimensional models included in this article are enhance the written content rather than be the entire focus of the article.

With the Smithsonian’s collection, the user could determine what view he or she wanted to see rather than accepting the model’s path of rotation as in the New York Times article. The article’s failure to make views of the model customizable may be credited to the amount of storage necessary to present such models. For the sake of the article, this more permanent rendering of the three-dimensional model is the most appropriate. For a museum, however, the Smithsonian’s format that allows the user to view objects from a variety of angles is more relevant to its purpose.

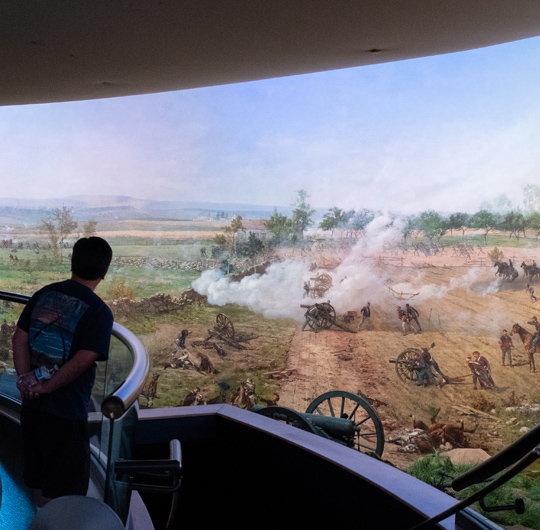
Kenderdine explores the concept of embodiment in three-dimensional models and virtual reality. While the New York Times article provides a good idea of how clothes would have looked, felt, and affected the movement of Bowie, Kenderdine thinks about virtual reality and panoramic views as a starting point for recreating embodied experiences. Unlike viewing digital three-dimensional objects in a collection, like the Smithson’s X3D collection, virtual reality and panoramas put the viewer in the center of the model. Kenderdine explains that this method of three-dimensional modeling has its roots in the cycloramas of the late nineteenth and early twentieth centuries depicting American Civil War battles. The Battle of Gettysburg Cyclorama, created by French artist Paul Philippoteaux in 1884, is an example of this antiquated entertainment still on view at the Gettysburg Foundation Museum. This cyclorama places the viewer in the center of the action, allowing him or her to explore the full circle of the painting.

Two images depicting visitors viewing the Gettysburg Cyclorama by Paul Philippoteaux, 1884. Gettysburg Foundation.

Beyond the cycloramas of the late nineteenth centuries, Kenderdine includes virtual reality as a new frontier for recreating embodied experiences in art history and museum exhibitions. Kenderdine uses the example of the exhibition Pure Land: Inside the Mogao Grottoes to explain an effective harmony of multiple digital reproductive methods to create a multi-sensory visitor experience that enhances the viewer’s understanding of this impressive historical site in China. Jeffs’ and Kenderdine’s articles explain how three-dimensional models can be used as more than mere toys in digital art history, but as meaningful methods for thoughtful user engagement and scholarly, object-based analysis.

In the workshop portion of our class this week, I learned how to make a digital, three-dimensional model using the platforms AgiSoft and SketchFab. These platforms are accessible tools to create digital, three-dimensional models. Users do need to purchase an AgiSoft subscription, though. Jeffs also identified Sketchfab as a helpful platform for sharing and storing three-dimensional models. The creation of a good three-dimensional model depends largely on the quality of photographs taken of the object for digitization. In class, we used example images of a public sculpture found outside of Person Hall on UNC – Chapel Hill’s campus. This subject was ideal for photographing and reproducing digitally due to its lack of excessive texture, its relatively matte surface, and its even source of lighting. These variables will be important to consider for my own experiment in photogrammetry.

Three-dimensional modeling is a useful method for presenting an object digitally in a collection so that it may be given a greater sense of how it occupies space. In both the David Bowie article and the Smithsonian spacesuit, the viewer can grasp how the objects take up space. With the Smithsonian collection, the user can also view how light and shadow affect the object and its colors. Three-dimensional modeling presents a new opportunity in digital art history to expand to a different form of object digitization that will support analysis and access to objects in a collection.

Connecting, Connection, Connected: Networks as Data Visualization

            At the most basic level, networks are simple to understand. If there is one connection drawn between two heterogenous data points, you have a network! Expanding this to include more data points and connections complicates this basic graph, but it also produces a useful visualization of data that can help viewers understand connections between different data points. Before diving into this subject and my own class’s experiment making a network, it is necessary to define a few terms with the help of Scott Weingart’s post “Demystifying Networks.”[1] I will also use the Dancing with the Stars network that our Digital Art History class collaboratively created with the platform Kumu as an example.

Figure 1: Image from Weingart’s “Demystifying Networks” representing a basic network.

Weingart defines networks plainly as an interlocking system of stuff and relationships, imagined in Figure 1. This “stuff” can be divided into “types” and “nodes” or “vertices.” A “type” describes the nature of the node, while the node itself is the most individual element of the network that will be fit into this web of connections. Using our Dancing with the Stars example, the individual nodes are the participants of each season. The types are the categories that the participants fall into, like “Contestant,” “Pro,” or “Judge.” These types are divided even further for the Contestant into the type of celebrity they are, like “Professional Athlete,” “Musician,” or “TV Host.” By the end of class, we also discussed the possibility of drawing further connections between nodes by indicating relationships. For example, more avid consumers of Dancing with the Stars noted that some contestants are married or in romantic relationships with each other or that some are siblings. The product of our test network resulted in a web of connections.

This “web of connections” is visually challenging to look at, a problem that Houda Lamgaddam, et al. examine in “Perceptual Effects of Hierarchy in Art Historical Social Networks.”[1] In this article, Lamgaddam et al. explain that network viewers prefer hierarchical rather than “force-directed” networks. The article concludes that hierarchical network graphs reduce the “cognitive load” on the user. I could see these forces at work within my own experience with Benjamin Zweig’s “A Universe of Artists” which he created based on the available Wikidata of artists. Zweig’s project is impressive in its scope. It names all artists with Wikipedia pages and connects them to other artists who are linked in their page.

            While we did not input nearly as much data into our shared Dancing with the Stars Kumu network, the force-directed display creates a similar “cognitive overload” to Zweig’s “A Universe of Artists.” Because the data set for the Dancing with the Stars network is significantly smaller, the user can still see the individual nodes. Looking at Zweig’s “Universe of Artists” is much more overwhelming with this massive dataset, causing it to look like an indistinguishable mass of data.

Figure 2: An image of the Kumu network Dancing with the Stars, created collaboratively in the Alt-Methods: Digital Art History class on October 29, 2026.

Figure 3: Benjamin Zweig’s A Universe of Artists. https://bzweig633.github.io/universe-of-artists/.

The hierarchical network instead organizes nodes and connections, also known as “edges,” like a family tree so that connections can be seen linearly. This hierarchical network, however, may be better suited for some data sets more effectively than others. Hierarchical networks may make the most sense when there is a downward or upward relationship between the nodes rather than multiple elements connecting different nodes. In a family tree, connections flow in one direction, from parent to child. In our Dancing with the Stars example, we made connections of nodes based on their status as a contestant, professional, or judge. We also thought it would be interesting to chart connections between individual nodes, like marriages or relationships between participants. This would create another element to complicate the network and make a hierarchical network using this dataset more difficult to accomplish.

Placing this method of data visualization within the greater themes of this semester, the creation of networks may be the most direct method of data visualization. Creating networks is a form of macroanalysis, that, by its nature, will necessarily draw the researcher’s or user’s attention to the pattern created in the data through the connections of nodes to elements.

Timelines visualize time linearly, limiting the variables that can be used. Throughout this past week, I have worked on a timeline related to a term paper that I am writing about the architect Owen Jones. You can find a link to view “The Education, Life, Work, and Travels of Owen Jones” below. This timeline charts the major life events of Jones including his education, significant travels, and most influential publications.

Link to “The Education, Life, Work, and Travels of Owen Jones”: https://cdn.knightlab.com/libs/timeline3/latest/embed/index.html?source=v2%3A2PACX-1vSXAwJ_aNWmPgGYUohiWkg7vZvGM5DIyioO1DJBr1Xq_jUPfowFH70tpA3vI8K2TjSNCw92S_HnBmiV&font=Default&lang=en&initial_zoom=2&width=100%25&height=650


[1] Houda Lamgaddam, et al., “Perceptual Effects of Hierarchy in Art Historical Social Networks,” Digital Humanities Quarterly vol. 16 no. 1 (2022).


[1] Scott Weingart, “Demystifying Networks,” Scottbot.net, December 14, 2011, https://www.scottbot.net/HIAL/index.html@p=6279.html.

Timelines in Digital Humanities

            A few weeks ago, I ventured into spatial mapping using Google’s custom maps. This week, I tried out mapping across space by creating a timeline in Timeline JS. The program is simple to use with a pre-formatted Google sheet where the user can simply plug-in the information he or she would like to plot on their timeline. Users can add a variety of media to the timeline including image and videos in the form of jpg or mp3 link addresses. Unfortunately, this means that downloaded media cannot be attached, at least in this basic version of Timeline JS.

            My first experiment with this digital tool is very brief, although a more extensive timeline is coming soon! For this first experiment, I included a few works of art featured in the Philadelphia Art Museum as part of the exhibition A Nation of Artists: 250 Years of American Art. The pre-formatted Google Sheet is user-friendly, but Timeline JS’s inability to use downloaded images was a challenge since the Philadelphia Museum of Art does not provide an image address that can be easily copied. Instead, I used a reverse Google image search to find image addresses of the works included on a different website. The result is a four-object timeline plotting four works of art in the exhibition accompanied with an image and a brief description. You can check out this preliminary timeline below.

https://cdn.knightlab.com/libs/timeline3/latest/embed/index.html?source=v2%3A2PACX-1vS0ju4fuuXWckwIizWQE6qLyMbDz5Lwl0CEjF2UMFUlFfiRrWlbxmu_9aiRF1IIWqwwwj87DoiiidSg&font=Default&lang=en&initial_zoom=2&width=100%25&height=650

Timelines in Digital Humanities

            For class this week, I also explored other digital humanities projects’ that used timelines. The timelines in these projects suited each purpose well, whether the objective was to describe a specific historical figure or event for close-reading or for creating an interactive browsing interface.

            “Mina Loy: Navigating the Avant-Garde” was a project led by scholars in English literature from Davidson College, Duquesne University, and the University of Georgia. Spanning several years with the help of a grant from the National Endowment for the Humanities, the project seeks to examine the life and work of Mina Loy, an influential figure in the avant-garde movement. The timeline specifically is successful for explaining Loy’s life and work by separating it into phases based on places that she lived. From this project, I can see how using a timeline is helpful to visualize an historical figure’s life, especially for one who moved to different places throughout his or her lifetime.

The project integrates a variety of media throughout the interactive project, including images and audio. One shortfall of this project is broken or inactive links. I found myself encountering them throughout the timeline feature when an image could not be properly displayed. This reality indicates how digital humanities projects require a sustainability plan and constant maintenance to continue to function beyond the construction of the project.

            The project leaders, Suzanne Churchill, Linda Kinnahan, and Susan Rosenbaum, also published a reflection about the project on the platform Visualizing Objects, Places, and Spaces: A Digital Project Handbook.[1] In this reflection they described the process of collaboration across institutions and disciplines, the workflow timeline, and funding from the NEH and their respective institutions. In the section “Challenges & Opportunities,” they emphasized the need to keep the project focused and to limit—to a degree—the extent of the project or a particular aspect of the project to avoid spending too much time and energy on a part that may not be necessary. Overall, the project aligns well with other blog posts and articles that we have read throughout the semester that outline the main tenets of creating a digital humanities project. The Mina Loy project, like others, required collaboration, realistic objectives, and clear strategies for achieving those objectives while also allowing flexibility and space for discovery and innovation.

            Some other examples of timelines used in a digital context include “Mapping Austro-fascism” from Campus Medius, the Metropolitan’s “Heilbrunn Timeline of Art History,” and Google Arts & Culture’s Time Explorer.

“Mapping Austrofascism” takes a close-looking approach to a specific weekend in May 1933 the Simon Ganahl, the project leader, posits was highly influential in spreading fascism in Austria. This project combines spatial mapping with a timeline, with the timeline also indicating the duration of the events. Examining each event throughout this weekend in Austria paired with text and media clarifies and paints the user a detailed picture of the context required to understand the significance of each even throughout this brief moment in history.

A screenshot of “Mapping Austrofascism” with a view of the timeline, map, and additional information and media supporting the explanation of this event.

While “Mapping Austrofascism” and “Mina Loy: Navigating the Avant-Garde” involves extremely close looking, the Metropolitan’s “Heilbrunn Timeline of Art History,” and Google Arts & Culture’s Time Explorer is better suited for the casual browser. The Metropolitan’s “Heilbrunn Timeline of Art History” is separated thematically and geographically and allows the user to browse the Met’s digital collections. Each timeline is accompanied with an essay describing the theme of the timeline, and the timeline also indicates influential events that occurred in the region. The Google Arts & Culture’s Time Explorer is even more general, spanning across geographies and digital collections to create a more comprehensive timeline complete with images, a link to the holding institution, and details about specific works of art. With Google’s Timeline, I am curious to know how works across digital collections are chosen. I assume that the images presented are meant to be for public use.

Throughout this week, I discovered how timeline are both helpful for browsing and for close-looking. Timelines can help track and divide moments throughout an historical figure’s life, like that of Mina Loy, or the specific events over the course of a day, like the “Mapping Austro-fascism” project. On the other hand, timelines can also be fun and interactive tools provided by institutions to give the user another creative way to interact and browse through their collections. Timelines, like maps and other forms of data visualization, are helpful to visualize time while also increasing user engagement with a digital humanities project.


[1] Suzanne Churchill, Linda Kinnahan, and Susan Rosenbaum, “Mina Loy: Navigating the Avant-Garde,” Visualizing Objects, Places, and Spaces: A Digital Project Handbook (PubPub, January 14, 2021), https://handbook.pubpub.org/about.

The Fate of Art and Art History in a Data-Dominated World

            This week we read an evaluation of different methods of visualizing data—their strengths and their flaws. Catherine D’Ignazio and Lauren Klein take on the question of authority and perspective in data visualization in a chapter in Data Feminism while Nathan Yau explains the numerous ways in which data visualization can be construed while still maintaining its aura of objectivity in “Defense Against Dishonest Charts.”[1] Eryk Salvaggio and Victoria Turk analyze how biases and gaps in data appear in one of the newest forms of data visualization, artificial intelligence (AI), in their result reports for experiments they had conducted using AI.[2] Kaylee Alexander and Emily Lawhead posit a more optimistic view of AI by placing it within the context of other media inventions like photography. These various articles all grapple with what it means to live in a world not only inundated with data, but also with generative technology that can process data by itself.

            Ignazio and Klein’s article is a good place to start to challenge this idea of rational data visualization. Sure, numbers and statistics can be collected objectively, but the story they tell can be communicated powerfully—and even emotionally! —to the viewer. Take Periscopic’s data visualization of US gun deaths in 2013, an example used by Ignazio and Klein. The data collected and displayed are quantitative, the amount of people killed by guns and the number of more years these victims could have lived had they not been cut short, but it is communicated in a way that allows the viewer to better visualize this loss. Unlike a chart or plot of the amount of mass shootings, this graph focuses on the victims rather than the crime and associates the number of people killed with the amount of time they could have lived. Taken together, this visualization of data illicits an emotional reaction.

            Yau describes in “Defense of Dishonest Charts” how data—objective, quantifiable data—can be visualized to prove one point better than another. Laying out the basics of data visualization and good data visualization practice in “Representing Data” in the book Data Points: Visualization That Means Something, in this article, Yau describes how data can be manipulated through different elements of data charting and how to be a vigilant consumer of this data. His article is written with the assumption that data visualization features like graphs automatically signal to readers a sense of objectivity.

            Artificial intelligence generates images and responses from massive amounts of data scraped from across the internet. Salvaggio and Turk use artificial intelligence image generators to explain how artificial intelligence processes this data to create the most “average” of images in response to prompts, and in consequence reveal both gaps and biases in data. Salvaggio explains that the images produced by artificial intelligence are not so much pictures as they are representations of data. Any weirdness or distortion in images, like those produced in the images of people kissing, is attributed to a lack in adequate data to create these images. In Salvaggio’s case, a bias was revealed that showed predominantly single-race, heterosexual couples. His study was run in 2024, so the picture-producing ability of AI has likely increased dramatically, but it still likely features similar biases.

            Turk’s article on AI image generation focuses exclusively on generated images that reproduce stereotypes of cultures and gender ideals. The article artfully incorporates interaction with the different images produced by AI and highlights common themes across prompts. For example, the inclusion of chopsticks in images produced of “Chinese food.” Turk’s article demonstrates how AI is like an echo chamber of western stereotypes of other cultures. A fact that Ignazio and Klein also address in their article about unobjective data visualization. Like Turk, Ignazio and Klein reveal how the authority of the west, best embodied in a white male perspective, underlies most data visualization tactics. In this way, these stereotypical images of cultures produced reveal how western assumption of other cultures—eerily reminiscent of nineteenth-century imperial colonial efforts to visualize and display non-western cultures—is still largely at work within existing data.

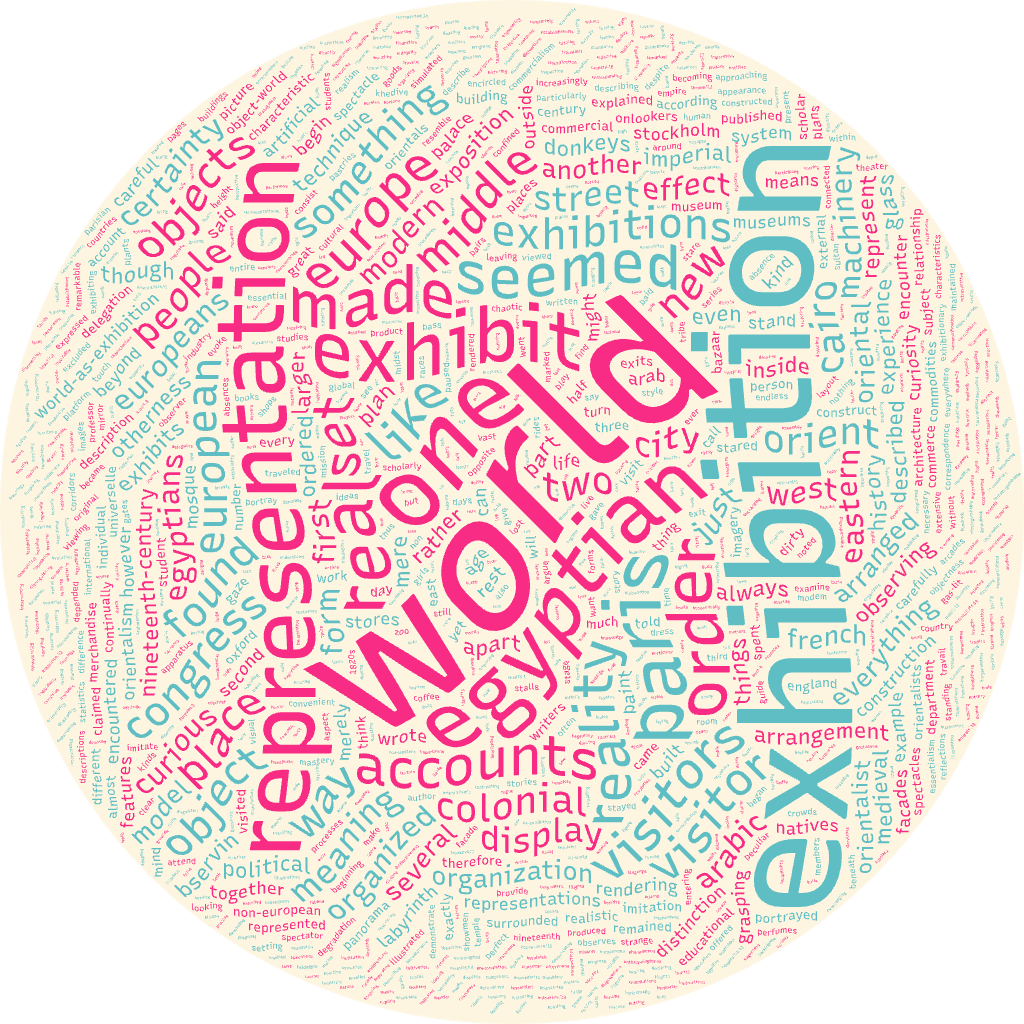
            While I did not use AI images to visualize data, I used the more accessible Tag Crowd to create a visualization of words used in Timothy Mitchell’s “Orientalism and the Exhibitionary Order.”[3] The word cloud did extract words that communicated the main themes of Mitchell’s seminal text including “world,” “exhibition,” and “representation.” A closer look at words used less frequently, like “Egyptian,” “European,” “objects,” “colonial,” and “nineteenth-century” may even reveal to a person who has not read the text before a general idea of what it is about. In this way, I think that a word cloud to visualize quantitative data, the frequency of a word used in a given text, is helpful more as a pedagogical tool or method to communicate themes of one’s research.

            Turning to Alexander and Lawhead’s article “Data and Discontent,” they argue that art created with artificial intelligence will be the way of the future and that the fear and anxiety produced by its entrance on the global stage will be abated within time like that of photography. As a class, we discussed several flaws to this idea. Despite the human required to create prompts, it seems as though the hand of the human is largely out of the loop. Can a person really make art from a mass of art-as-data available freely to be consumed and processed by AI models? The answer we concluded with was a resounding no.

            Despite its claims to objectivity, data visualization is anything but. This has only been amplified with the advent of artificial intelligence. In a world increasingly flooded with data, it is the now, more than ever, the responsibility of the consumer to critically analyze how to use this data.


[1] Catherine D’Ignazio and Lauren Klein, “On Rational, Scientific, Objective Viewpoints form Mythical, Imaginary, Impossible Standpoints,” in Data Feminism (MIT Press, 2020).; Nathan Yau, “Defense Against Dishonest Charts,” accessed October 25, 2026, https://flowingdata.com/projects/dishonest-charts/.

[2] Eryk Salvaggio, “How to Read an AI Image,” Cybernetic Forests. Last updates August 2024. https://www.cyberneticforests.com/news/how-to-read-an-ai-image.; Victoria Turk, “How AI reduces the World to Stereotypes,” Rest of World, October 20, 2023, https://restofworld.org/2023/ai-image-stereotypes/.

[3] Timothy Mitchell, “Orientalism and the Exhibitionary Order,” in Grasping the World (Routledge, 2004): 442-460.

Annotations and Transcripts: The Significance and Utility of Thick Data

            Oral histories and videos are sources that can be especially useful for art history. Oral histories are an important source for collecting stories from people who have first-hand experience, and videos may be the medium of an artwork or a method of its documentation. Oral histories are great primary sources that often capture different information from written sources. It seems that oral histories require the researcher to consider more thoughtfully who the interviewee is, who the interviewer is, and what questions are being asked compared to written and spatial or map sources. This week, we reviewed how to practically refine oral transcripts and annotate videos to make these sources more accessible for research.

Matthew J. Westerby proposes in “Annotating Upstream: Digital Scholars, Art History, and the Interoperable Image” that scholars should create their own metadata from publicly available images and sources. Westerby explains that IIIF annotations, the International Image Interoperability Framework, are useful for standardizing formats of images and videos for accessible sharing, but they may not suit the needs of the scholar using them. To solve this problem, he suggests “annotating upstream,” or, in other words, the scholar adds his or her own annotations in addition to the data received by the institution providing the image. This “knowledge-de-centralization” mitigates institutional bias and allows for individual scholars to personalize the media to their own needs. Making these annotations publicly available can create media with what Westerby defines as “thick data,” or digital images with a lot of description added by multiple people on top of the IIIF provided by the institution. Rather than accepting the “downstream” annotations, the scholar can enhance the context surrounding an image.

In the workshop session of class, we practiced annotating videos. The annotations for images that Westerby describes in his article can also extend to videos. In class, we used a clip from The Cotton Club, the 1984 film directed by Francis Ford Coppola, to practice writing annotations.1 These annotations focused exclusively on the set design and cinematography of the scene. Another scholar may be interested in a different aspect of the film, like the music or dialog. Annotations created by different people for different purposes would create the “thick data” that Westerby describes. Public annotations on digital content create a new area for scholarship generation and analysis.

I also experimented with annotating video—albeit on a much simpler scale. I refined a short clip from the 1964 stop motion Christmas television special, Rudolph the Red-Nosed Reindeer, produced by Rankin/Bass Animated Entertainment with the online platform Panopto.2 Panopto allows the user to correct the dialog transcript for captions, post interactive discussion posts, and notes. The discussion posts and notes are timed with specific moments in the video, making these features especially helpful for internal research note-taking or film class discussion questions. I included notes that explained the commercial origins of the story, song, and movie of Rudolph the Red-Nosed Reindeer alongside individual frames in this short clip. While I added notes contextualizing the origin and creation of the Rudolph story, in an attempt to reveal the ultimately commercial basis of this classic Christmas tale, another scholar may be interested in the technical processes of stop motion animation. In this way, we would each create different annotations for the same digital object, creating “thick data.”

Rudolph the Red-Nosed Reindeer, Rankin/Bass Entertainment Animation (1964)

By pressing the right upwards arrow button, the user can navigate to Panopto, where he or she can view my video annotations.

 Although I do not have videos or oral histories pertaining to my research right now, Panopto will be useful in the future if I need auto generated and editable captions as well as timed video annotations. Interfaces like Panopto are accessible, practically helpful, and fairly intuitive for the scholar to use for producing and refining oral history transcripts and videos. Panopto’s editable captions and notes are especially helpful for the internal research process rather than a public-facing final “project.”

The Institute of Museum and Library Services provides a thorough guide to beginning an oral history project. Linda Shopes’ article “Making Sense of Oral History,” a part of the Institute’s “Oral History in the Digital Age” site, delineates features of oral histories that should be considered by the scholar who is using or creating them. Some of these nuances include recognizing who is being interviewed, who the interviewer is, and what questions are being asked. She also reminds the reader that oral histories are based on people’s own subjective experiences and recollections, so they should not be accepted as fact. She uses several examples throughout this article to illustrate her points. For example, she provides different perspectives on the same experience within one family, and the reader can identify how each interviewee’s answers are formed based on their role within the family (e.g. father, mother, and daughter). She also uses the example of a former enslaved woman interviewed by a young. Black man in comparison to a white, female social worker. In this interview, the reader can see how the interviewee is much more candid with the Black interviewer in comparison to the subdued, practiced answers for the white woman. These considerations outlined by Shopes led me to think about how I should use oral histories in my future research, knowing that they are important but also subjective, living documents.

I think that creating, refining, and using oral histories for research is a promising direction for a more “digital” art history. If oral records exist documenting artists and their art, they will be a relevant and useful primary source to incorporate into research. Annotating images and videos also generate greater scholarship and context for non-experts of the image. This allows scholars to build up institutionally designated IIIF to provide more context or scholarly perspectives on a single image or video. Resources like Panopto can facilitate this scholarly annotating process. Although transcripts or annotations may primarily be used by scholars for their individual, internal research projects, making this additional data available and usable to the public is another method of scholarship-sharing. Whether a scholar’s annotations result in a polished, public-facing digital project or not, the creation of thickly descriptive, publicly accessible metadata still supports future scholarship and creative curiosities.

1The Cotton Club, directed by Francis Ford Coppola (Orion Pictures, 1984). 2Rudolph the Red-Nosed Reindeer, directed by Larry Roemer, produced by Rankin/Bass Productions, aired December 6, 1964 on NBC.

Mapping the Relationship Between Art and Place

Spatial mapping is an old but still useful and relevant tool in art history. This week, after reading about and looking through different art historical mapping projects, we had the chance to experiment with some accessible digital mapping tools ourselves, including Google Maps and JS Story Maps. With advances in technology, digital mapping is an accessible and educationally rewarding tool in the field of art history.

            In Béatrice Joyeux-Prunel’s article “Digital Humanities for a Spatial, Global, and Social History of Art,” she explains that art historians’ interest in the spatial relations of art is not new—in fact, it dates back to the time of Giorgio Vasari.[1] The identification of art with particular places helped to define the cultural identity of countries while also advancing nationalist agendas.[2] In recent decades, spatial mapping has become an analytical tool facilitated by advancing digital technology. Joyeux-Prunel offers a tactical introduction on beginning, organizing, and executing digital mapping projects. Ultimately, Joyeux-Prunel explains that mapping in art history is useful for education and scholarly research.

Earlier in the semester, we read “The Digital Art History as the Social History of Art: Towards the Disciplinary Relevance of Digital Methods” by Paul Jaskot, who argued that digital tools for macroanalysis would become the norm for art history research in twenty-first century.[3] In this article, he used the example of a digital mapping project of a German design firm that allowed him to extract an unusual pattern in the firm’s construction habits. He used this example to illustrate his point that macroanalysis with the aid of digital tools can highlight patterns that a human may not be able to recognize by just reading.

The Jaskot and Anne Kelly Knowles article from this week, “Architecture and Maps, Databases and Archives: An Approach to Institutional History and the Built Environment in Nazi Germany,” highlight how a mapping project may help advance scholarly research.[4] Rather than the end goal being an interactive, educational digital humanities project for the public, this project served to help Jaskot and Knowles understand the construction and building habits of the Nazis running Auschwitz for a written research paper. By mapping and tracking the construction of the buildings, Jaskot and Knowles revealed a pattern of architectural instability and dynamism rather than the stable, unchanging, presence that the Nazis wanted to communicate.

While Jaskot and Knowles’ digital mapping project was not permanently available to the public, other digital mapping projects like Columbia University’s Mapping Gothic France, Boyeux-Prunel’s Artl@s Geomap of Paris salons, and the University of Iowa’s Campus Cornerstones. My personal favorite is Columbia University’s Mapping Gothic France because of its immense scope, images, and user features. Mapping Gothic France pinpoints where a multitude of Gothic cathedrals are located throughout Europe, not limited to just France. When a use selects a single cathedral, they are offered an interactive floorplan in which arrows provide images of the church from different viewpoints. The panorama is also very detailed and helpful for both the casual browser and the interested scholar. The depth of Mapping Gothic France can be attributed to the years dedicated to this project and advanced funding through a grant.

Although more limited in scope compared to Mapping Gothic France, the University of Iowa’s Campus Cornerstones offers an interactive, archival-based account of the buildings on campus throughout university history. Combining both map and timeline features, Campus Cornerstones allows users to see where old buildings used to be located and what stands in their place now. From this project, users can understand the architectural history of the University of Iowa and how it evolved over time.

I tried my own hand at basic digital mapping in throughout this week, as well. I came into class this week with some experience in both Google Maps custom maps and JS Story Maps. In Google Maps, I had identified where monumental sculptures were located in a 1974 public sculpture exhibition, Monumenta, throughout the city of Newport in Rhode Island. I had used JS Story Maps for an Italian project during my undergraduate degree to map out a theoretical road trip across Italy. In class this week, I began playing with a few maps, like a Google Map identifying places that I visited often when I studied abroad in Rome and a JS Story Map identifying a few centers of Pennsylvania German folk art. Through this experimentation, I appreciated how the intuitiveness of these interfaces. These low-stakes tests also prepared me for a project more related to a different research project that I am working on.

I decided to make a map of twenty objects in Google Maps that Owen Jones identifies in his 1856 book The Grammar of Ornament. This map does not include all the illustrations in the book, but I attempted to choose one illustration that had the clearest location from each chapter. I excluded any illustrations from his chapter on designs from nature and instead opted to select two illustrations of column capitals from the Egypt chapter. I realized soon after I began inputting the location information in the map that some location’s names had not remained the same. For example, the “Memnonium” that Jones refers to in Egypt, is now referred to as the “Ramesseum” to refer to an ancient tomb. There were also a few items from India and Persia that Jones accessed from libraries and museums in England rather than their place of origin. He also uses racist and culturally reductive language, using the term “savage” to refer to indigenous tribes across continents. Because he used this term to name a chapter, I included it in the description for that illustration, but I made a note in the map description warning any potential viewers about the presence of this racist, antiquated language.

After reading the articles about metadata last week and my own experimentation with mapping this week, I realize that there is also a healthy amount of ambiguity that scholars must contend with. I think that approaching uncertainty with transparency about unknown or ambiguous information is the best way to present information without construing data. Mapping is still a useful and relevant tool in art history to extract patterns from large amounts of data and allow users to understand a bigger picture of the relationship of art with place and time.


[1] Beatrice Joyeux-Prunel, “Digital Humanities for a Spatial, Global, and Social History of Art,” In The Routledge Companion, ed. Kathryn Brown (Routledge, 2020), 88-108.; Joyeux-Prunel, “Digital Humanities,” 88.

[2] Joyeux-Prunel, “Digital Humanities,” 89.

[3] Paul B. Jaskot, “The Digital Art History as the Social History of Art: Towards the Disciplinary Relevance of Digital Methods,” Visual Resources 35:1-2 (2019): 21-33.

[4] Paul B. Jaskot and Anne Kelly Knowles, “Architecture and Maps, Databases, and Archives; An Approach to Institutional History and the Built Environment in Nazi Germany,” The Iris (February 15, 2017).

Defining Ambiguity: The Challenge of “Clean” Data in Art History

            The word “data” seems like it strikes fear in the hearts of all scholars in the humanities, especially in a field like art history. While it would be easy to say that the future of art history is inevitably digital, I think that also discounts the work that good data analysis pioneered by art historians can do for the field. Earlier in the semester, we learned how data analysis can inspire creative digital humanities projects and digital collections. These efforts ultimately make art, history, and knowledge more accessible to those around the world. Shouldn’t that be the goal of any good scholarship?

            I had this in mind as I read our assigned articles this past week discussing exactly how to extract this good, clean data that could make knowledge an scholarship more accessible. It turns out, the answer is not quite as clear! Scholars disagree on exactly how to organize data and institutions abide by a certain standard of sharing their data. We saw these opposing views of data organization confronting each other in Susan Elizabeth Gagliardi and Constantine Petridis’s article, “Mapping Senufo: Making Visible Debatable Information and Situated Knowledge,” and Karl W. Broman and Kara H. Woo’s, “Data Organization in Spreadsheets.”[1]

            The main difference between Gagliardi and Petridis’s article and Broman and Woo’s is how they treat ambiguity. Ambiguity and uncertainty is unavoidable in art history and surfaces often with ancient art or non-western art, like the Mapping Senufo project which involved organizing West African art. For Gagliardi and Petridis, they struggled to adequately assign labels to pieces of art that had an unclear artist or origin, owing to the fact that there may be multiple spellings or names for the artist or locations. Broman and Woo suggest that every cell in a spreadsheet should be filled, even if the information is unknown, and to have a standardized spelling or phrase to describe the same piece of data. This is helpful to eliminate inconsistences across spreadsheets, but it may not be truly reflective of the actual data.

In the case of the Mapping Senufo project, assigning a standardized name to an artist or location eliminates the ambiguity and reduces its cultural complexity. This elimination of ambiguity asserts that only one name is correct and any other spellings are wrong, imposing this binary worldview and a misleading authority of certainty. If a date or exact artist’s name is unknown, it would be dishonest to represent an approximation or educated guess as authoritatively true.

Including this ambiguity of the unknown is not conducive to using the data for further analysis, though. In class, we saw how one museum, the Tate in London, combatted this in their publicly available API. The Tate includes a qualitative column next to their quantitative information to explain how and when they simplify their data to format it best for analysis. For example, if a painting was created circa 1840 to 1850, they would include that information in the qualitative column, while a more concrete date, “1840,” is added in the quantitative column. In this way, the museum can be transparent about the information they have while also providing the best approximated information for data analysis.

The key takeaway that I gleaned from this topic of data and data analysis from a humanities perspective is that ambiguity is ok—and necessary—in a field like art history. In an environment where data analysis seems to be an exciting new path towards future art historical scholarship, it may be necessary to artificially “clean” ambiguous data for analysis. As long as the data originator is transparent about ambiguity and uncertainty in their data, I think that it can be responsibly simplified for helpful data analysis.

Text Analysis

            Text analysis is another method that can be helpful for humanities research, including art history. In class this week, we reviewed the Google N-Gram Viewer and the Voyant text analysis software. Even simple functions like counting word frequency or word placement can be helpful for pinpointing main ideas, subjects, or terminology that occur frequently across a corpus of documents.

             For understanding broad trends across all published works, I think that the Google N-Gram word frequency tracker is especially useful. Like most digital tools used in humanities research, this tool identifies patterns, but it cannot provide an explanation for that discovered pattern. For example, in class we discussed how certain words may simply appear less in the 19th century simply because there were less publications compared to the most recent decade. This tool may be helpful for tracking the popularity of certain ideas or concepts, but it is still just a starting point for deeper analysis.

            Voyant seems especially useful for scholars who have several text documents to sift through. Using an example article from a library science course, I found phrases and terms that recurred often throughout the text. It was helpful to see phrases that occurred the most often and where they appeared throughout the text.

            For a research paper, I am examining the book plates in Owen Jones’s 1856 book, The Grammar of Ornament. I think that text analysis with Voyant will be appropriate to use for this project. Before using the Voyant application, I would need to ensure that the PDF of Jones’s digitized work has been properly OCR’d so that it recognizes the text. Then, I can use Voyant to see what words and phrases that Jones uses frequently. This can give me a better idea, not only of Jones’s work, but also of the language that his contemporaries may have used in related texts.

            To further explore Jones’s The Grammar of Ornament, I am considering creating a more comprehensive searchable collection of the book plates in the text. I began this project by uploading ten book plates into CollectionBuilder’s GitHub. To continue this project, I would need to add to the metadata organized in a Google Sheet, including the standard “tombstone” data along with the file identifier. This data can then be converted into a CSV file to be uploaded into CollectionBuilder. This project would not be possible without accessible, data analysis tools.

            Incorporating digital tools into the field of art history does not reduce the role of the scholar. In fact, they can aid in analysis and increase accessibility to this scholarship. There are also creative aways to maintain art history’s ambiguity or at least methods to maintain transparency. Through clean data and data analysis, art historians can integrate digital tools into their methodology, continuing make their scholarship more accessible and innovative.


[1] Karl W. Broman and Kara H. Woo, “Data Organization in Spreadsheets,” The American Statistician 72, 1 (2018): 2-10.; Susan Elizabeth Gagliardi and Constantine Petridis, “Mapping Senufo: Making Visible Debatable Information and Situated Knowledge,” in Perspectives on Data, ed. Emily Lew Fry and Erin Canning (Art Institute of Chicago, 2022).

Digital Art History in the Undergraduate Classroom

            Lauren Kilroy-Ewbank’s article “Doing Digital Art History in a Pre-Columbian Art Survey Class: Creating an Omeka Exhibition Around the Mixtec Codex Zouche-Nuttall” unites the themes that we have been discussing as a class since the beginning of the semester.[1] Within her experimental integration of digital art history into a Pre-Columbian art survey class, Kilroy-Ewbank notes the challenges, successes, and potential for using a digitally centered project as a part of her pedagogical methodology. We can see the product of educating students in building digital repositories through interfaces like The William Blake Archive. Introducing digital tools to practice digital art history earlier in art history students’ educations will facilitate new and innovative projects.

            The objective of Kilroy-Ewbank’s project for her students was to create an interactive digital exhibition investigating various characteristics of the Pre-Columbian Mixtec Codex Zouche-Nuttall. Kilroy-Ewbank explained that students often had trouble understanding the pictorial nature of written Mixtec communication. She saw the creation of this interactive exhibition as a method for students to meaningfully interact with the piece in order to achieve greater comprehension of the work as well as Mixtec art and communication more broadly. By dividing students into teams to learn how to create their exhibit from a new digital tool, Omeka, she made collaboration necessary to the classroom rather than the more traditional research paper completed individually.

            Alison Langmeade also wrote about how digital art history encourages collaboration in her example of the University of Pittsburgh’s Visual Media Workshop (VMW).[2] Through this organization of students, Langmeade explained how the VMW allowed students to collaborate on projects together rather than conduct research in isolation. Kilroy-Ewbank’s Omeka project for her students functions in the same way. She notes that even outside the project, she encouraged collaborative research and study made possible by Google Apps suitable for sharing notes with whole classes. She also acknowledges, like Langmead and Paul Jaskot, that digital analysis is useful for macroanalysis and for finding spatial and temporal patterns in works but that it is the human’s responsibility to explain the pattern.[3] The pictorial nature of the Codex Zouche-Nuttall also lends itself to be analyzed and explained well through a digital project.

            Without knowing a lot about the Codex Zouche-Nuttall itself, its overwhelming amount of images remind me of Hieronymus Bosch’s Garden of Earthly Delights. Last week, I also mentioned Bosch’s work and the Netherlands’ subsequent digital humanity project that creates an audio-visual experience where the user can zoom in and click on details for further information.[4] I can imagine students creating a similar digital project for the Codex Zouche-Nuttall. Kilroy-Ewbank notes how students were responsible for collecting comparative images and the potential to integrate geographical or topographical data into their exhibitions. The practice of creating, arranging, and constructing a digital exhibition not only allowed students to create a unique research project to learn more about a piece of Mesoamerican history, but it also introduced undergraduate students to digital tools to disseminate scholarship in an age inundated with digital images.

            One challenge that Kilroy-Ewbanks noted was students’ frustrations with using Omeka, a completely new tool for them, and the ensuing awkwardness or inconsistencies that manifested in the resulting exhibition. I am experiencing similar frustration technological frustration while using the digital repository-building tool, Collection Builder through GitHub. During my undergraduate studies, I had taken classes that did involve aspects of digital humanities and digital art history, but I mostly participated in the research and scholarship rather than the digital construction.

While studying abroad in Rome, Italy, I worked with fellow students in a Museum Studies class to create a digital exhibition of fake art confiscated by the Carabinieri de Tutelo di Patrimonio (the site is still active if you would like to check it out! Deception by Design: Lessons from Forgeries). A graduate student constructed the digital exhibition, while the undergraduate students researched and wrote about the objects. In her class, Kilroy-Ewbanks required the students to also be involved in the maintenance of metadata and construction of the digital exhibition.

            The creation of digital exhibitions and repositories like The William Blake Archive are helpful for sharing scholarship with a greater public and for creating new scholarship. Kilroy-Ewbanks notes in the conclusion of her article that some of her goals for the Codex Zouche-Nuttall project included having her students learn the importance of sharing scholarship and the fact that history is created through thoughtful research and synthesis. The William Blake Archive is an early example of a digital project aimed at increasing access and generating scholarship related to the art and writing of William Blake. Starting in 1995, The William Blake Archive unites the works of Blake across several repositories and features rotating digital exhibits that highlight different aspects of Blake’s lifetime as an artist, like an exhibition dedicated to his work in Sussex for William Hayley or his drawings of the pilgrims in Chaucer’s Canterbury Tales. The William Blake Archive is a great example of the past of digital projects, but it also inspires the future for even better digital repositories.

            The William Blake Archive is not without its faults. Likely because of its long life, issues of maintenance and uniformity inevitably become issues as contributors and editors come and go. I think that as more scholars experiment with creating digital tools, upkeep and maintenance will prove to be an important factor to consider as the life of the project persists.  

            Integrating digital art history methods into undergraduate art history curriculum, like Kilroy-Ewbanks’ assigned project, allows art history to adapt to the digital world. As scholarship is almost entirely shared and produced online, it is important for students of art history to learn about helpful digital tools for their own research interests—technological frustration and all.


[1] Lauren G. Kilroy-Ewbank, “Doing Digital Art History in a Pre-Columbian Art Survey Class: Creating an Omeka Exhibition around the Mixtec Codex Zouche-Nuttall,” Journal of Interactive Technology and Pedagogy, no. 12 (February 2018).

[2] Alison Langmead, “Art and Architectural History and the Performative, Mindful Practice of the Digital Humanities,” Journal of Interactive Technology and Pedagogy, no. 12 (February 2018).

[3] Paul B. Jaskot, “Digital Art History as the Social History of Art: Towards the Disciplinary Relevance of Digital Methods,” Visual Resources 35:1-2 (2019), 26.

[4] Pieter van Huystee Film, NTR, Jheronimus Bosch, the Garden of Earthly Delights (Pieter van Huystee Film, NTR, 2016), https://archief.ntr.nl/tuinderlusten/en.html#.

Using Digital Collections: The New Frontier

            Digital collections are one of the most helpful research resources an institution can provide. Coming from the perspective of an art historical researcher, I typically arrive at a museum or cultural institution’s site knowing what I want to see. Not every museum site visitor is conducting research, though, and it is important for institutions’ digital collection searches to accommodate both audiences. Fabian Offert and Peter Bell, Dominik Bonisch, Tim Sherratt, and Mitchell Whitelaw write about new and past digital collections and interfaces that explore the potential of digital resources to effectively organize digital collection to be more user-friendly.

            Sheratt offers examples of how people can creatively use publicly available digital records in his article, “It’s all about the Stuff: Collections, Interfaces, Power, and People.” Written in 2011, Sherratt demonstrates the potential to push digital collections beyond only making them available online. One of his examples is the project “The Real Face of White Australia,” which he uses to explain how digital databases have the ability to turn records from tools of oppression to a restoration of humanity. In the case of “The Real Face of White Australia,” Sherratt and Kate Bagnall used photographs that government officials in the 19th and 20th centuries required non-white Australians—which included Chinese, Japanese, and Indian immigrants in addition to indigenous Australians—to submit so that they could re-enter the country if they traveled abroad. Because the National Archives of Australia digitized these records and made them public, Sheratt and Bagnall could use these photographs to create a searchable database and craft biographies for these people to offer a counter-history to the myth of a “White Australia.” This project demonstrated how digital records could be used analytically and to restore marginalized perspectives in history.

            Transitioning from Sherratt’s accounts of early forays into digital collection organization, Bonisch and Offert and Bell report on experiments with generative models to improve the intuitiveness of digital collections through pattern recognition. Bonisch explains an experiment using the massive, digitized collection of the Danish National Statens Museum for Kunst to create a model trained to “think like a curator.” Working in a bottom-up pattern, the artificial intelligence treats each separate piece as its own data point and gradually narrows it down based on similar visual features and metadata. Offert and Bell discuss the use of imgs.ai, an artificial tool also aimed at increasing the browse and searchability of several collections. Although it cannot search across collections, imgs.ai works with a few museums including the Rijksmuseum, the Metropolitan, and the Getty. This model begins by presenting the viewer with a random series of all the museum’s digitized images. The user can click on an individual image to see more images with similar features. In this way, the model keeps “a human in the loop” in its searches. From Sherratt’s early examples of using digital collections to create interactive, analytical databases, Bonisch, Offert, and Bell take the technology forward another step with generative technology creating and recognizing patterns between images.

            Exploring digital collections is essential for any student of art history. In my experience, the digital collections of the Metropolitan, Philadelphia Museum of Art, and the Rijksmuseum are particularly user-friendly for researchers—especially those that have a very clear idea of what they are looking for. While conducting research for my undergraduate thesis about a wardrobe with German decorative influences, I needed to search the collections of a few Swiss and German museums. From a book detailing the Historisches Museum Basel’s collection, I found the accession number of a wardrobe that I believed would be particularly helpful to include in my work. The collection site proved to be very accurate for finding that particular wardrobe. When I used the keyword “wardrobe” to search for more examples, the results were limited. The case was even more drastic in the collection search for the Bayerisches National Museum. This digital collection could only recognize German words (Fig. 1 and 2).

Search bar to the Bayerisches National Museum digital collection that reads "wardrobe." Below in the search results it reads "Unfortunately, your search for 'wardrobe' did not yield any results."

Fig. 1: Search results from the Bayerisches National Museum digital collection search using the keyword “wardrobe”

Search bar from the Bayerisches Natoinal Museum's digital collection that reads "schrank." Below, the search results includes several images of wooden wardrobes.

Fig. 2: Search results from the Bayerisches National Museum digital collection search using the keyword “schrank“

This small experiment between primarily German collections may only prove my own lingual Anglo-centricity, but it does introduce another challenge to organizing and improving the accessibility of digital collections. Is there a way for metadata attached to images to be easily translated? In a world where digital and online spaces can feasibly grant access to collections from any corner of the globe, will language still be a barrier? Or will tools that primarily use visual features, like imgs.ai, mitigate this problem?

            Digital collections are important for institutions not only for research but to grant accessibility to all. This not only includes academics, but also the casual browser. While collections databases should be able to execute advance search functions, institutions should also provide intuitive and engaging interfaces to browse through. Whitelaw discusses this idea in his article “Generous Interfaces for Digital Collections.” Whitelaw praises the intuitive nature of the Rijksmuseum website and offers a few examples of user-friendly interfaces in Australia including “Discover the Queenslander,” a magazine archive, and “Manly Images,” a series of digitized images in the collection of the Manly Public Library. I think that the Rijksmuseum is also a great example of an institution that balances accurate, thorough, and intuitive search functions with engaging content for the casual browser. Its “Art Explorer” tab is particularly exceptional because it provides prompts to encourage leisurely audiences to interact with its collections. In the future, I think that institutions should look to the Rijksmuseum’s website as an example for both leisurely browsing and detailed searches.

            After this week, I firmly believe that digitized collections should be accessible to academics and general audiences alike. Bonisch and Offert and Bell’s articles highlighted the potential to make digital collections even more user-friendly while Sherratt’s article the great work that digital collections management has already accomplished. Whitelaw emphasized the necessity of “generous” interfaces to de-mystify searches and encourage browsing for general interest. Moving forward, it will be exciting to see—and even participate in—the new methods that institutions will discover to make their collections even more engaging and accessible to the world.

« Older posts