This week, we discussed networks and webs as visualization tools. In articles like “Iterative Pasts and Linked Futures: A Feminist Approach to Modeling Data in Archives and Collections of Artists’ Publishing,” and “Perceptual Effects of Hierarchy in Art Historical Social Networks,” we heard from different digital art historians who engage with networks as a means of changing how we think about different artists and art movements. Multiple of these authors mention the idea that networks can be a method of disrupting or decentering hierarchy in data visualization. Opposed to the family tree, or even the timeline, no one point in a network can be treated as an origin point. This visual change does fundamentally alter the way we understand information, understanding each point relationally and on equal standing with one another.
In “Perceptual Effects of Hierarchy in Art Historical Social Networks,” the authors created studies to see which kinds of visualizations were more clearly understood by students. Interestingly, a number of shortcomings showed up for networks, one being that for many students they were less legible and harder to retain. This makes sense to me, because the whole point of network visualizations is to nuance data—and nuance rarely lends itself to things like simplicity and clarity. In this case, I think this means we should just use the right tools for the right information. When visually depicting a family, I really think that the old-fashioned family tree is the most effective way to present information. It communicates visually what those relationships are in an accurate way.
From “Perceptual Effects of Hierarchy in Art Historical Social Networks”
However, when it comes to a group of artists that worked at the same time as each other, a network would be a much better representation. I’ve often thought I should make a network for my own purposes working on contemporary art, charting who’s done talks or exhibitions with who. In class, we looked at networks that charted different visual artists. This had its issues, mainly that the scope was not well defined, placing disparate artists alongside each other, some having many points and others having very few (despite the fact that they were well-known in their artist community at the time). For example, artists like Georgia O’Keeffe had no connections, despite the fact that she was an extremely well connected artist through Alfred Stieglitz’s studio 291 and then through her own reputation.
Like many of the projects we’ve looked at in this class, most issues with networks come down to an ill-defined goal or scope. But for our digital project this week, our goal was defined and very, very important: chart the cast of Dancing With The Stars!
We made this project with Kumu and while most of my classmates collaborated on one document, I did not get the memo—thus, I created my own network of just Season 7 of DWTS. I did this by uploading a .csv file which I converted from a chart I found on Wikipedia. I realized that Wikipedia actually lets you download .csv files directly from their site. Nonetheless, once I uploaded the data, it needed a lot of cleaning up. Here, I actually found Kumu frustrating: it’s interface doesn’t work exactly like a spreadsheet, even though it presumably could. Instead, you have to manually type everything in, and it’s harder to move categories around and copy/paste. I feel like this was one of my less successful projects in this class, but oh well.
For this class, we were tasked with looking at a number of different timelines. Some of these incorporated mapping as well, and some didn’t, and some were less traditional that others. One of the map-timelines we looked at was Mapping Austrofascism, which charts the events of a single day in 1933 Germany. From the outset, the idea of mapping on a timeline the events in a single day in Vienna which ultimately show the Nazi takeover of Germany is really interesting. I always like projects that address histories which have been told many times over in a new way. The “topography” took me through a more traditional map, and the “topology was more akin to a timeline.
Throughout this project, a decision was made that vintage maps would be used (understandably), but their appearance was sometimes confusing and muddled. Still, this was a really cool idea for a project. Another project about modernist woman artist Mina Loy used a whole plethora of different digital projects, many of which were timelines.
These timelines tracked many different facets of Loy’s life and the historical context which surrounded her. Looking through this project, what struck me is just how effective a timeline can be for storytelling. I know it feels obvious or even rudimentary, but timelines are still one of the most effective ways to visualize how events relate to one another temporally. Art historians tend to under-utilize timelines, maybe because we tend to do everything through written essays. I have found in my short time teaching an introductory seminar to art history that we perhaps should bring back the timeline. If I find it hard to keep the order of all these written dates in my head, then I am sure that some of the undergraduates do too.
I was then inspired to look at some potential teaching tools related to timelines, and one that came up was from SmartHistory (which I often direct my students to). Though their timeline linked to very detailed information, it was more text-centered than a true visualization should be. Just scouring the internet, I found a timeline but it’s too broad to show to my students. Perhaps one day I’ll find a good one to share with my students, ideally before they have to take their final exam for the semester.
An art history timeline made by a Reddit user
However, what I found continuously is that a timeline can become very uninteresting and unengaging if you’re not invested in the subject matter, because in some cases there’s less interactivity than other kinds of digital projects have. This is where combining a timeline with a map can add interest and extra context which creates more investment from users. For my project this week, I decided to create a timeline from my own research interests: one that combined the history of surveillance with the history of art that addresses surveillance.
I have to say, I am really happy with how this turned out. To me, it makes a difference when these technologies and systems arose, but it tells us about the political context and motivations behind them. I was surprised at just how impactful it was for me to see the combined timeline between art and technology, which contextualized the art in a new way. I would like to keep expanding this timeline, potentially to use it in a project down the road.
In On Rational, Scientific, Objective Viewpoints from Mythical, Imaginary, Impossible Standpoints, authors Catherine Ignazio and Lauren Klein advocate for an approach to infographics that allows viewers to feel alongside the graphic. This approach is certainly counter to so many scientific journals and political science groups which attempt to convey information through the most “objective” graphics possible. In the midst of the 2026 midterm elections, we were all being constantly inundated with these kinds of charts, graphs, and maps, all of which attempt to represent the election as accurately as possible, and many of which can be hard to read nonetheless.
Midterm election graphic from Al Jazeera which shows different types of potential map styles to represent election results
The day after the election, many different news outlets released a litany of various graphics or visualization tools—here’s one from Reuters that I found particularly interesting, because it used almost every chart format one could think of. When we think of ideal charts to show electoral college votes or state elections, we think of perhaps the least embodied and least subjective format possible: after all, isn’t the goal to communicate facts in a bipartisan way? If I were to make a chart that embodied my experience of this election, it’s aesthetics would certainly communicate joy, enthusiasm, etc… but these graphics are meant to communicate to diverse audiences.
However, as first argued by Donna Haraway in her Situated Knowledges , we should always treat claims to complete objectivity with some suspicion. To claim objectivity is to claim that there is no particular narrative or perspective being communicated, no act of persuading, and that is almost never the case when it comes to graphic design. As Ignazio and Klein put it: “Any communicating object that reflects choices about the selection and representation of reality is a rhetorical object.”1 The authors posit that, if this is true, we should be more mindful about what we’re actually trying to portray in graphics and charts. If we don’t limit ourselves to objectivity and indifference, a world of creative possibilities opens up, where emotion and embodied experiences could be communicated through data visualization.
Do Women Have to be Naked to Get Into the Met Museum? Guerilla Girls, 1989
Instead of “data visualization,” Klein and Ignazio point to “data visceralization.” This is where data and graphics teams work to visceralize the data they represent whether through the creation of multi-sensory interfaces, or making graphics that are meant to garner emotion in it’s audiences. Here there’s clearly an overlap with visual art more broadly. The Guerilla Girls made feminist infographics about inequity in the art world, but they did so in a format that was punchy and meant to garner affect. As the authors note, civil rights movements are well aware of the power of a good infographic.
Another example they gave was this chart which depicts gun deaths in the U.S. as years of life lost. Part of what makes it so effective is the animation, where you see the trajectory of one person (one dot) begin its arc before abruptly cutting off. See here: https://guns.periscopic.com/
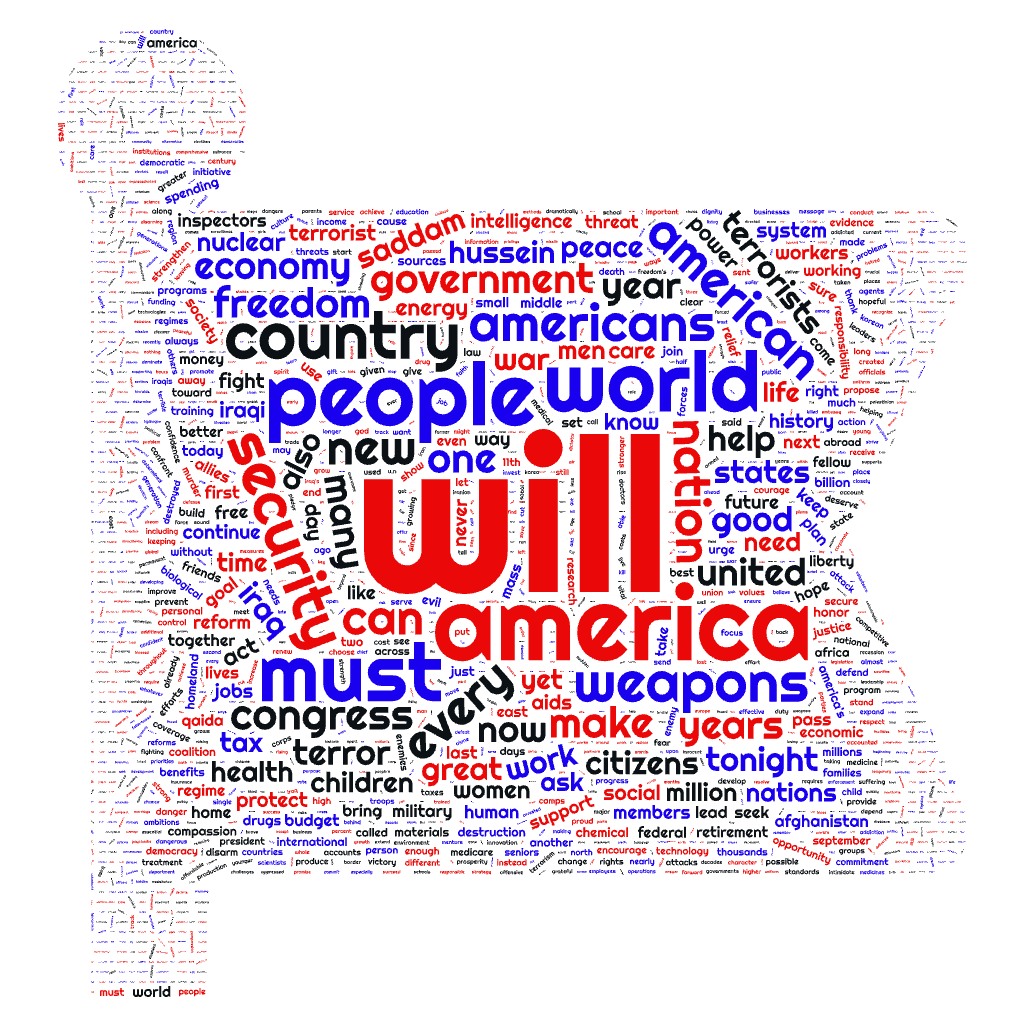
In this case, movement is what pushed this graphic into the realm of the embodied and affective, but there are many different ways to do that. For my attempt at “data visceralization,” I wanted to see if I could think about politics in a new way. In class, we learned how to generate word clouds, and I uploaded the full texts of George W. Bush’s State of The Union addresses from his time in office. I don’t often see word clouds in political graphics, but I think that the words politicians say can tell us a lot about the mood of politics any given year, and it’s a bit more descriptive than, say, a map that shows approval ratings or votes. What I came up with was only semi-effective as a graphic, and I’d like to revisit the project. Many of the words were too small to read, and I wish I could make a version where you can click on each word and zoom in, and the graphic would tell you how many times that word was said. Even so, I think my choice of the flag shape and the colors of red white and blue did elevate the graphic.
Honestly, a good look at this told me a lot about what the republican president was offering to the public at this time and which narratives he was trying to draw out. I think the fact that “will” is by far the largest word says a lot. There were a lot of promises to be made and a lot of explanations too.
In “Annotating Upstream: Digital Scholars, Art History, and the Interoperable Image,” M.J. Westerby discusses the role of International Image Interoperability Framework (IIIF), an open-source image metadata system, in art historical scholarship. At the top, he makes the stakes of this technology clear: when the British Library’s databases were hacked in 2023, their data which had been shared with IIIF was broken and led to objects becoming temporarily unavailable for scholars and the public to access on multiple platforms (not just the Library’s). While IIIF has some major benefits, like how it allows “images and descriptive metadata [to] be reused and decentralized,”1 Westerby notes that there is danger in having only one set of “upstream” metadata for any given object. Basically, Westerby argues that these institutionally-generated identifiers have a not-insignificant amount of power over how an object will later be described. Indeed, these “upstream” descriptions can shape the very narratives we have about a work, or can change the way we teach objects.
I completely agree—at the graduate level, I try to have a diverse and robust amount of sources to understand objects I write about, but as a contemporary art historian I find that there are often fewer descriptive sources than I’d like—leaving me to rely on metadata generated by only one or two galleries or museums. Similarly, I’m a Teaching Assistant for a survey of a (so-called) western art history right now, and it’s clear on the back-end how important it is to have IIIF and other institutionally-driven open-source data in order to create curriculum for and teach those kinds of classes. Westerby continues by arguing that scholars shouldn’t have to rely on sparse IIIF metadata and annotations about their images. They say, “art historians and digital scholars should produce IIIF resources and not rely only on institutional data services,” and later that “Art historians and digital scholars can take ownership of their insights and storytelling outputs by practicing upstream annotation.”2 An example of one such image description project is shown below.
Screenshot showing colored annotations in Digital Mappa 2.0 linking words describing elements of a painting to a IIIF canvas with an image of Orazio Gentileschi, The Lute Player, c. 1612/1620, National Gallery of Art, 1962.8.1. Image: M.J. Westerby
I think that art historians could practice engaging in these captioning projects as a creative practice, experimenting with different ways to describe objects past their date and medium. In this course, I’ve made my own Collection Builder site about surveillance art. When I was approaching the “description” part of the metadata, I wanted to focus on situating works in their art historical and technological context, rather than only saying what the object is. Description, translation, and annotation are all important creative mediums in and of themselves. Nonetheless, my personal take on Westerby’s proposal is that I do not have the time or real motivation to generate my own independently sourced IIIF data (or an equivalent).
It takes significant time, and the reason why museum and library institutions are the centers of these data sources is because they can and do pay people to work on IIIF and other digital archiving projects for their jobs. What he proposes sounds a lot like something I’ve done for different internships, not all of them paid unfortunately, but all of which I put on my CV, which is at least some material benefit. This feels like a proposal geared toward digitally-inclined art historians who have the time and resources to spend working on a fully independent metadata project—which isn’t any of the grad students I know!
Though our class didn’t engage in image annotation or metadata this week, we considered another type of data annotation: audio transcription. Using Panopto, I captioned a video I had made for the Department of Art and Art History’s instagram, where I asked different professors to give a tour of the bookshelf in their office. In part, I thought this would be an interesting case study because I had already captioned the video by hand and I wanted to see how accurate Panopto was in comparison. There were a number of art historical terms that it had trouble picking up on, but for the most part it was accurate and certainly far quicker than doing it myself. I went on to use the tool for my own research. First, I had Panopto caption an hour-long talk between the contemporary artist I’m writing my thesis on, and an important scholar who’s curated their work. Though YouTube did have captions on this video, being able to pull quotes directly from the Panopto transcript is extremely useful. Second, I used Panopto to transcribe an interview I conducted with the artist I’m writing my thesis about, who I met in their New York studio about a week ago. Aside from the clear benefits of having this interview in the form of a written document, it also saved me the deep discomfort of listening to myself talk for an hour (except for when I had to fix errors in the transcription).
I like the idea of getting creative with captions too, though that doesn’t serve my research goals right now. A number of artists (especially video artists) have treated captions as a creative medium.
Westerby, M. J., (2024) “Annotating Upstream: Digital Scholars, Art History, and the Interoperable Image”, Open Library of Humanities 10(2). doi: https://doi.org/10.16995/olh.17217 ︎
“How do art historical questions and evidence intersect with geographic concepts and digital mapping methods?”
This question opens Paul Jaskot and Anne Knowles’s article about their work mapping and spatially visualizing concentration camps during the Holocaust. Over the course of the article, the authors give us a look into how their own research evolved over time largely due to the challenges and new perspectives furthered by working with GIS mapping technology.
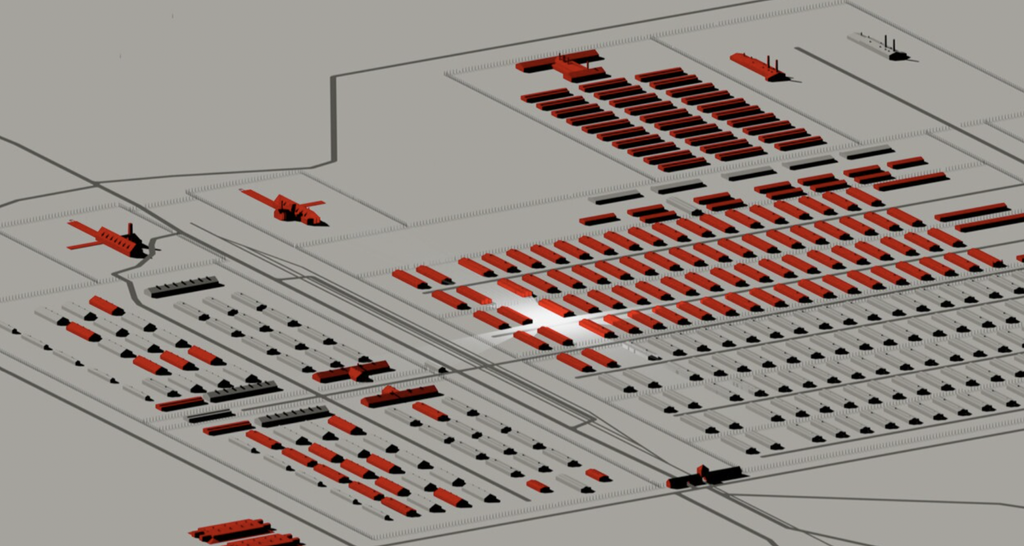
The project itself was a collaboration between art historians, historians, and GIS specialists to use GIS to visualize the development of the SS camp system over time. The first hurdle was the quality of information available—a running theme in digital art history. Though the Nazi Party kept detailed documentation, this cannot always translate into the specific coordinates or specific dates necessary for GIS systems. Translation becomes an issue here, especially in historical contexts as filled with trauma and violence as the Holocaust. Data will never be able to convey the emotional weight of these specific times and places, which is something the research team considered when they were making their model of how the Auschwitz camp expanded and evolved over time. Nonetheless, the process of visualizing the camp’s changes brought to the fore new and important research questions for the scholars.
Plan of Auschwitz-Birkenau, with red shading indicating buildings under construction or significant repair from May 1943 to May 1944. Reconstruction and map (as of state of research 2010) by Chester Harvey.
To answer Jaskot and Knowles’ opening question, art history certainly intersects with geographic concepts and mapping—art history is, after all, still one approach to writing history, a field to which, geography, and the changing of space over time hold clear weight. Maps could allow us to visualize evolving political geographies (like national borders) and the development of different art movements, the building of monuments, etc.
Though there are so many obvious use-cases for mapping as applied to art history, the field itself lacks training in creating maps and often lacks the motivation for using them. For better or for worse, it’s a convention of the field that we begin our study with the art object, and it is this quality which makes art historians averse to viewing a map as a main source of inquiry. Particularly for contemporary art historians, merely mapping the location or structure of the works we study wouldn’t always yield interesting results, as artists tend to be centered around big population centers or universities, which would not always generate an interesting map.
I myself ran into issues when trying to apply mapping to my own art historical research. Contemporary art is often well-suited to digital projects, with many artists using digital tools in their own work, and I really enjoyed making a small archive of surveillance art in collection builder last week (see here). However, when it came to mapping, I struggled to think of a map that would be useful for my research purposes. If I were to map the physical locations of the installations I study it would look like a huge cluster in New York City, a smaller cluster in LA, and some scatters throughout the rest of the country: affirming what we know about the major art centers in America. I considered creating a map which focused more on surveillance specifically, thinking of the pre-existing Flock camera maps (see here), but quickly thought that I don’t have the technical capabilities to do so.
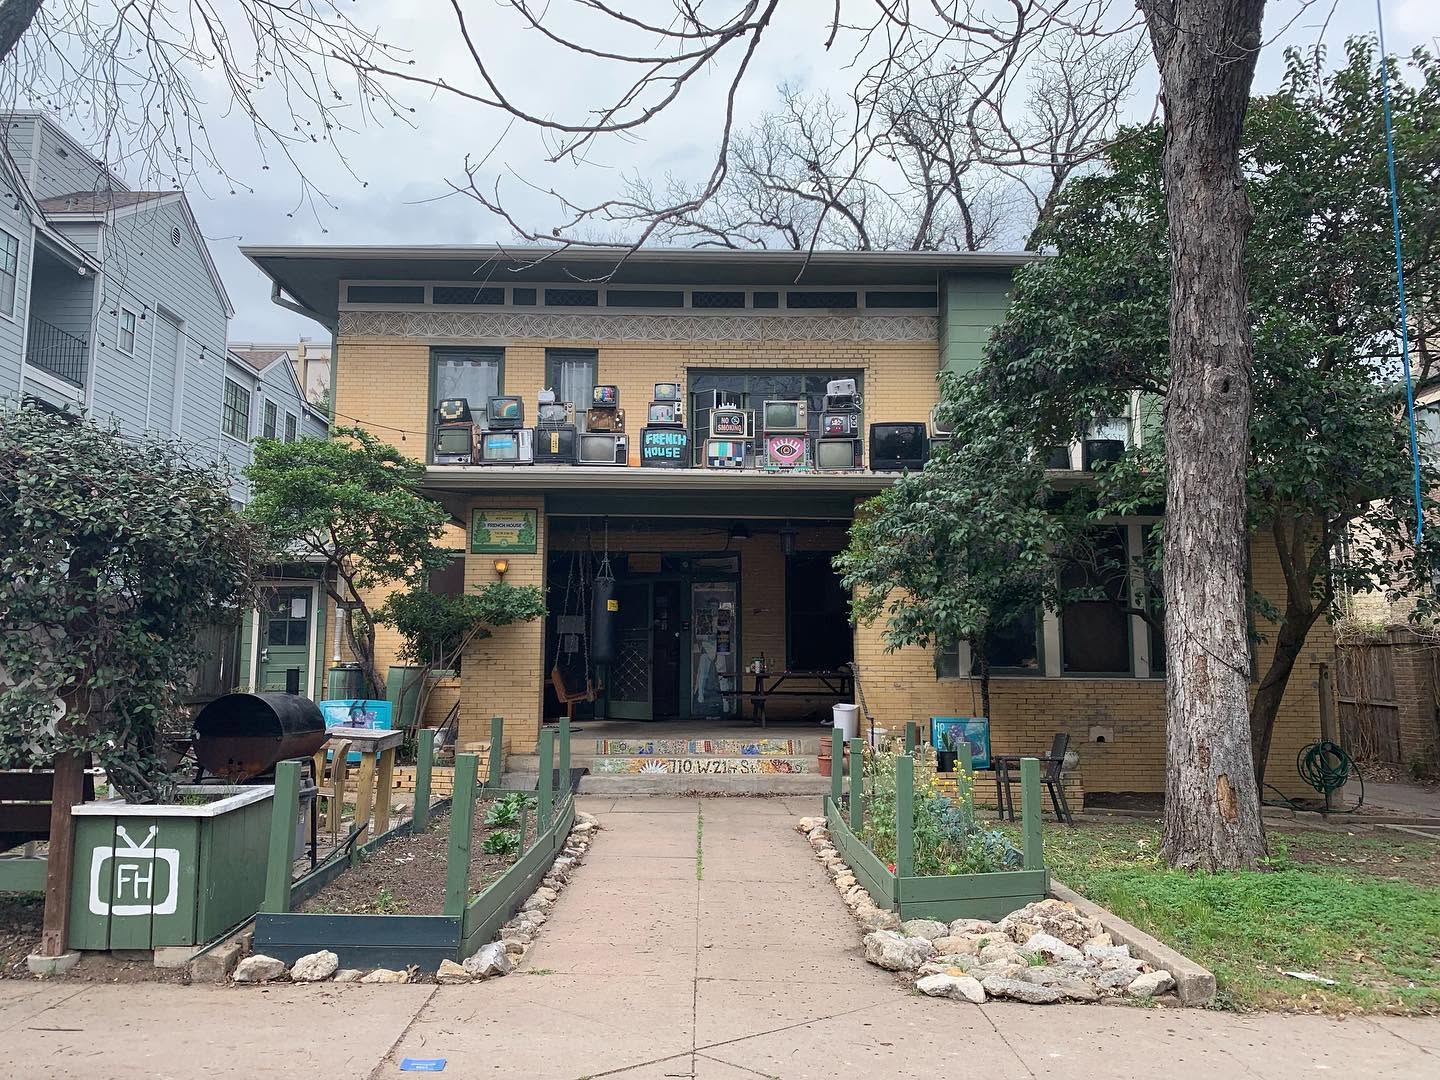
Though I know I could fruitfully connect mapping to my research if given the time, I decided to make a map about a more personal project instead: cooperative student housing in Austin, Texas. As an undergraduate I lived at a number of these “co-ops,” and aside from providing me essential social support and housing, I was always interested in the architecture and history of these homes. Austin is a relatively new city, and its population boom was only in the 2010s, so much of the town is populated by new builds. Co-ops, on the other hand, often originated as depression-era group houses which means many of the buildings date to the 1920s.
French House Co-op, ICC (Inter-cooperative council) Austin, in 2019. The house was originally built in the 1920’s, and still has many of it’s original features, like the decorative molding on the front of the home. This is where I lived for the last two years of my undergraduate experience.
Considering Jaskot and Knowles’ proposal that a mapping project ought to be led by spatial questions, the spatial question in this case might be how the presence of the University of Texas affected the distribution of cooperative houses. That said, the other reason I made this map was in the hopes it might be useful to the co-op councils that are in charge of these houses, either for promotion and visibility or logistics. There is always, always, the fear that cooperative housing will cease to exist because of a lack of funds. In a city full of aggressive housing developers, I shudder to think of what might happen to these historic homes if they had to go for sale. This project felt like a small way of giving back to the community that supported me.
Codex Zouche-Nuttall (source: Michel Wal, GFDL, via Wikimedia Commons)
Week FOur, 9/8/2026
This week, we’re thinking about developing digital collections, and the issues posed by using photos that do not necessarily belong to you. It’s easy to see the connection between these two topics—in order for students to utilize programs like Omeka to create class projects, they often have to pull images and other files from outside sources, like archives and museums. While I was creating my Omeka project as an undergrad, I was lucky enough (or perhaps unlucky enough?) to have photographed and processed all of those images myself, such that our readings which outline scholars’ general anxiety about permissions and images surprised me.
Once again I’m drawing from my own experience with Omeka, which can be viewed in my projects page.
However, an issues report on “Copyright, Permissions, and Fair Use among Visual Artists and the Academic and Museum Visual Arts Communities,” sponsored by CAA, detailed quite convincingly that not only are the majority of scholars anxious about using images, but that this anxiety can really hinder research. The report notes that scholars simply are unaware of how copyright law actually functions, and therefore that their “work is constrained and censored, most powerfully by themselves, because of that confusion and the resulting fear and anxiety.”1 (CAA Report, 7)
Much of the report is spent advocating for the understanding of fair-use images, and images in the public domain. Essentially, while scholars might be worried that they’d face legal repercussions for not gaining permission to use a specific image, oftentimes they are well within their legal right to use said image under fair-use policy. I imagine this is equally, if not moreso, the case for students who create publicly available projects as part of their coursework. In those cases, there’s a clear educational motive behind the use of whichever image.
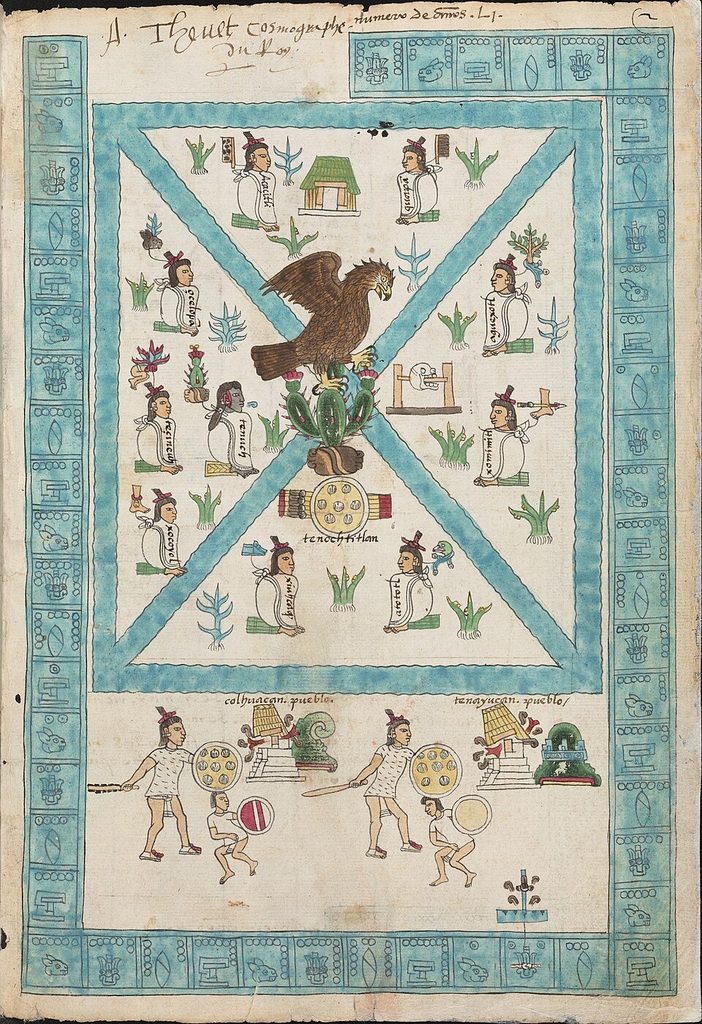
One such example is the work done by art historian Lauren Kilroy-Ewbank, who began implementing Omeka into her classroom to explore the pre-Columbian Mixtec Codex Zouche-Nuttall.2 In her article, “Doing Digital Art History in a Pre-Columbian Art Survey Class: Creating an Omeka Exhibition Around the Mixtec Codex Zouche-Nuttall,” Kilroy outlines how and why Omeka specifically was her collection-builder of choice for students. The interface is fairly beginner-friendly (though it definitely has its frustrating aspects) and students can organize different pages under one larger exhibition. This means that although each student was learning and writing about the same Codex, they would make their specific page about only one aspect of the codex—say, one specific symbol or theme.
Further, this visually-forward platform allows art history students to equally value images and text as aspects of their scholarship, which is sometimes lost in traditional essays. Kilroy also mentioned that she had an assignment which trained students in DublinCore, the language conventions widely-used by archivists. I thought that not only was this a potentially useful skill for the job market, but also that it’s a great way to get students thinking about some of the fundamentals of art objects. “What is this object made of?” and “what is it used for?” might appear to be an obvious question, but it is essential that we begin with those considerations when we’re discussing art objects.
Codex Mendoza (public domain via Wikimedia Commons). Note: I was lucky enough to handle a real codex, very similar to the early-colonial era codex seen above, at the Benson Latin American Library while I was a student a UT Austin. It was pretty awesome.
Finally, in class this week we began to explore CollectionBuilder, an open-source model for creating digital collections using metadata and linked files. Like all good digital art history tools (see Omeka above), CollectionBuilder is free and open to use by the public. A similar model to this can be found in ArchivesSpace, which is also open-source, but is more focused on internal data management rather than user interface, and is most often used by institutions as opposed to individuals. CollectionBuilder finds much of its strength in its relative accessibility, and seems to be most useful for pulling public domain and fair-use files from different sources to be compiled in one exhibit. Another strength of CollectionBuilder is the built-in user interface: it’s simple but effective, and it automatically creates a timeline.
It must be said, however, that the biggest weakness of CollectionBuilder is the fact that it relies heavily on HTML coding. Despite the digital prowess and training that archivists generally have, often those abilities manifest in their use of specific programs like the aforementioned ArchivesSpace, or the popular TheMuseumSystem. Further, us art historians often seem like luddites in comparison to our more computationally-minded colleagues in the archives, meaning that CollectionBuilder’s heavy reliance on code is even more of a barrier to access. While I understand that one cannot ask too much for a free-to-use and communally created software, the fact that users have to navigate code and coding in order to develop a collection makes the software somewhat more inaccessible. Even so, I am excited to start building my own collection using CollectionBuilder, with my fair-use and public domain images of course!
Patricia Aufderheide, et al. Copyright, Permissions, and Fair Use among Visual Artists and the Academic and Museum Visual Arts Communities: An Issues Report (College Art Association, 2014) ︎
Lauren G. Kilroy-Ewbank, “Doing Digital Art History in a Pre-Columbian Art Survey Class: Creating an Omeka Exhibition Around the Mixtec Codex Zouche-Nuttall,” Journal of Interactive Technology and Pedagogy, no. 12 (February 2018) ︎
In class this week, we’re considering how artificial intelligence could aid or impact digital collections. To preface, I am generally skeptical of the utility of AI (particularly consumer-facing AI like Chat GPT), and am one of many who are concerned about the kind of future the technology might bring about. Even if you set aside the massive ecological impact that AI will have on our planet—which is a lot to set aside—the daily use of these technologies holds clear ethical issues. It is frequently implemented to devalue human labor, devalue learning, and to infringe upon artistic ownership. Nonetheless, the technology itself is one of many new digital tools, and in the right hands it can do really interesting things. When considering viable and meaningful implementations of AI, one that immediately comes to mind for me is archival work.
In one sense, digital archives (and data management in general) present an ideal use case for machine learning/AI. The job of a digital archivist is to sort large amounts of data and metadata, often with different media types linked to one object. One thing that machine learning is good at, even the consumer-facing large language models, is compiling huge amounts of data and making sense of it in a manner that a person can more easily digest. The other major task of an archivist is to identify what an object, artwork, or document actually is; of course, image recognition is another popular use of AI technologies.
However, the focus for this week was not on how AI might be able to aid the internal work of archivists, but rather, how it can aid us in creating more dynamic, accessible, user interfaces. In particular, two of the digital projects we read about each utilized AI to showcase the formal similarities between different images in a larger cluster of images. One project was Imgs.AI, which allows users to search pre-existing collections—like the Met or the Rijksmuseum—by choosing images that they’d like to see more similar objects to.1 The other project, “Training the Archive,” utilized a similar technique, wherein machine learning models were trained to make visual associations between images before generating a map or a schematic, grouping similar images with one another. Both projects take a human’s ability to recognize similar images, and an art historian’s finely honed ability to do so, and automates it to the end of quickly generating a schematic of images.
Though the project’s stated ambition was to create an intuitive, fun, and automated website to sort images, Imgs.AI was relatively disappointing: its interface was confusing, not clearly labeled, and the sorting capabilities rarely seemed more advanced than your typical digital collection.
In the other AI digital collections project, “Training the Archive,” the machine learning model was trained from theories of the German art historian Aby Warburg (1866-1929). In order to train this model, project leader Dominik Bönisch notes that: “a procedure had to be implemented that would enable curators to connect digital collection objects with one another according to specific (…) criteria for context, aesthetics, iconography, and art historical references.”2 (Bönisch, 26)
Though many of the graphics generated from this project accurately picked up on formal and aesthetic nuances, the machine learning process still relied heavily on the expertise, and labor, of human professionals.
At the present moment, it seems that there is a distinct ceiling on what machine learning can contribute to digital archives, digitization, and user interfaces, and further, I believe that there will continue to be. As Dr. Bauer noted during class, each and every one of these projects still require human intervention, and I expect this will continue to be the case. At the very least, humans still need to be present as editors and fact-checkers. Though Bönisch ends his article by declaring that “AI is also suitable for the automated processing of the collections.” (Bönisch, 29), I am not so sure that this is currently the case. Further, digital collections managers and archivists have been creating dynamic and impactful user-interfaces without the use of AI for decades now.
Each of the impressive digital archiving projects referenced by Tim Sherratt in his 2011 article “It’s all about the Stuff: Collections, Interfaces, Power and People,” were created prior to the popularization of artificial intelligence, and the expertise of curators and archivists come to the fore in each of these projects.
Virginia Untold: The African American Narrative is one particularly effective example of how archivists can make records legible and accessible to audiences. By providing high-quality scans, grouping items together by theme or relevant historical event, and attaching explanatory texts to collections, archivists shaped legal documents and letters into an accessible narrative for general audiences and researchers alike. Users are also able to easily save certain documents to read for later by “pinning” them to their account.
As alluded to in my last posts, digitization is a laborious and often boring process. That being said, it is a process that is completed by interns, students, and volunteers, alongside professional archivists with library science degrees. I fear that what is at stake here is not the implementation of AI to make those laborers’ jobs easier and more impactful to the public, but rather, a proposition to replace them with machine labor as much as possible. Though a novel and potentially useful technology, the introduction of AI and machine learning will not solve the systemic issues that our field continues to face. Prior to introducing these new technologies, we ought to re-assess the technologies we already use, and give archivists the resources and training needed in order to be digitally literate. In my opinion, the systemic underfunding of our field is at the heart of this struggle to create exciting and accessible user interfaces.
Fabian Offert and Peter Bell, “Imgs.AI. A Multimodal Search Engine For Digital Art History,” International Journal for Digital Art History (vol. 9, 2024) ︎
Dominik Bönisch. “The Curator’s Machine: Clustering of Museum Collection Data Through Annotation of Hidden Connection Patterns Between Artworks.” Digital Art History Journal (May 4, 2021) ︎
From left to right: Brigid Hynes-Cherin, Peter Hynes, Arleen Hynes, and Timothy John Hynes
Week two: 8/25/2026
“The nature of the gap between original and surrogate may change as technology improves, but it can never be entirely closed. In fact, the strengths of digital surrogates lie in their differences: their versatility, their independence from time and place, their potential for creative interaction.” — Emma Stanford in “A Field Guide to Digital Surrogates”
Any museum professional, archivist, or librarian will be able to recognize the significance of digitization, or “digital surrogates,” to the field today. Immense resources, labor, and time have already been dedicated to the digitization of all manner of documents and it’s unlikely that demand for such projects will stop soon. From an accessibility and preservation standpoint, the benefit to a digitized archive is readily apparent. Information held on physical documents can now be preserved where it otherwise might have been at risk of damage or degradation. People from across the globe can now view documents and artifacts held at archives, libraries, and museums, so long as they have access to the internet. There are so many more benefits to well-done digitization projects, like the potential to easily transcribe and translate digitized documents with OCR.
From The Georgia O’Keeffe Museum’s Access O’Keeffe, a comprehensive digital archive which compiles high quality scans of O’Keeffe’s paintings, photographs, letters, and other archival documents. While I was an intern at the O’Keeffe museum, the lead archivist and librarians were still collaborating to make this project a success. The resulting digital interface is easily searchable, with a sophisticated system that allows users to search from a number of tags generated from metadata.
Of course, it is worth interrogating any technology or methodology used by archivists and art historians, particularly when so many resources are directed their way (at times, at the risk of other kinds of projects). In “A Field Guide to Digital Surrogates: Evaluating and Contextualizing a Rapidly Changing Resource,” scholar Emma Stanford outlines the long history of “surrogates” (or, images of art objects) as an essential resource to art historians, while also making a close evaluation of all the complications and pitfalls that this populate this practice in the digital age. Institutional structures, and failings, account for many of these—for example, it is impossible for most institutions to digitize all of their archives, leaving the decision of which objects and documents should be digitized as a curatorial one, and therefore impacted by many of the same factors that continuously shape curatorial decisions. In the case of the Bodleian Libraries at the University of Oxford, this meant that more manuscripts were digitized according to what interested big donors. Even on a smaller scale, editing through omission is one huge way that digitization can distort documents. Stanford points out a number of examples: long manuscripts which only have a few “important” pages digitized, how digitized images often crop the objects and documents they capture, or the inability of photography to capture the tactility of objects and papers.
In reality, so many of the issues that plague digitization efforts have to do with funding and labor, even though Stanford does not always acknowledge this outright. What archives and museums can actually afford to have a lengthy and costly digitization project depends largely on which institutions have funding, which is largely dependent on complex socio-economic factors. There is also the question of usability and access once the archives are actually digitized. As lengthy a process that scanning and archiving digitized documents can be, designing the interfaces through which users access these documents is just as extensive. The ability (or inability) to search for accurately described objects is at the center of what makes a digitized archived accessible (or not). Ideally, each archive would be able to provide extensive tags for objects, and would reliably be able search from the metadata of objects, but this is often not the case. When I designed a digital archive in Omeka for a collection at my undergraduate university, I was certainly not leaving detailed tags for each item. I was the only research assistant working on the project and I simply did not have time, nor was I being paid enough, to make the archive as accessible and searchable as I would have liked it to be.
From my own work as a digital art historian, making archives accessible to the public. https://utctlarchive.org/
Of the above issues with digitization efforts, most are somewhat solvable given enough time and money. There’s one issue that remains genuinely irreconcilable: that a digital surrogate will never be able to capture the physical object in its entirety. Art historians know this well, which is why they often advise students to see works of art in person if at all possible. Stanford believes that rather than being a weakness, the inherent difference of a digital surrogate can be a strength:
“In fact, the strengths of digital surrogates lie in their differences: their versatility, their independence from time and place, their potential for creative interaction. The most effective digital surrogates leverage these traits.” (Stanford, 211).
Recently, I have been able to see these strengths with a newfound emotional potency. My cousin and I are currently embarking on a digitization project for my late Aunt Brigid’s family and travel photos, of which there are thousands. Such a project is a serious archival task, but it’s allowed me to view the work of digitization through new eyes, outside the confines of my professional life. I have a large family (21 first cousins), and I can feel how much it means to everyone to have these images of loved ones, so many of whom have passed, accessible and preserved for future generations.
While nothing can replace the affective experience of holding one of these photographs in your hands, this project can open up new opportunities for family members to see their history where otherwise we might have to wait for another family reunion, wedding, or funeral to view them. When I approach this topic from a critical art historical perspective, I see many of the gaps and failures of digital surrogates as a sign to be wary of them. However, this project has given me assurance of the real-life significance of digitization. Whether or not it’s apparent in the moment, you never know the importance digital surrogates might hold to a researcher or a private individual.
Ultimately, the project of digitization is an important and worthwhile one, but it’s equally important to consider the labor of museum professionals, interns, and volunteers, many of whom may be victim to the exploitative labor practices of a field that so often lacks the money and resources to back otherwise worthy ambitions. It is with this institutional structure in mind that we could continue to acknowledge the limitations of digitization, while advocating for the laborers doing their best to surmount them.
“The struggles and wishes of our age are, undeniably, wrapped up in computational systems.” —Amanda Waiselewski and Anna Naslund in “Critical Digital Art History”
Digital Art History (or DAH) can refer to both the tools that art historians might use, and a way of thinking about art history. For this week in our seminar on “Alt-Methods: Digital Art History,” we were assigned a number of readings that sought to understand the history behind DAH and what it means to be a practitioner of “digital art history” today. As a defined discipline, it is far newer than art history proper; of course, the very tools that would produce DAH only came about with the widespread popularization of computers. Yet every author we read this week is quick to note just how important technology, whether digital or not, has always been to art historical research. Alison Langmead writes in her “Art and Architectural History and the Performative, Mindful Practice of the Digital Humanities,” that the adoption of the slide projector in the late-19th and early-20th centuries as represented a major shift in the field. Pioneered by art history professor Herman Grimm in the 1890’s, the projector (initially called a “Magic Lantern”) presented opportunities for art historians to teach simultaneous to students and lecture attendants viewing works of art. For a field that relies on the often unsteady ability of words to accurately represent images, it’s understandable that such a device was adopted quickly. Langmean continues, noting that throughout the 20th century, the slide room and the projector continued to be the main tools of art historians and art history teachers. Significantly, not only were these technologies incredibly useful to art historical research, the neccessity of a physical slide library where art historians (often professors and students at universities), were allowed a kind of third-space to meet and discuss their work.
What followed the overwhelming switch to digital cameras, screens, and computers was not a shift away from the use of images and projectors in art historical teaching, but rather, the abandonment of slides and slide rooms. DAH practitioners Harald Klinke and Paul Jaskot both note this discipline-wide shift to the digital as one of many ways in which all art historians are already “digital art historians,” despite the field as a whole tending to look down on novel and creative uses of digital technologies in research. As an art history graduate student, I can attest to the fact that despite my professors’ consistent reliance on digital images, computers, and projectors, very few of them seem to be entirely comfortable with digital technologies and most research outputs are the same as decades past (like research papers or manuscripts). Klinke proposes that art historians already dealing with digital data on a regular basis ought to look to DAH as a means of improving their data literacy: what he defines as the ability to understand and critique where, how, and why data was generated, and further, the ability to recognize the role of algorithms in the filtering of information.
Of course, most of DAH is conducted through projects that use data in digital systems which generate a myriad of formats. My experience in archival roles has given me a greater familiarity with DAH projects than my time as an art history student has. Because archives are interested in making a large amount of data accessible and interesting to the public, digital formats can present so many opportunities. I’ve worked on a couple different projects that had to do with digitizing archives and creating interfaces for audiences to view and sort the contents of the archives. One consideration in these contexts is how we (as archivists) can make our collections engaging, and formats like Omeka are really well suited to that. Another major consideration is that, often, only one researcher at a time can view archival documents in person unless they’ve been included in a physical exhibition. For both art historians and archivists, the tools proposed by DAH can present so many opportunities to expand our audiences. Much like slide rooms in the 1890’s, images and data can be democratized and made accessible through digital technologies. Paul Jaskot even argues that the opportunity to present information as maps might make art historical data itself more “democratized,” in the sense that where a paper typically requires a single narrative, the visualization data offers more potential loose associations.
Nonetheless, these visual data sets do still offer opportunities to present those single narratives—for better or worse. Maps, graphs, 3-D visualizations, and digital exhibits are all subject to distortion and narrativization by their authors. This is similarly true of the digital image which, like the slide image, is only one possible representation of an object. The central issue of reproductions versus reality presented in Walter Benjamin’s seminal “The Work of Art in the Age of Mechanic Reproduction” (1935) remains truer than ever in our digital age. Yet, I would hope that art historians can embrace the digital technologies that we are already using, consider using new ones, and even begin to build data literacy in themselves and their students. The world is certainly not going to become less dominated by computers and digital data anytime soon.




 ︎