Women Architects and World Fairs

Author: Kat Cardullo (Page 1 of 2)

Immersive Facsimiles as a Form of Play

This is the probably unit of the class I was the most excited about! I am very familiar with 3D modeling on the arts production side, but I had never had the chance to approach it from an art historical or pedagogical perspective. In particular, I was not familiar with embodiment theory; I was operating on a much more vibes-based understanding of what makes art immersive that’s informed by my own trial and error in creating immersive environments. Sarah Kenderdine’s article “Embodiment, Entanglement, and Immersion in Digital Cultural Heritage” explores some of what it means in a more philosophical sense to build a multisensory, non-static, kinesthetic representation of works of art. Part of Kenderdine’s argument is that these types of environments allow for a higher level of learning and emotional connection for students who are able to use these tools. 

I think this builds on some interesting conversations about surrogacy that we’ve touched on over the course of the class. Namely, is there a way to create a facsimile that comes close to replicating the experience of the original work? While I think virtual reality and 3D models are incredible technological marvels (I was, in fact, prepared to devote my life to making them before realizing the work available to me was car insurance commercials and unpaid indie films), I’m not sure that they’re the real, true answer to that question. However, that does not necessarily render them useless. A theme I’ve been thinking on throughout the class is the space Kenderdine describes as “the borderline of the indexically real and the phantasmally virtual – between re‐embodiment and dis‐embodiment.” We all understand, on a fundamental level, that facsimiles are not real. I don’t think there is a way to capture the true aura of an original object, and yet, that has never once stopped anyone from trying to share their experience of that aura. Surrogates then end up existing in the space between truth and performance, never really able to lean into one side or the other. I don’t think we can start to have effective 3D and immersive surrogates unless we start explicitly breaking that kayfabe and being intentional about embracing the places where these methods fall short of reality.

If the ultimate goal of making an immersive environment or 3D digital representation of an object is to offer the opportunity to advance scholarship and investment in specific works or sites, as antithetical as it sounds, I don’t think you can neglect spectacle. Something my former professor Stuart Robertson said once really stuck with me, and even if it’s not necessarily a 1:1 analogy in this case, stick with me. In Christopher Nolan’s The Dark Knight, it was decided that they’d be flipping an 18-wheeler on set rather than rendering it in post production, where it would have been cheaper, safer, and still gotten the point across. But, you can bet that every person who was on set that day they flipped the truck walked away telling that story for years afterwards. Sometimes, you just have to do things because they’re cool! And while that is an interesting moment in cinema history, it certainly didn’t detract from the story that was being told; if you bring up The Dark Knight to someone, they’re much more likely to acknowledge the performances in the film than the truck flip. To that end, wonder and awe can have a place in pedagogy, and that doesn’t necessarily mean that the substantive intellectual content you’re leading them to is cheapened. If the gimmick truly supports the narrative you are trying to tell and gets more people to engage with something they may not have before, it is worth doing.


It was exciting for me to get back into photogrammetry during this week! One of my mentors at SCAD wrote his thesis on incorporating photogrammetry into visual effects curriculums, and a few of my classmates and I got to help start up a photogrammetry club at the school. While the technology has been around for a while, as a 21 year old in 2018 it seemed like it was magic! I was also fortunate enough to be in lovely Savannah as I was learning, which has some incredible architecture that was relatively easy to capture. Although I never finished this project, here’s a screenshot of a model I created depicting a set of stairs down to River Street that my friends and I called “The Bachelorette Killer.” 

And here’s a turnaround of an unpatched model of my friend’s plushie that I included in my demo reel.

We got to generate the beginnings of a model in our workshop, and I’ll admit I was surprised how well it worked with only 12 images! Typically, we recommended 30-80 photos in our workshops, but that many high-resolution photos would have made this short workshop take much, much longer.

I’d also like to point out something that you may not know if you haven’t ever 3D modeled before. Take a look at the wireframe for the model, and take a look at how many faces it has.

For any kind of practical purpose, this is not best practice. In order to make models created with photogrammetry usable in production without ballooning your render time (or slowing down your real-time viewer), you’d need to decimate and retopologize this model. Without getting too much into the weeds of 3D modeling workflows, this means that you redraw the faces in a more logical way that does not remove detail from the model itself. Here’s an image that shows what exactly retopologizing looks like- notice how the detail of the form is not being lost, but the wireframe looks like something you can understand. 

For our purposes in this class, retopologizing is not a pressing issue- I only bring it up because if you want to create a model that you want people to actually use, reuse, and distribute, you will need to take steps to prevent it from lagging people’s computers and browsers.

Kenderdine, Sarah. “Embodiment, Entanglement, and Immersion in Digital Cultural Heritage.” In A New Companion to Digital Humanities, 1st ed., edited by Susan Schreibman, Ray Siemens, and John Unsworth. Wiley, 2015. https://doi.org/10.1002/9781118680605.ch2.

Mental Maps and Spaghetti Globes: showing connection effectively

Although our focus as a class was on network analysis as a product and process of research, it seemed like many of our discussions took us into the realm of user experience design. Network analysis can be complicated (and is very easily overcomplicated), and the effective illustration of networks seems to be the true test of not only the clarity of the research, but a solid understanding of how it could be used. 

In the 2022 article “Perceptual Effects of Hierarchy in Art Historical Social Networks” by Lamqaddam, De Prekel, Brosens, and Verbert, network graphs were stress tested by graduate students in order to measure their efficacy as tools for communication. Lamqaddam et al. really dug into why we organize connections the way that we do, and how we can create clear maps that allow for hierarchy but do not limit relationships to being hierarchical. They considered where the differences lie between mental maps and physical ones, and asked both where that clarity was being lost and how they could incorporate it back in. The branching family tree style network has such a strong cultural hold on how hierarchical relationships are understood that drastic deviations from this organizational structure increased levels of frustration and decreased levels of confidence in the viewers’ understanding of the material. 

This article resonated with me, because as someone who has not yet had the chance to use network graphs in my academic career, I find myself getting a bit lost in the “spaghetti globe” (as Dr. Bauer put it) without feeling fully convinced that it brings any additional clarity or insight into research. While I never had the opportunity to take UX design classes in my undergraduate program, I had friends and roommates who did and I helped blind-test their designs by showing them how I would navigate them. I will never forget the dawning realizations on their faces when the structures that made complete sense to them weren’t particularly clear to me (or to their other testers), and I’ve noticed that same dissonance between how a project is designed to be used and how it actually appears to its users in a few of the projects we’ve looked at for this class.

Network analysis also seems to highlight some of the underlying inadequacies of representing complex information with a flattened set of data. For instance, in Lozana Rossenova and Karen Di Franco’s article “Iterative Pasts and Linked Futures,” Carolee Schneemann’s Parts of a Body House is used as an example of an open-ended network mapping success. The nature of artist’s book publishing places works such as this one in a uniquely situated web of connections; several iterations of the same content have been published in different literary forms, and despite being catalogued, archives, libraries, and museums have no universal standardized way to indicate the presence of text from this work. For instance, Parts of a Body House was also partially published in several magazines, but because of the nature of cataloguing, Schneemann is not indexed as being a part of those publications and therefore it would be difficult to locate versions of this text across multiple institutions. 

When we were playing with Kumu as a class to map the people involved with Dancing with the Stars, we got to see how difficult it is to map some of those multiplicities. What we started with was straightforward: add contestants, judges, and pro dancers and connect them to their roles. What we ended up with was something that still needed some work to become legible. Here is our map as we left it in class.

And here it is with a little cleanup. Hopefully the interactable map loads okay.

iframe[src*="kumu.io"] { height: 750px !important; min-height: 750px !important; }

I felt like surely the first iteration was not the intended final product, so I messed around in the settings a little. Forgive me, I know it was a collaborative project! All I did was un-pin all of the nodes and let Kumu do its default force-directed organization. It’s a lot more legible, but you can more clearly see now where we were still working on adding in connections and building new types of connections. For instance, one type of connection my classmates hoped to add was married couples. In Kumu you can connect any nodes to one another, but in order to define that relationship you have to annotate that connection. This makes it very difficult to build a network at a larger scale; sure, we were able to reasonably begin a network of a few dozen people, but what happens when you want to map hundreds or thousands of connections? Network analysis is, after all, intended to facilitate macroanalysis. It is not an impossible task by any means, but it seems like a difficult one to scale that gives diminishing returns on clarity.

Of course, social networks are not the only thing you can map; we also took a look at the tool ORBIS, which honestly answers a lot of my qualms about network mapping as a research product. ORBIS, which is a project mapping the transportation network of the Roman Empire organized by Stanford, bills itself as an “interactive scholarly work.” While there is a distinct difference between networks mapped as a research method vs networks mapped as a product of research, ORBIS seems to somehow be both. I’m not particularly an expert in the Roman Empire (I took my first survey of art history course over ten years ago and only studied contemporary art after that), but even I could see how valuable of a tool this could be for a number of audiences.

ORBIS charting a path from Londinium to Alexandria in the Summer.

I think ORBIS is a particularly effective example of network analysis because it has a clear visual goal based on connections in a framework we can understand and has ample documentation of how to use the tool itself, which really embodies that goal of being an interactive scholarly work. Having the scholarly work is one thing, but as I mentioned before, It’s not worth much as an expression of information if no one can read, understand, or use it.

Iterative Pasts and Linked Futures: A Feminist Approach to Modeling Data in Archives and Collections of Artists’ Publishing. December 19, 2022. https://www.artic.edu/digital-publications/37/perspectives-on-data/28/iterative-pasts-and-linked-futures-a-feminist-approach-to-modeling-data-in-archives-and-collections-of-artists-publishing.

Lamqaddam, Houda, Inez De Prekel, Koenraad Brosens, and Katrien Verbert. “Perceptual Effects of Hierarchy in Art Historical Social Networks.” Digital Humanities Quarterly 016, no. 1 (2022).

“Modeling Networks and Scholarship with ORBIS · Journal of Digital Humanities.” Accessed October 26, 2026. https://journalofdigitalhumanities.org/1-3/modeling-networks-and-scholarship-with-orbis-by-elijah-meeks-and-karl-grossner/.

Timelines and Micronarratives

While broader data visualizations and maps are helpful for getting an overview of a topic, timelines are a great way to get into the minutiae. When the scope of a project is much more focused, such as with the life of an artist or a single day in Vienna, organizing information chronologically tends to be a more compelling way to communicate an idea. This week, we looked at some projects that took different approaches to the deep dive with varying levels of success.

The most expansive project, “Mina Loy: Navigating the Avant-Garde,” was truly a bit shocking to me in its scope. Aside from scholarly essay collections, it contains multiple exhibits, timelines, games, a participatory artwork, and 20 student projects under a tab called “New Frequencies.” Reading through the article written on the process of creating the site, it becomes clear why it has been constructed that way. Most importantly, a number of grants were acquired to fund this three-year project. This allowed faculty researchers to create the bones of the site, which they then used as a pedagogical tool to allow students to explore the life and work of Mina Loy in a more creative way. As a result, there are a lot of hands that touched this project. To me, this was kind of a strength and a weakness at the same time. Having more creative reinterpretations playing on the lines of an artist’s creative philosophies is engaging (and I’m sure was fun to put together), but at the same time, the way the site is organized is somewhat meandering at times. It seems like they allowed the project to grow more organically, which does fit with the theme of the manifesto on the site; ultimately, it is successful in its goal of “challeng[ing] you to read outside the norms of scholarly writing.” I very much enjoyed the “art exhibits” section, which uses works created by Mina Loy as “maps” with annotations at specific points in the image. I think this is such a great communication tool (and use for StorymapJS) for art historical research that not only walks viewers through the intricacies of the work itself, but how to even do a close reading of an image in the first place.

A screenshot of the Storymap for Mina Loy’s 1959 work Prospector 2.

While some of the organization of the second biggest project we looked at (Mapping Austrofascism) was also a bit convoluted to me, I really liked how well the linear storytelling method used fits the thesis of the project. Essentially, a play-by-play of a 24 hour period (May 13-14, 1933) tells the story of “the Nazi ‘seizure of power’ in Germany and the Austrian response to these developments.” It is clear that there was a lot of thought put into every choice about how to represent this critical turning point; project lead Simon Ganahl writes about the influence of the chronotrope as a way to capture an essence of modernity. In my experience of navigating the project, it adds an urgency and contextualization to the description of events that I hadn’t seen in a project like this before. I was also very inspired by how in-depth the descriptions associated with each of the fifteen data points were (especially in the topology section), including images and videos. I will admit, I’m not super sure what the purpose of splitting it into topology and topography is, but if I just consider that it is two different ways of looking at the same information, it makes a little more sense. Overall, I thought this project was really cool and I definitely was inspired by its compelling and clear narrative!

An expanded selection from the 24 hour timeline on Mapping Austrofascism.

I’ll also briefly touch on some of the less successful timelines we looked at in class…namely, the Time Explorer from Google Arts and Culture. I think in principle it’s something that could be functional and even potentially open up new paths for scholarship by allowing holdings from international museums to be placed next to one another, but as it is right now, it’s just a cautionary tale in metadata standardization. Which is unfortunate, because I feel like people who aren’t necessarily deep in history truly conceptualize what global events were running concurrently: there’s the classic example of samurai and cowboys existing at the same point in time in the mid/late 19th century. A tool like this has the potential to globalize art history in a thoughtful way, but clearly, no one is cleaning up the metadata here. Hokusai’s The Great Wave off Kanagawa is indexed for every museum that has a print of it, which is at least a dozen. Perhaps the most unfortunate of the museums featured is the National Folk Museum of Korea, whose undated objects show up in every single time period on this scale (and some more often than others, for some reason). I think this is such a disservice to these artifacts, and it even makes them into a bit of a nuisance to scroll through since they are so incongruous with every list that they’re included in. Archives and museums have been dreaming of an aggregative database for ages, and while this is a step in the right direction, it looks like we’re as far as we’ve ever been from realizing that dream.

This centrifuge from the National Folk Museum of Korea makes a lot of appearances. It is shown here in the section attributed to the 1500s.

After digesting all of these ways of expressing stories temporally, we got to practice it ourselves. To be quite honest, the only thing I could think of that I could get a full 20 data points out of was the story of Patience Worth. If you looked through my CollectionBuilder site on séances I touch briefly on Patience, but she’s got an interesting story worth digging into. A St.Louis woman named Pearl Curran claims to be in contact with the spirit of an Englishwoman who died in the mid-17th century named Patience Worth. This spirit is not being used for predicting the future, reading fortunes, contacting the dead, or any of the theatrics associated with Spiritualism; instead, Patience Worth wants to write and to publish, and that’s all. I encountered Patience’s work for the first time at my museum job. We were cataloging a series of 50+ diaries kept by a local woman; this woman loved poetry, and had clipped several of Patience’s poems from Reedy’s Mirror and placed them in her diary. Their highly stylized nature made me look twice at the publishing date, then immediately go to look up who this faux old English poet was. I was immediately hooked by how odd this story is. I feel like this is also a story that lends itself particularly well to being told in a linear fashion, because there was a lot of push and pull between Pearl Curran and her critics; they very directly influenced each other. (Here is a direct link in case the embed is being strange.)

I definitely have things I would do differently next time (especially aesthetically, since I spent more time on the content than the look), but overall using the new version of TimelineJS was so easy. After fighting with the Google sheets version, I caved and made an account so I could upload my own images (mainly newspaper clippings!) which made the process a breeze. I particularly appreciated the much more elegant way the new version scales the timeline to your dates.

The impossibility of “clarity without persuasion”

This week we picked up on a thread that we first touched on in our readings on mapping and spatial narrative-building; in Béatrice Joyeux-Prunel’s article, she states, “[…] when you publish a map, be careful about what it might seem to say.” The operative concept here is “seem,” because as we have seen, the ways in which we present data heavily influence our perceptions of it. Data visualization at its core is a narrative expression of information with all its subjectivity and ambiguity, but the word “data” offers a connotation of emotionless truth that simply isn’t present. Many of us in the class seemed affected by the emotionally charged visualization of gun violence created by Periscopic (as shown in chapter 3 of Data Feminism by Catherine D’Ignazio and Lauren F. Klein), especially when compared directly with the Washington Post bar graph depicting the number of active shooter incidents occurring between 2000 and 2015. Even though they were created for completely different reasons, they ostensibly depict the same phenomena: gun violence in America. And yet, one offers a visceral reaction while the other only offers a vague impression. 

Of course, I feel (or at least hope) that most people understand on some level that data can be represented differently in order to make it fit a narrative. However, it seems rare to me that the deliberate evocation of emotion is not only encouraged, but is the main purpose for the gathering of the data in the first place. This is of course not to say that I disagree with how the information is presented! On the contrary, I think that human impact is something we should be able to focus more on in a world deluged by data. In the example of gun violence, the scale of suffering we are experiencing is terrifying, and it grows every year. It is so easy to let the numbers be numbers rather than let them represent real, human lives, because comprehending suffering on that scale is incredibly difficult! But rebuilding that bridge is central to bringing an ethic of care to how we represent the world and our impact on it. As D’Ignazio and Klein argue, the traditional model of data visualization in which the emphasis is on “just the facts,” writes off ways of communicating information in a way that genuinely resonates with people. Data feminism as a philosophy seeks to challenge this false binary of truth and emotion, offering new ways of looking at and understanding how we represent and communicate information truthfully. Ultimately, it argues that “clarity without persuasion” (as cited by a workshop at the Guardian) is impossible.

I was particularly struck by the example D’Ignazio and Klein gave for the concept of “data visceralization” with the performance A Sort of Joy. There is a lot you can do visually to represent the gap between male and female artists in the MoMA, but it is easy to look once and not really comprehend what it means. By stretching that data spatially, aurally, and temporally, viewers are forced to confront the disparity in a highly uncomfortable way. I had never even considered a data visualization that is not purely visual and two dimensional, but by complicating the “look at a graph to understand the data” experience by removing looking and graphs, it forces a visceral presence in that moment that allows for emotion to surface. It is a highly persuasive representation, but at the same time, there is no untruth to it. Its point is clear and simple without supposition as to the “why” of the phenomenon; that is all on the viewer to determine.

In the vein of outside-the-box representations of data, we also took a look at AI images as a form of data visualization. I won’t lie, as both a digital artist and an information professional I do not have a high opinion of AI in general. Because of the impact on artists and the environment I think you would need to make an absolutely unequivocally solid case for the use of AI in general, and I just have never seen anything that to me justified its use. I’m happy to explore use cases and not write it off completely in case that unicorn use case comes along, but I truly think there is no good purpose for AI-generated images specifically. As Victoria Turk showed in her article How AI Reduces the World to Stereotypes, an image that is the average of everything on the internet is just going to give you the average of images created by the types of people who can access the internet. Although those numbers grow every day, the internet is largely still stuck in a white, Eurocentric, patriarchal world. Describing why this is a problem is preaching to the choir here, but the perpetuating of this singular worldview is an unfortunate and inextricable effect of the technology.

I also took a particular umbrage with Kaylee P. Alexander and Emily Lawhead’s article Data And Discontent: A Converging History Of Photography and AI Art and its conflations with the history of emerging art technologies. While certain technologies may look like magic and there have been artists who use technology to advance their work, they still require an eye for design and executive decision-making by the artist. But, I digress. AI generated images, which in a technical sense fall under data visualizations, at most evoke a curiosity in the current digital social landscape (as in Salvaggio’s Reading AI Art) and at worst are unethically produced visualizations that can cause real harm. I don’t think that ethics are worth setting aside for societal insights.

Keeping everything we learned about what makes a good visualization in mind, we were tasked with creating our own simple visualizations. I will admit that I struggled a bit with getting Palladio to work with the Tate dataset we input into it. I think this may be because I use Firefox rather than Chrome (to ideally disentangle myself from Google a little bit), but it crashed the site for me multiple times. I would love to explore it further with a different dataset at some point, but for the ease of sharing my results, I took a look at WordClouds instead. I input a portion of the first chapter from Skin Shows: Gothic Horror and the Technology of Monsters by Judith Halberstam since I’ve been reading it this month.

A word cloud generated from approximately 11 pages of text from Skin Shows.

It definitely picked out a lot of themes of the chapter (and the book overall), and I suppose it’s kind of a fun graphic, but I’m honestly not quite sure what I would do with this. I think you could probably glean as much information from the description on the back of the book. Then again, I’ve never been entirely sure what effect word clouds are supposed to have- we made plenty of them in high school, and I never felt like picking out single words did more than fragment my understanding of a text. Maybe it’s just me and my experience though, so I’ll be curious to see if anyone else feels differently and had some breakthroughs for their texts.

Annotation as Accessibility: the way we document non-textual information matters

With this week’s exploration, we took a look at a few of the ways we can attach textual information to visual information. Without being able to explicitly attach contextual information to an image or video, we lose out on entire readings of works and ways of relaying interpretations to future viewers. This also becomes a problem of accessibility in multiple senses of the word. By attaching textual information to images, video, and even audio, they become discoverable. Text can be indexed in a way that non-textual information cannot, and when we are able to flag specific areas of note, we create a more tangible record of what that non-textual information contains. In the second meaning of accessibility, the presence of text as an interpretive layer allows for greater disability access. Subtitles allow for those hard of hearing to engage with video and audio, and for those with visual impairments, the presence of text is necessary for a screen reader to function. By including avenues to attach additional information to image and video viewers, it theoretically becomes easier to expand scholarship on specific works.

In his article “Annotating Upstream: Digital Scholars, Art History, and the Interoperable Image,” Matthew J. Westerby lays out the potential benefits of using annotations to build on analysis across multiple scholars in addition to his more technical descriptions of the functions of IIIF. The field of art history particularly benefits from being able to embed analysis and research findings directly into images (and even 3D models); it allows scholars to point to exact details, filling in missing context and elaborating on often sparse museum-created metadata. The IIIF viewer also allows for a higher resolution of viewing, which encourages close looking and analysis. By being able to reuse, share, and disseminate high quality interoperable images, we encourage the use of “thick data.” Of course, as with many digital projects, there are a number of challenges and shortcomings of this approach that Westerby identifies. Firstly, there is no centralized platform to share this thick data on; analysis can be built upon by pre-existing networks of scholars, but its reach is limited. If we want to annotate upstream in the truest sense of the phrase, there has to be an upstream to begin with. There are of course user-created workarounds and plugins to share annotations, but it can be intimidating for less technologically-inclined scholars to integrate into this workflow. And of course, it almost goes without saying at this point that maintaining thick data in this multi-part form is a digital preservation challenge because of its many moving parts and semi-obscure file types.

We got to try a little bit of video annotation ourselves to see how it looks in practice through Panopto. After the Westerby article, I was curious to see what more art historical annotations would be like, so I brought in a video from my favorite artist duo: Janet Cardiff and George Bures Miller. If you are unfamiliar with them or have never had the privilege of seeing one of their pieces live, Cardiff and Miller construct looping, immersive, multi-media narrative works featuring animatronics/moving parts that are sometimes contained to singular rooms or scenes. I originally considered annotating my absolute favorite work of theirs, Opera for a Small Room, but unfortunately it doesn’t film particularly well. There’s a moodiness and a physicality that just doesn’t come across in video; not being able to move around the piece and feel the sound breaks the immersion (and Cardiff and Bures Miller rely a LOT on sound!). I had originally thought that maybe annotation could fill some of those gaps, but after annotating, I was a little frustrated that it just couldn’t replicate the experience of watching this piece. So, instead, I looked at The Marionette Maker, which is a similar piece from Cardiff and Bures Miller with a less direct, linear storyline.

While this video representation is still not perfect and misses a lot of the aura of the original piece, I enjoyed being able to mark it up like you would be able to for a static piece. Since there are no spoken words in The Marionette Maker, I added a few bits of analysis and transcriptions for the general soundscape. I have also edited the video down to a more appropriate length for this example from the full 11 minute and 11 second video available on the artists’ website. Please forgive some of the awkward cuts; I tried to cut down on the amount of time the camera lingers on each setpiece, but had a bit of a hard time getting precise in Panopto. If you’re interested in the full video, here is the youtube link (and some higher resolution photos so you can see the craftsmanship!). Don’t forget to open this video in Panopto to see the added notes.

Practicing annotating videos led well into our discussion on oral history. While a small number of traditions prefer to focus on the purely aural aspects of a recorded interview, most rely on transcripts and annotations to make their content accessible (and indexable). As someone who has been working in a small museum for two and a half years, I’ve had direct experience with how vital (and difficult) it is to make oral histories accessible. Since the museum is owned by the City of Raleigh, we face specific municipal pressures to have a collection that is of and for the people of the city; this means that when we accept anything into the collection, it’s important that we are able to make it accessible to laypeople and not just researchers. However, because we don’t have transcription software, every bit of typing and indexing we do is entirely by hand. It takes a lot of work (and a few janky workflows) to get the dozens of oral histories in our collection into a state that is even remotely searchable. 

Because of this, we have experimented with automated transcription for a project interviewing former students of Ligon High School. For some quick background, J.W. Ligon Junior-Senior High School was one of two of Raleigh’s black public high schools, and considered to have a particularly excellent teaching staff; many students went on to become STEM leaders in the Triangle area. The school operated as a junior/senior high school for 18 years before the desegregation of Raleigh public schools, and every year on the weekend of July 4th, alumni gather for a reunion. Some of these people have donated to the city’s historic collections before, so we have been trying to have a presence at these events, putting together small exhibits of Ligon items we have in the collection and operating an oral history station. Although the interviews only last 10-15 minutes, we still get about a dozen per year. Recently, when we had a several year backlog, we attempted to do some automation with our transcripts, which honestly did not save us much time. Transcription software tended to have a very difficult time deciphering the heavy accents of our interviewees, and it did awfully at understanding place names, so we had to go back in and basically rewrite the transcripts. It also of course did not understand any of the contextual information that we understand as stewards of this history- how could it possibly know that “the rat box” was what people called the movie theater on Hargett Street and index it appropriately? 

I have a lot to say about oral history as a practice but in short, without being able to add that context back in, holes start to appear in the historic record. 

Westerby, Matthew J. “Annotating Upstream: Digital Scholars, Art History, and the Interoperable Image.” Open Library of Humanities 10, no. 2 (2024). https://doi.org/10.16995/olh.17217.

Maps for Narrative-Building

Many of the visualization methods we’ve been looking at this semester fall under the umbrella of distant viewing, and spatial data is no different. Rather than looking solely at the minute details that make up a data point, we’re allowed to take a huge step back and see what patterns, if any, emerge. Because the purpose of this type of visualization is to help illustrate these patterns, it can be versatile as both a research method and a way to express the results of that research. The process of placing textual data about locations into a representation of three-dimensional space can unearth a number of unanticipated complexities within the data used. This is also a very highly visual and contextual medium of representation, so while we did look at some literature on the topic, it made more sense to see as many examples as we could in order to compare and contrast. 

Béatrice Joyeux-Prunel’s work with the Artl@s was a great introduction, since with her chapter “Digital Humanities for a Spatial, Global, and Social History of Art” we got an inside look into the processes and principles that went into the final product. I appreciated the very balanced look she took in the process of mapping; she advocates for mapping as a research method and not necessarily as a standalone product, and gives guidelines for making sure that the purpose of your maps is clear when they are reduced to static images. However, I’m not so sure the final result of the Artl@s project we looked at (Geography of the Parisian Art Market) was all that successful as a final product. The process of conducting this research may have been illuminating, but as we spoke about in class, the final map does a poor job of elaborating on its purpose, function, and ease of use. Having an adjustable timeline was a necessary feature, but the lack of data at each gallery location makes in-depth analysis difficult. This is especially true when juxtaposed with projects like Mapping Gothic France, which contains exhaustive documentation on each of the cathedrals included in the project. I thought that this project was very well scoped, which seems to be a key to success for digital visualization projects. They knew that location mapping was not the only point of the project- it was just one aspect of physicality, which was what they actually hoped to convey. Rather than 1900+ sparse data points they included ~200 thorough data points, which in conjunction with the time afforded to work on the project set it up for a great final product. 

The shift from standard art historical thinking to cartological thinking also appears to have been a difficult one for both the Artl@s project and the Jaskot and Knowles project we looked at. For Jaskot and Knowles, even coming up with a shared vocabulary for architectural historians and historical geographers was difficult. In the article “Architecture and Maps, Databases and Archives: An Approach to Institutional History and the Built Environment in Nazi Germany,” Jaskot and Knowles describe their experience mapping Auschwitz-Birkenau. One important factor they discuss is the decision-making process to narrow down more generic information on construction into definitive data points. Disallowing these ambiguities feels counterintuitive to standard research methodologies, but in order to represent information in this very binary system, it was necessary. Jaskot asks a question in this article that I think is a much more important question than it seems at first glance: “How accurate did our digital models have to be to provide acceptable answers to our questions?” Rather than letting their judgement calls on preciseness sit as end-all-be-all determinations of fact, they were able to allow ambiguity back in by asking how much of that preciseness is actually reflected in the final product. And, since this project ended up acting as more of a research tool than a public-facing visualization, this still ended up surfacing some interesting questions and observations about the spatial and bureaucratic elements of the camp. 

After weighing all of the examples we looked at, we created our own (much, much simpler) spatial maps. I was very intrigued by the narrative framing of StorymapJS, but didn’t think I had enough time to really give a project in it the detail it deserves. So, I looked at Google Maps instead. For my map, I took a look at tourist traps and roadside attractions; I think they’re such an interesting phenomena (and a wealth of weird vernacular art!), and I wanted to (hopefully) illustrate how the development of highways created and shaped many of these little kitschy spots.

I unfortunately didn’t get super far into the highways part of my map, but fortunately Google maps does display highways. Most of the 20 locations I chose are either in urban metropolises or right off of major interstates, and I was a bit surprised that this held true for both new and old attractions! I’m sure maps like this have been made a dozen times over, but I definitely would like to continue with this little project. I was also curious to see if specific types of attractions were concentrated in particular geographic zones, but I think I would need more data points to really analyze that. For instance, Georgia seems to have a lot of oddities museums and West Virginia has (at least) two cryptid museums- it would be interesting to interrogate why that is. 

Jaskot, Paul B., and Kelly Ann Knowles. “An Approach to Institutional History and the Built Environment in Nazi Germany.” Getty News, February 15, 2017. https://www.getty.edu/news/dah_jaskot_knowles/.

Joyeux-Prunel, Béatrice. “Digital Humanities for a Spatial, Global, and Social History of Art.” In The Routledge Companion to Digital Humanities and Art History, 1st ed., edited by Kathryn Brown. Routledge, 2020. https://doi.org/10.4324/9780429505188-10.

When the tombstone isn’t enough: how we represent uncertain data

The concept of authoritative data is inextricably linked to Western methods of cultural understanding. When we expect data to be clean, neat, and authoritative, we are leaving behind more complex questions of ownership and history. Susan Elizabeth Gagliardi and Constantine Petridis’s article “Mapping Senufo: Making Visible Debatable Information and Situated Knowledge” makes the case for an expansion of our implicit beliefs about data using West African art as an example. In these cases, Gagliardi and Petridis found typical “tombstone” style data to be insufficient; aside from dubious methods of obtaining provenance from early 20th century collectors, very rarely are these works attributed to a single person or even a single use. In their case, the only things they could identify with any reasonable amount of certainty were the approximate locations that these objects were crafted in. While this has the potential to be the case for a large swath of art historians, there is not a lot of work going on to standardize the ways in which this information is represented in databases. This is an interesting conundrum- the way we structure and standardize data is essential to its legibility and usability, but it is clearly not serving everyone in the ways that it should. While I’m not fully sure I understand the more expressive, illustrative visualization methods proposed for Mapping Senufo, I appreciate that they are grappling with this question and attempting to propose alternative methods of promoting understanding.

A possible design for Mapping Senufo featuring hand-rendered elements, created by Mark Addison Smith after photographs in the Michel Convers collection, Musée du quai Branly-Jacques Chirac, Paris, as presented on January 31, 2020, to the Mapping Senufo team. Courtesy of and © Mark Addison Smith.

The slippery nature of data is easy enough to talk about, but it becomes really clear when you start working with it. In our workshop this week, we took a look at a few visualization methods using API data from the Tate. Each of the 65,000+ entries in the spreadsheet had a reasonable amount of tombstone information in them, but a few factors quickly limited what we could do with the data. Firstly, any field with unstandardized text (or text at all, really) was immediately off the table for generating graphs and charts. This meant that anything with a date range or uncertain creator was inaccessible for this form of visualization. For the Tate this is less of a problem since they do not particularly focus on antiquities, but for many other museums, any level of uncertainty makes data from whole eras and movements inaccessible. This was something I also ran into while working on my CollectionBuilder exhibit– when looking at the material culture of spiritualism in the late 19th and early 20th century, many of these objects were used and refined over long periods of time. Attribution is also further complicated by the fact that many of these objects are a type of ephemera intended to be used in performance and never acknowledged as true objects with authorship- to acknowledge that the “ectoplasm” is a thin linen pulled from the nose of Helen Duncan would immediately and irrevocably alter the purpose of the object by disrupting the suspension of disbelief. While the specific dilemmas any field of research faces regarding the certainty of their classification and identification will be different, this exercise has driven home the point that complete standardization of data is virtually impossible (even with just ten items).

In addition to looking at the textual metadata for images, we also took some time to look into text analysis this week. It was something I had been vaguely aware of, but didn’t quite know the extent of what you could do with it. I thought the project Mining the Dispatch was particularly successful in illustrating what text analysis can do. The tool looks at trends in the Richmond Daily Dispatch throughout the duration of the Civil War; when viewing graphs of multiple trends at once, hypotheses start to form. For instance, viewing trends for clothing advertisements alongside trends of articles mentioning trade can illustrate when some of the effects of blockades were starting to be felt by Virginians. In order to explore text analysis on our own we looked at the tool Voyant, which creates a dashboard of potential textual analysis tools for one or more textual documents. It offers word clouds, trends on word usage, frequency of phrases, correlations between words and phrases, and a number of visualization tools to represent the text.

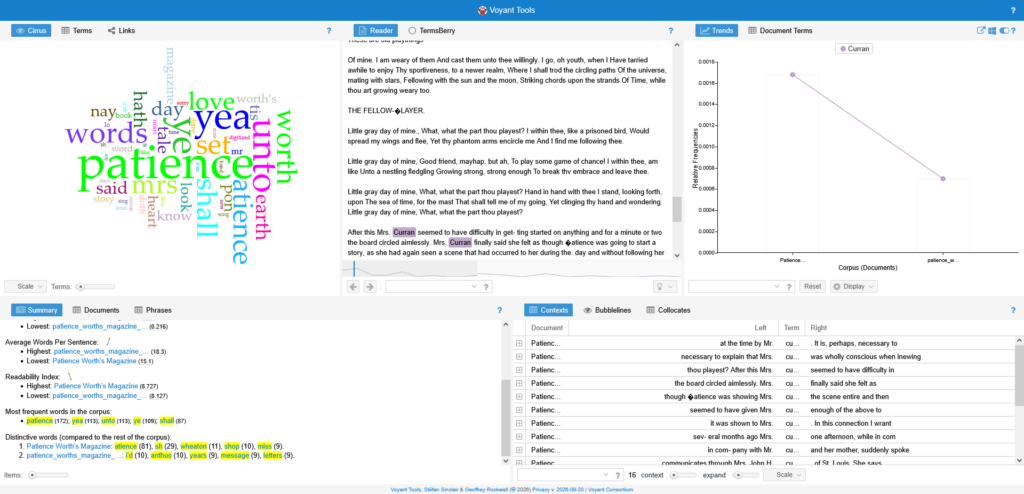
Since I had a PDF of Patience Worth’s Magazine that I used for my digital exhibit, I was curious what results Voyant would return for the first and last issues of the magazine. The language of Patience Worth is perhaps the most notable and most debated part of her works (besides the authenticity of her otherworldly origin); written in a faux-archaic English, her poems and fiction never seem to falter in their own internal logic system. Voyant offers a ton of different ways to visualize and understand Patience’s notoriously dense writing style as well as track changes from document to document. I was curious to see how mentions of Pearl Curran, the “channeler” of Patience, changed from the first issue to the last issue, and Voyant showed a clear drop in the frequency of “Curran” (most likely because the context of Patience’s writings was long out of the way by the final issue).

Voyant comparing the August 1917 and May 1918 issues of Patience Worth’s Magazine.

Of course this is just a beta version of the tool, but it still was very interesting to see what I could get out of it! And, as we learned this week, the tool is only as good as what you can put into it- these PDFs fortunately had decent OCR, but anything with poor OCR, large files, or more than two pdfs is unusable with this iteration of Voyant.

As for what types of data I might be interested in working with, I’m honestly not too sure. To be frank, I don’t have a clear, defined research topic- everything I drew from this week was from a lifelong personal interest in the occult, not true academic research. However, working with CollectionBuilder these past two weeks has offered me some more interesting ways of using metadata to visualize similarities and differences. I would be interested in using museum APIs to visualize collection data and explore trends, but that does unfortunately rely on museums to have very clear and unambiguous metadata. As we have learned from Mapping Senufo, that can be extremely difficult to come by.

Gagliardi, Susan Elizabeth, and Constantine Petridis. “Mapping Senufo: Making Visible Debatable Information and Situated Knowledge.” The Art Institute of Chicago, December 19, 2022. https://www.artic.edu/digital-publications/37/perspectives-on-data/23/mapping-senufo-making-visible-debatable-information-and-situated-knowledge.

What makes a successful digital collection?

While I had some cursory knowledge about digital collections and exhibits, it was great to take this week’s topic as an opportunity to really dig into what goes into making them work well. In her article “Doing Digital Art History in a Pre-Columbian Art Survey Class: Creating an Omeka Exhibition Around the Mixtec Codex Zouche-Nuttall,” Lauren G. Kilroy-Ewbank very clearly lays out her thought processes for why Omeka is such a great tool for teaching her undergraduate students how to think on a deeper level about both the Mixtec Codex Zouche-Nuttall and the ways in which its presentation affects its meaning. The codex’s nonlinear and non-textual narrative is uniquely suited to the benefits a digital exhibit can offer; it is a highly visual and modular presentation method. Pieces are easily rearranged, recontextualized, annotated, described, and compared. Working in Omeka right off the bat, while sometimes challenging for her students, also acts as a digital veil-lifting of sorts; as beginner students of art history, it is likely that many of these students have done most of their artwork viewing digitally. By having students investigate and explore metadata on their own, it immediately becomes apparent that everything they had seen about artworks online previously has been highly constructed, and suddenly every decision made from the classification of the object down to the digitized image itself becomes apparent. I had never thought about using this process as a pedagogical tool, but Kilroy-Ewbank makes an excellent case for using this type of digital curation to teach both textual and metatextual readings of artwork.

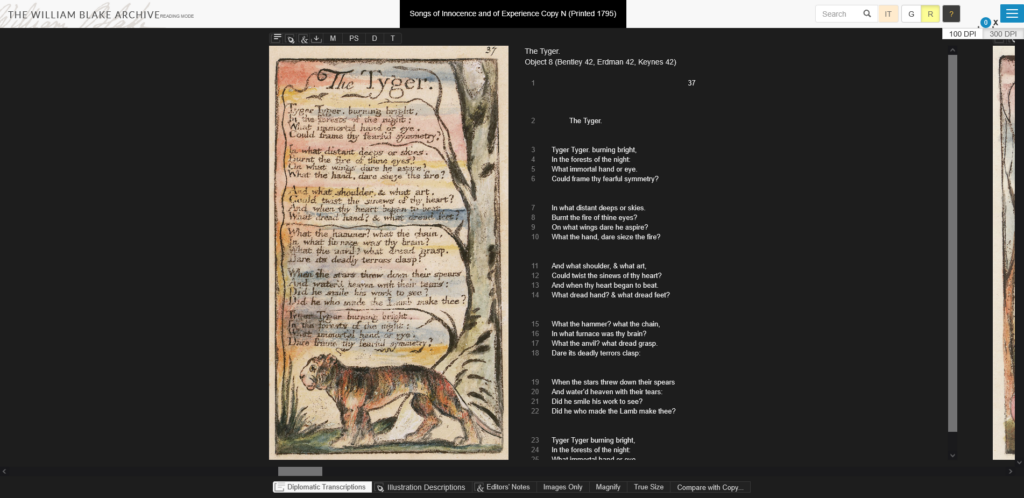
We also took a look at the William Blake Archive, which is a digital collection of both the poetry and visual art of William Blake maintained by the UNC Chapel Hill Libraries and ITS. The site contains both a searchable/browsable collection of his works as well as curated exhibitions with interpretive commentary from scholars. This archive is laid out very thoughtfully, and I particularly enjoyed looking at the documentation for the project! I had never seen a project lay out their past and present standards so clearly before, which is a shame because transparency is something that many archives are trying to improve. Not only does transparency help other institutions and collections know what you have (and its quality) so that your collection can be advertised via word of mouth, it helps build trust from your users when they can see how you decide what should be included in the collection and who took part in that decision-making. I also thought that the interface was well-chosen since it allows the user to toggle between written and visual information via a “gallery” and “reading” mode. When viewing a piece, the list of related pieces (with thumbnails) in that same series is also available below the main image viewer.

The William Blake Archive in “Reading” mode.

And, to make comparison even easier, the site has a lightbox feature! After hearing about how the lightbox of slides is a dying method of building theses in art history, I appreciated that the developers of this site still saw its value. Of course, it’s not a perfect site by any means (some of the dropdown menus could be better streamlined, etc), but as far as a custom-built interface for a narrowly-focused collection goes, this was a good one. I feel like I’m always saying that whenever anything isn’t tailor-made to a collection, no matter whether it’s something technical like a collection interface or something more bureaucratic like policy, it definitely shows. And while I’m not a scholar of William Blake, I can easily see how this resource would be a staple reference to return to. 

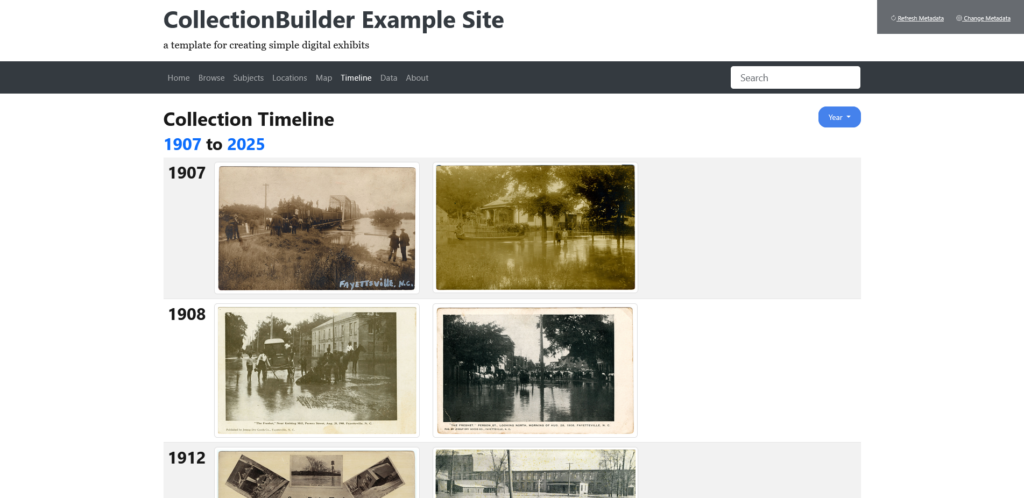
After looking more deeply at what makes a good digital tool, we also started out on our first project: to make our own mini-exhibit in CollectionBuilder. I had heard of CollectionBuilder before, and it was actually a system we had considered using in my practicum project (organizing, cataloging, and partially scanning hundreds and hundreds of slides encompassing 50+ years of work from Chapel Hill-born photographer Avery Danziger) but ultimately decided not to use because we didn’t believe it would be sustainable long-term for the artist to run on his own (and he preferred an offline system). I somewhat regret that now after seeing how easy it is to build, and it would have worked great with his goals of being able to view his work by subject, date, and location! I was kind of shocked at how easy it was- all you really have to do is have a GitHub account, make a copy of the template containing the source code and file directory, and link up a google spreadsheet to let that data populate on the site. It’s pretty difficult to mess up, and you don’t need to do a ton of ground-up web design to make it usable- plus it’s even open source! The basic template allows for browsing by a number of different methods (via map, subject, date, and even just in a list), which is a feature I have particularly appreciated on all of the collection interfaces I’ve found to be successful. No gimmicks, just clear, thorough metadata that offers a few predetermined ways of getting a collection overview. So, in a user experience sense, I really like CollectionBuilder.

The timeline from the example site we built in class with a test dataset.

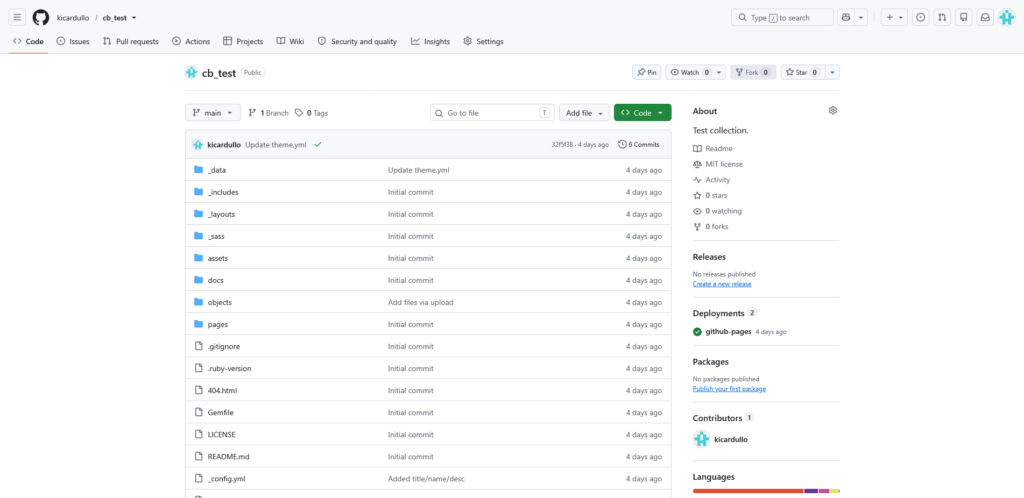
I do, however, see a few drawbacks with it. Firstly is that it is entirely dependent on GitHub, which is a for-profit company now owned by Microsoft. If you know anything about digital preservation, you know that this can put a huge wrench in longevity plans- it’s unclear how long Microsoft will continue to support GitHub or what would happen to it if Microsoft decided to abandon the site. It seems to be safe for the foreseeable future because it is a massively popular code repository (that even a lot of digital preservation tools are hosted on!), but as with anything for-profit, longevity is not guaranteed. Secondly, without coding experience, it can be difficult to change the basic template sites to something custom. From what I understand from looking at the documentation (I am not a code-minded person!), the benefit of using Jekyll as a basis for your site is that it takes a lot of the work out of coding an HTML site from scratch by using layouts and modular blocks. This is both a pro and a con- it’s fool-proof to use, but ultimately you’re kind of limited by what you’re given to work with.

The CollectionBuilder file directory for the template in GitHub. Kind of scary if you don’t know what you’re looking at.

As I work more in CollectionBuilder this week, I’ll be curious to see how my opinion changes!

Kilroy-Ewbank, Lauren G. “Doing Digital Art History in a Pre-Columbian Art Survey Class: Creating an Omeka Exhibition around the Mixtec Codex Zouche-Nuttall: Doing Digital Art History in a Pre-Columbian Art Survey Class: Creating an Omeka Exhibition around the Mixtec Codex Zouche-Nuttall.” Re-viewing Digital Technologies and Art History, February 21, 2018. https://cuny.manifoldapp.org/read/doing-digital-art-history-in-a-pre-columbian-art-survey-class-creating-an-omeka-exhibition-around-the-mixtec-codex-zouche-nuttall-9ecc5e1c-2062-4cd4-9ede-a7589404cd17/section/2ec0cf43-4333-4c25-aeba-d9aefb521d3b.

Balancing Search, Exploration, and Sustainability in Collections Interfaces

This week, we took a more critical look at the process of discovery in collections and what methods are being tested to make it easier to find things in databases of visual information. It was interesting to look at collection access from a user experience design point of view; facilitating use of the materials is what I believe the core function of any collection should be, but often it is swept to the side with the assumption that anyone who gets as far as your search bar already knows exactly what they are looking for. This problem is often further exacerbated by the complexities of searching for images, whose indexing relies almost exclusively on the information found in their metadata. For example, if you were trying to trace the origin of the pigeon-breast silhouette of early 1900s women’s clothing, there is a slim chance that searching “pigeon breast” would bring up every example of this silhouette in a textile collection. In order for a catalog entry to show up with that search term, its cataloger would have needed to add those words to its description in some shape or form via tags, subject headings, or plain-text description. This is where semantic searching comes in, which requires some level of cultural understanding of a query on the part of an information retrieval system and not just simple 1:1 text matching. Unfortunately, while many commercial search engines utilize this function, not many search algorithms in collections management software are advanced enough to do so. 

We looked at two projects in particular that took a machine learning/neural network approach to ameliorating some of these difficulties: “Training the Archive” and IMGS.AI. Both projects center on the central idea of clustering as a form of determining relevance, which they are able to do via image recognition tools that can pull out details such as color, shape, and other purely visual features. To be quite frank, I was not very impressed with the use cases of either of these methodologies. Both projects identify the need for a method of determining visual similarity in search that does not necessarily rely on metadata, and I do agree that this is especially true for large volumes of images, but in my opinion the question of “what can we do with AI tools” seems to have taken precedent over “what problems are people actually having while navigating databases.” IMGS.AI uses sound information retrieval theory with a clever way of instantaneously incorporating user evaluation, but in practice, its interface is highly unclear and essentially amounts to a “hot or cold” game with the database. “Training the Archive” uses a similar clustering system to replicate the knowledge and aesthetic sensibilities of a curator, and while it is true that it was able to pick out some stylistically similar images, I think it’s a bit bold to jump to the claim that it has the potential to become “The Unbiased Curator’s Machine.” It’s an interesting thought experiment, but a very loaded way to present a tool that has its own set of problems with real-world consequences.

The project I thought was most successful was Mitchell Whitelaw’s “generous interface” for the Australian Prints and Printmaking database. With options for guided browsing and search, there are many different entry points into the same collection. In particular, I thought the subjects explorer was a fantastic visualizer for similarity that made image metadata abundantly clear in its interface. The more related a topic was, the more saturated it appears in the sidebar menu, making it very easy to jump between subjects and filter down results. While it requires structured inputs and may not be as flexible as the previous examples, I think the ultimate result is much more navigable and offers more utility to the way people are actually searching and browsing for materials.

The Australian Prints and Printmaking Subject Explorer in action.

I wish more repositories had a way to visualize links between people, organizations, topics, and collections that was so simple to use! The downside to this approach though, as with many tools that yield exciting results, is that it is highly labor intensive and that labor is practically invisible. For each of the 40,000+ works in this collection, each one already had clear, structured metadata with those links between artists and works already established. This is fantastic for a small to mid-sized collection such as this, but this process must be nearly impossible to scale (in a timely manner) for large institutions. For example, the collections I work with at the City of Raleigh currently number at over 35,000+ items accumulated since 1992. I can say from experience that I am constantly updating old descriptions, adding tags and subject headings, creating new scans and photos, and measuring objects in the collection, and there are still at least hundreds of subpar catalog entries that would lead researchers directly into dead ends. And that is just the size of a small local history museum- the North Carolina Museum of History has over 150,000 items in its collection, and huge institutions like the Smithsonian have millions. The sheer amount of labor required to standardize that volume of data is truly astronomical, and I’m not sure how we can create that level of utility and simplicity without either massive funding or the exploitation of GLAM workers- either directly or by training new tools on their work. 

I’ll admit, when searching for more collections interfaces to explore, I had a difficult time finding one to share! Not many had very robust exploration options, and most limited browsing to a collection-by-collection basis. I ended up looking at the collections website for the Indianapolis Museum of Art (my hometown art museum as a child), and found it to be pretty intuitive for browsing. On the landing page, there’s an assortment of featured works along with links for popular searches. I hadn’t seen a museum site that had that feature or that exact wording before, but it shows that they have a knowledge of what bridges already exist between their audience and their collection and a desire to encourage those bridges.

The landing page for the Newfields Collections.

There are also easily accessible sections that show only open access or public domain images. The catalog is extremely clear about copyright, which can be so helpful. Often there is just a vague “the creator owns this” statement on catalog entries that is baked into cataloging systems.

The beginning of 19,000+ results for public domain images.
Note the copyright information near the lower left corner of the photo. When clicked, it links to more information about the copyright of this evening dress.

I also appreciated that you can view past exhibitions from an exhaustive list, and that all works from the exhibition are represented. Most recent exhibition collections also have images of all of the works used where copyright allows, and catalog entries for every image contain information about its copyright. I wouldn’t say it’s a perfect interface, but it does have some pretty solid methods of exploration.

The information page from a recent exhibition at the Indianapolis Museum of Art

Bönisch, Dominik. “The Curator’s Machine: Clustering of Museum Collection Data through Annotation of Hidden Connection Patterns between Artworks.” International Journal for Digital Art History, no. 5 (2020): 5.20-5.35. https://doi.org/10.11588/dah.2020.5.75953.

Offert, Fabian, and Peter Bell. “IMGS.AI.: A Multimodal Search Engine for Digital Art History.” International Journal for Digital Art History, no. 9 (2023): 5.28-5.39. https://doi.org/10.11588/dahj.2023.9.91295.

Whitelaw, Mitchell. “Generous Interfaces for Digital Cultural Collections.” Digital Humanities Quarterly 009, no. 1 (2015).

Copies of copies of copies

This week’s readings and activities were right up my alley- ever since beginning my career transition to cultural heritage four years ago as a volunteer cataloging and digitizing local history, the question of whether or not surrogates are effective has been a pressing question to me. As someone who also has a hefty background in more technical image processing as a compositor, the bits and bytes we use to represent ourselves, our stories, and our society have certainly framed a lot of the ways that I approach cultural heritage. To create, in one form or another, is to abstract. But how many layers of abstraction and how many copies of copies can exist before they become something different altogether? It’s quite a philosophical topic, and Emma Stanford’s article “A Field Guide to Digital Surrogates” did a fantastic job in laying out the points of interest in this discussion succinctly. 

Of course, no conversation about representation of an original is complete without at least acknowledging Walter Benjamin. The conversation of how accurate a surrogate could possibly be has its genesis in the advent of the publicly accessible camera; now that any person can capture an accurate image, what purpose does the original serve? Benjamin’s response (the concept of “aura”) points to the unique physicality of viewing originals, and nearly a hundred years later, we still unequivocally prefer to see the original, regardless of medium. Stanford, however, classifies this as a fundamental (if common) misunderstanding of what the purpose of a surrogate for an art object is. It is neither “a perfect substitute or […] a threat to the original’s authenticity”: It is a tool for delivering a singular perspective of a three-dimensional object, which comes with its own set of pros and cons. As we move beyond simple 2D recreations of objects and into the realm of more advanced digital surrogates (such as the parallax viewer tool created by the Victoria and Albert museum that we explored in class), these questions are pushed back to the forefront of the field. Whether or not more advanced surrogates will actually advance the study of art history seems to be the focus of exploration in this course.

Stanford also touches on something absolutely vital to the creation of advanced surrogates for long-term use: longevity. From an archival standpoint, we have been inundated since day one with the mantra “the archivist is not neutral,” and the same goes for collecting institutions of all kinds. What gets saved, acquired, processed, and made accessible is a slice of a slice of a slice of the overall experience of humanity. I’ve always appreciated Michelle Caswell’s quote, “Not all events ­are recorded; not all records ­are incorporated into archives; not all archives ­are used to tell stories; not all stories are used to write history. Power is implicated in each of these moments; which stories get told, which get for­got­ten, when, and by whom, is inextricably linked ­to the power to tell and to remain silent.” The introduction of power into the equation makes these choices of what and how to digitize that much more pressing and complex. When we take into account the resources necessary to maintain surrogates long-term, this problem further devolves into a case of the haves and have-nots. So, from step zero, there is a massive amount of push and pull from external sources that clouds our ability to answer the question of efficacy. Stafford also echoed a sentiment that anyone who has ever worked with digital objects of any kind has encountered; the tools are arbitrary, and it is the fundamental way of approaching a specific problem that ultimately determines how successful the result will be. 

In taking the time to explore what it takes to make a clean, high-quality, and accessible static digital image, we got to experience first-hand how some of these small decisions quickly shape the experience of the surrogate’s viewer. I brought in a book I purchased for an art history course nearly a decade ago titled The Downtown Book: The New York Art Scene 1974-1984 because I was kind of tickled by the idea of reproducing an image from an era focused on what it means to reproduce, re-contextualize, and re-appropriate an image. I scanned a page with one of Barbara Kruger’s untitled works from 1981 (Your gaze hits the side of my face) printed on it, and got to see firsthand what was lost in the interaction. For instance, when on exhibit, the work is placed in a frame painted bright red- her signature accent color for this era of her work. The frame’s vibrancy only partially made it into the image in the book, and when scanning the image in the book, the stark red border was only further diminished by my (somewhat rushed) cropping job. Frames are such a large part of presentation, and Stanford even describes them in the article as a context clue for the larger meaning of a work. Sure, it’s just a thin, red border, but red is such a prominent part of Kruger’s visual language and seeing it get smaller and smaller in this exercise made me a little sad! Some artifacting from the book’s printing was also included in the scan; there is an inherent graininess to the work, but this scan overly exaggerates its texture. I played around with frequency separation (a retouching method used often for skin in beauty photography) as a method of reducing texture, but ultimately found that separating the grain of the image from the grain of the book’s printing to be nearly impossible. 

Black-and-white photograph of the side profile of a classical marble female bust. Running vertically down the left edge are eight stacked black rectangles containing bold, white, capitalized text that reads: "YOUR GAZE HITS THE SIDE OF MY FACE."
Barbara Kruger
Untitled (Your gaze hits the side of my face), 1981
As scanned by me from The Downtown Book
Black-and-white photograph of the side profile of a classical marble female bust. Running vertically down the left edge are eight stacked black rectangles containing bold, white, capitalized text that reads: "YOUR GAZE HITS THE SIDE OF MY FACE."
Barbara Kruger
Untitled (Your gaze hits the side of my face), 1981
A more professional digitization of the piece.

I was, however, much more satisfied with the scans for two additional items that I brought in to compare how digitizing printed and original works differed. The postcard I brought, which was another printed material, had a similar result as far as added texture and graininess. In this case though, the artifacting present is much more in keeping with the nature of a cheaply printed souvenir photo postcard. I also know for a fact that many, many photos have been taken of this exact angle of downtown over the years (I’ve encountered many a Raleigh skyline postcard in my years with the City’s special collections), so the “aura” of the photo and of the original view feels less important in the digital reproduction from my perspective. I was also quite happy with how the scan of my linocut print (one of my very first) turned out. As a print, which is technically another type of “copy,” I feel like this surrogate comes pretty close to the original intent for the viewing of this work, and I felt a lot more confident being able to edit it myself to fit that view. I wonder if in today’s age, digital reproductions (from living artists, at least) are best obtained from the artist themselves? I think if artists were included in the determination of a “particular interpretation” of their work, as Stanford describes, it would be more accurate; the idea of digital surrogates suddenly becomes much more feasible for artists currently working.

A postcard-style photograph of the Raleigh, North Carolina skyline at twilight. In the upper left corner, white stylized text reads "Raleigh" over "North Carolina".
A souvenir postcard depicting the Raleigh, North Carolina skyline at dusk. Photo by Bill Cobb.
A black-and-white linocut print showing a UFO abducting a spotted cow at night.
4″x6″ Linocut print
Kat Cardullo, 2024

Benjamin, Walter. “The Work of Art in the Age of Mechanical Reproduction.” In Illuminations, edited by Hannah Arendt, translated by Harry Zohn, 217–251. New York: Schocken Books, 1968.
Caswell, Michelle. “Archiving the unspeakable : Silence, memory, and the photographic record in Cambodia.” University of Wisconsin Press. 2014
Stanford, Emma. “A Field Guide to Digital Surrogates.” In The Routledge Companion to Digital Humanities and Art History, 1st ed., edited by Kathryn Brown. Routledge, 2020. https://doi.org/10.4324/9780429505188-19.

« Older posts