Women Architects and World Fairs

Category: ARTH 851 Fall 2026 (Page 2 of 4)

Maps for Narrative-Building

Many of the visualization methods we’ve been looking at this semester fall under the umbrella of distant viewing, and spatial data is no different. Rather than looking solely at the minute details that make up a data point, we’re allowed to take a huge step back and see what patterns, if any, emerge. Because the purpose of this type of visualization is to help illustrate these patterns, it can be versatile as both a research method and a way to express the results of that research. The process of placing textual data about locations into a representation of three-dimensional space can unearth a number of unanticipated complexities within the data used. This is also a very highly visual and contextual medium of representation, so while we did look at some literature on the topic, it made more sense to see as many examples as we could in order to compare and contrast. 

Béatrice Joyeux-Prunel’s work with the Artl@s was a great introduction, since with her chapter “Digital Humanities for a Spatial, Global, and Social History of Art” we got an inside look into the processes and principles that went into the final product. I appreciated the very balanced look she took in the process of mapping; she advocates for mapping as a research method and not necessarily as a standalone product, and gives guidelines for making sure that the purpose of your maps is clear when they are reduced to static images. However, I’m not so sure the final result of the Artl@s project we looked at (Geography of the Parisian Art Market) was all that successful as a final product. The process of conducting this research may have been illuminating, but as we spoke about in class, the final map does a poor job of elaborating on its purpose, function, and ease of use. Having an adjustable timeline was a necessary feature, but the lack of data at each gallery location makes in-depth analysis difficult. This is especially true when juxtaposed with projects like Mapping Gothic France, which contains exhaustive documentation on each of the cathedrals included in the project. I thought that this project was very well scoped, which seems to be a key to success for digital visualization projects. They knew that location mapping was not the only point of the project- it was just one aspect of physicality, which was what they actually hoped to convey. Rather than 1900+ sparse data points they included ~200 thorough data points, which in conjunction with the time afforded to work on the project set it up for a great final product. 

The shift from standard art historical thinking to cartological thinking also appears to have been a difficult one for both the Artl@s project and the Jaskot and Knowles project we looked at. For Jaskot and Knowles, even coming up with a shared vocabulary for architectural historians and historical geographers was difficult. In the article “Architecture and Maps, Databases and Archives: An Approach to Institutional History and the Built Environment in Nazi Germany,” Jaskot and Knowles describe their experience mapping Auschwitz-Birkenau. One important factor they discuss is the decision-making process to narrow down more generic information on construction into definitive data points. Disallowing these ambiguities feels counterintuitive to standard research methodologies, but in order to represent information in this very binary system, it was necessary. Jaskot asks a question in this article that I think is a much more important question than it seems at first glance: “How accurate did our digital models have to be to provide acceptable answers to our questions?” Rather than letting their judgement calls on preciseness sit as end-all-be-all determinations of fact, they were able to allow ambiguity back in by asking how much of that preciseness is actually reflected in the final product. And, since this project ended up acting as more of a research tool than a public-facing visualization, this still ended up surfacing some interesting questions and observations about the spatial and bureaucratic elements of the camp. 

After weighing all of the examples we looked at, we created our own (much, much simpler) spatial maps. I was very intrigued by the narrative framing of StorymapJS, but didn’t think I had enough time to really give a project in it the detail it deserves. So, I looked at Google Maps instead. For my map, I took a look at tourist traps and roadside attractions; I think they’re such an interesting phenomena (and a wealth of weird vernacular art!), and I wanted to (hopefully) illustrate how the development of highways created and shaped many of these little kitschy spots.

I unfortunately didn’t get super far into the highways part of my map, but fortunately Google maps does display highways. Most of the 20 locations I chose are either in urban metropolises or right off of major interstates, and I was a bit surprised that this held true for both new and old attractions! I’m sure maps like this have been made a dozen times over, but I definitely would like to continue with this little project. I was also curious to see if specific types of attractions were concentrated in particular geographic zones, but I think I would need more data points to really analyze that. For instance, Georgia seems to have a lot of oddities museums and West Virginia has (at least) two cryptid museums- it would be interesting to interrogate why that is. 

Jaskot, Paul B., and Kelly Ann Knowles. “An Approach to Institutional History and the Built Environment in Nazi Germany.” Getty News, February 15, 2017. https://www.getty.edu/news/dah_jaskot_knowles/.

Joyeux-Prunel, Béatrice. “Digital Humanities for a Spatial, Global, and Social History of Art.” In The Routledge Companion to Digital Humanities and Art History, 1st ed., edited by Kathryn Brown. Routledge, 2020. https://doi.org/10.4324/9780429505188-10.
Charting Japonisme

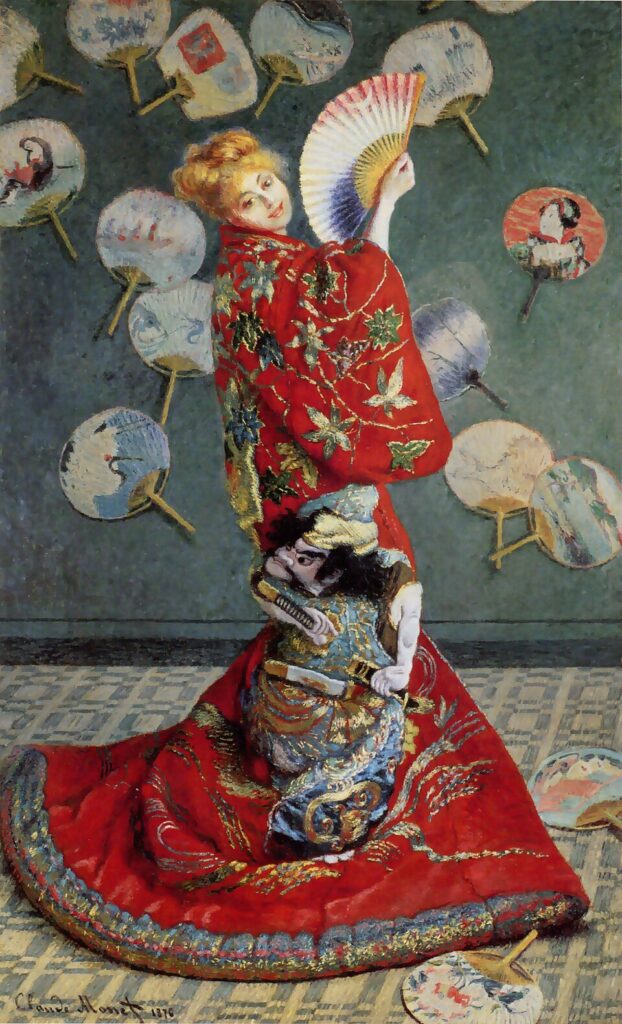
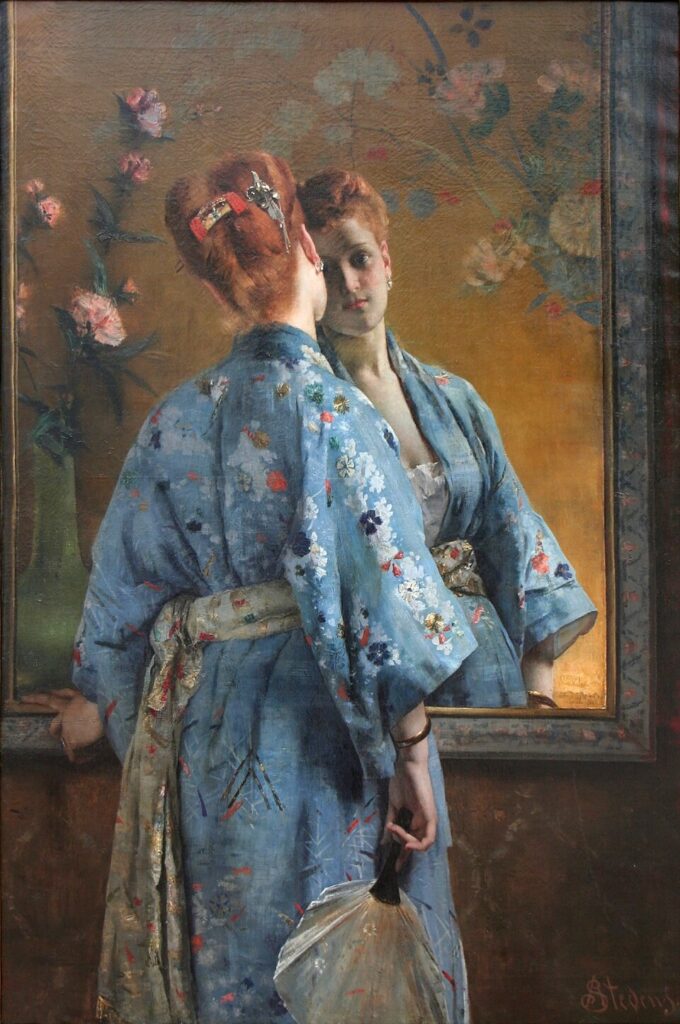
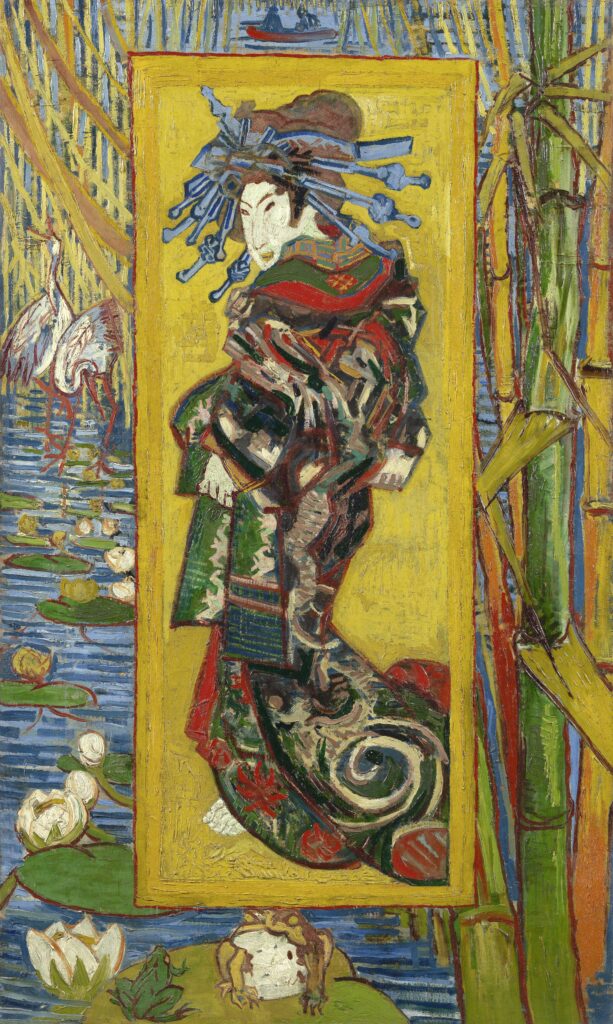
As an undergraduate, I had an idea for my senior independent study thesis that I couldn’t quite figure out how to realize. I wanted to create a digital collection of Japonist paintings from 19th century Europe. More specifically, I wanted to chart out just how quickly Japanese imagery (stylization, recreations, motifs, etc.) and goods (kimono, fans, ceramics, etc.) appeared in European paintings. I had lots of visual data – which is to say, I had knowledge of many works of art that would have fit into my project – and I had a pretty solid research question: just how many works of art fall into the category of Japonsime? The only issue is I had no idea how to even approach such a topic as the scope and methodology just felt too ambitious. Now that I am a masters student, I see how I could use data analysis and digital art history to make my project into reality. So, after six years of rumination, here is my proposal for how I could achieve my academic dream of realizing my project which I shall affectionately title Charting Japonisme.

La parisienne japonaise by Alfred Stevens, 1872.

Literature Review

In 2018 Van Gogh and Japan, Treaty of Kanagawa,

The Courtesan (after Eisen) by Vincent van Gogh, 1887.

Research Questions

Timeline of when it became popular, how prevalent it was, what areas it was most prevalent in. Connect that data to art dealers and track trade movement of real objects.

La collectionneuse au kimono vert by Frans Verhas, 1881.

Methodology

Scope of project to just paintings and just Europe (maybe even just France). One approach to keep this project feasible as a student would be to focus on a specific few artists. I am most notably interested in Vincent van Gogh and Claude Monet. I could use their catalogues raisonnés and chart exactly when they began incorporating Japanese objects and iconography into their paintings.

La Japonaise by Claude Monet, 1876.

Future of this project?

I miss doing this work!!!!!

When the tombstone isn’t enough: how we represent uncertain data

The concept of authoritative data is inextricably linked to Western methods of cultural understanding. When we expect data to be clean, neat, and authoritative, we are leaving behind more complex questions of ownership and history. Susan Elizabeth Gagliardi and Constantine Petridis’s article “Mapping Senufo: Making Visible Debatable Information and Situated Knowledge” makes the case for an expansion of our implicit beliefs about data using West African art as an example. In these cases, Gagliardi and Petridis found typical “tombstone” style data to be insufficient; aside from dubious methods of obtaining provenance from early 20th century collectors, very rarely are these works attributed to a single person or even a single use. In their case, the only things they could identify with any reasonable amount of certainty were the approximate locations that these objects were crafted in. While this has the potential to be the case for a large swath of art historians, there is not a lot of work going on to standardize the ways in which this information is represented in databases. This is an interesting conundrum- the way we structure and standardize data is essential to its legibility and usability, but it is clearly not serving everyone in the ways that it should. While I’m not fully sure I understand the more expressive, illustrative visualization methods proposed for Mapping Senufo, I appreciate that they are grappling with this question and attempting to propose alternative methods of promoting understanding.

A possible design for Mapping Senufo featuring hand-rendered elements, created by Mark Addison Smith after photographs in the Michel Convers collection, Musée du quai Branly-Jacques Chirac, Paris, as presented on January 31, 2020, to the Mapping Senufo team. Courtesy of and © Mark Addison Smith.

The slippery nature of data is easy enough to talk about, but it becomes really clear when you start working with it. In our workshop this week, we took a look at a few visualization methods using API data from the Tate. Each of the 65,000+ entries in the spreadsheet had a reasonable amount of tombstone information in them, but a few factors quickly limited what we could do with the data. Firstly, any field with unstandardized text (or text at all, really) was immediately off the table for generating graphs and charts. This meant that anything with a date range or uncertain creator was inaccessible for this form of visualization. For the Tate this is less of a problem since they do not particularly focus on antiquities, but for many other museums, any level of uncertainty makes data from whole eras and movements inaccessible. This was something I also ran into while working on my CollectionBuilder exhibit– when looking at the material culture of spiritualism in the late 19th and early 20th century, many of these objects were used and refined over long periods of time. Attribution is also further complicated by the fact that many of these objects are a type of ephemera intended to be used in performance and never acknowledged as true objects with authorship- to acknowledge that the “ectoplasm” is a thin linen pulled from the nose of Helen Duncan would immediately and irrevocably alter the purpose of the object by disrupting the suspension of disbelief. While the specific dilemmas any field of research faces regarding the certainty of their classification and identification will be different, this exercise has driven home the point that complete standardization of data is virtually impossible (even with just ten items).

In addition to looking at the textual metadata for images, we also took some time to look into text analysis this week. It was something I had been vaguely aware of, but didn’t quite know the extent of what you could do with it. I thought the project Mining the Dispatch was particularly successful in illustrating what text analysis can do. The tool looks at trends in the Richmond Daily Dispatch throughout the duration of the Civil War; when viewing graphs of multiple trends at once, hypotheses start to form. For instance, viewing trends for clothing advertisements alongside trends of articles mentioning trade can illustrate when some of the effects of blockades were starting to be felt by Virginians. In order to explore text analysis on our own we looked at the tool Voyant, which creates a dashboard of potential textual analysis tools for one or more textual documents. It offers word clouds, trends on word usage, frequency of phrases, correlations between words and phrases, and a number of visualization tools to represent the text.

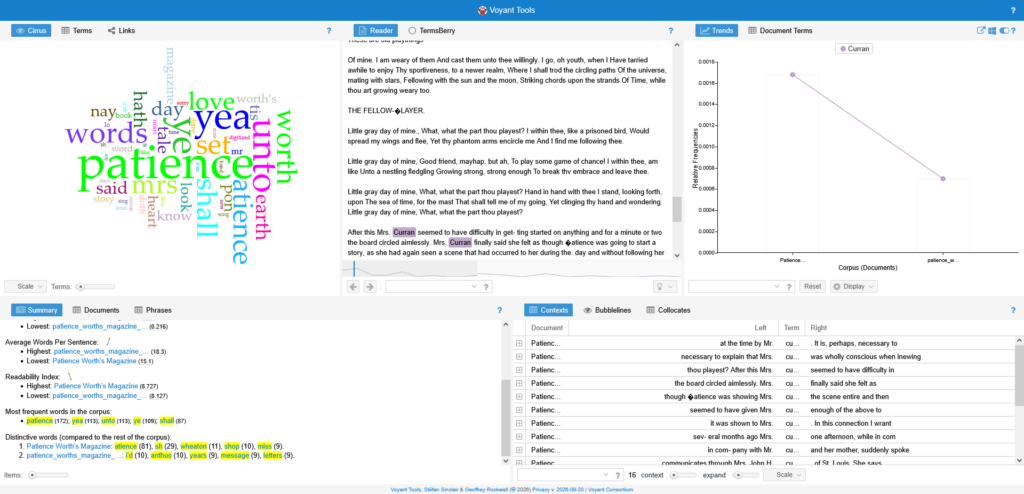
Since I had a PDF of Patience Worth’s Magazine that I used for my digital exhibit, I was curious what results Voyant would return for the first and last issues of the magazine. The language of Patience Worth is perhaps the most notable and most debated part of her works (besides the authenticity of her otherworldly origin); written in a faux-archaic English, her poems and fiction never seem to falter in their own internal logic system. Voyant offers a ton of different ways to visualize and understand Patience’s notoriously dense writing style as well as track changes from document to document. I was curious to see how mentions of Pearl Curran, the “channeler” of Patience, changed from the first issue to the last issue, and Voyant showed a clear drop in the frequency of “Curran” (most likely because the context of Patience’s writings was long out of the way by the final issue).

Voyant comparing the August 1917 and May 1918 issues of Patience Worth’s Magazine.

Of course this is just a beta version of the tool, but it still was very interesting to see what I could get out of it! And, as we learned this week, the tool is only as good as what you can put into it- these PDFs fortunately had decent OCR, but anything with poor OCR, large files, or more than two pdfs is unusable with this iteration of Voyant.

As for what types of data I might be interested in working with, I’m honestly not too sure. To be frank, I don’t have a clear, defined research topic- everything I drew from this week was from a lifelong personal interest in the occult, not true academic research. However, working with CollectionBuilder these past two weeks has offered me some more interesting ways of using metadata to visualize similarities and differences. I would be interested in using museum APIs to visualize collection data and explore trends, but that does unfortunately rely on museums to have very clear and unambiguous metadata. As we have learned from Mapping Senufo, that can be extremely difficult to come by.

Gagliardi, Susan Elizabeth, and Constantine Petridis. “Mapping Senufo: Making Visible Debatable Information and Situated Knowledge.” The Art Institute of Chicago, December 19, 2022. https://www.artic.edu/digital-publications/37/perspectives-on-data/23/mapping-senufo-making-visible-debatable-information-and-situated-knowledge.

Defining Ambiguity: The Challenge of “Clean” Data in Art History

            The word “data” seems like it strikes fear in the hearts of all scholars in the humanities, especially in a field like art history. While it would be easy to say that the future of art history is inevitably digital, I think that also discounts the work that good data analysis pioneered by art historians can do for the field. Earlier in the semester, we learned how data analysis can inspire creative digital humanities projects and digital collections. These efforts ultimately make art, history, and knowledge more accessible to those around the world. Shouldn’t that be the goal of any good scholarship?

            I had this in mind as I read our assigned articles this past week discussing exactly how to extract this good, clean data that could make knowledge an scholarship more accessible. It turns out, the answer is not quite as clear! Scholars disagree on exactly how to organize data and institutions abide by a certain standard of sharing their data. We saw these opposing views of data organization confronting each other in Susan Elizabeth Gagliardi and Constantine Petridis’s article, “Mapping Senufo: Making Visible Debatable Information and Situated Knowledge,” and Karl W. Broman and Kara H. Woo’s, “Data Organization in Spreadsheets.”[1]

            The main difference between Gagliardi and Petridis’s article and Broman and Woo’s is how they treat ambiguity. Ambiguity and uncertainty is unavoidable in art history and surfaces often with ancient art or non-western art, like the Mapping Senufo project which involved organizing West African art. For Gagliardi and Petridis, they struggled to adequately assign labels to pieces of art that had an unclear artist or origin, owing to the fact that there may be multiple spellings or names for the artist or locations. Broman and Woo suggest that every cell in a spreadsheet should be filled, even if the information is unknown, and to have a standardized spelling or phrase to describe the same piece of data. This is helpful to eliminate inconsistences across spreadsheets, but it may not be truly reflective of the actual data.

In the case of the Mapping Senufo project, assigning a standardized name to an artist or location eliminates the ambiguity and reduces its cultural complexity. This elimination of ambiguity asserts that only one name is correct and any other spellings are wrong, imposing this binary worldview and a misleading authority of certainty. If a date or exact artist’s name is unknown, it would be dishonest to represent an approximation or educated guess as authoritatively true.

Including this ambiguity of the unknown is not conducive to using the data for further analysis, though. In class, we saw how one museum, the Tate in London, combatted this in their publicly available API. The Tate includes a qualitative column next to their quantitative information to explain how and when they simplify their data to format it best for analysis. For example, if a painting was created circa 1840 to 1850, they would include that information in the qualitative column, while a more concrete date, “1840,” is added in the quantitative column. In this way, the museum can be transparent about the information they have while also providing the best approximated information for data analysis.

The key takeaway that I gleaned from this topic of data and data analysis from a humanities perspective is that ambiguity is ok—and necessary—in a field like art history. In an environment where data analysis seems to be an exciting new path towards future art historical scholarship, it may be necessary to artificially “clean” ambiguous data for analysis. As long as the data originator is transparent about ambiguity and uncertainty in their data, I think that it can be responsibly simplified for helpful data analysis.

Text Analysis

            Text analysis is another method that can be helpful for humanities research, including art history. In class this week, we reviewed the Google N-Gram Viewer and the Voyant text analysis software. Even simple functions like counting word frequency or word placement can be helpful for pinpointing main ideas, subjects, or terminology that occur frequently across a corpus of documents.

             For understanding broad trends across all published works, I think that the Google N-Gram word frequency tracker is especially useful. Like most digital tools used in humanities research, this tool identifies patterns, but it cannot provide an explanation for that discovered pattern. For example, in class we discussed how certain words may simply appear less in the 19th century simply because there were less publications compared to the most recent decade. This tool may be helpful for tracking the popularity of certain ideas or concepts, but it is still just a starting point for deeper analysis.

            Voyant seems especially useful for scholars who have several text documents to sift through. Using an example article from a library science course, I found phrases and terms that recurred often throughout the text. It was helpful to see phrases that occurred the most often and where they appeared throughout the text.

            For a research paper, I am examining the book plates in Owen Jones’s 1856 book, The Grammar of Ornament. I think that text analysis with Voyant will be appropriate to use for this project. Before using the Voyant application, I would need to ensure that the PDF of Jones’s digitized work has been properly OCR’d so that it recognizes the text. Then, I can use Voyant to see what words and phrases that Jones uses frequently. This can give me a better idea, not only of Jones’s work, but also of the language that his contemporaries may have used in related texts.

            To further explore Jones’s The Grammar of Ornament, I am considering creating a more comprehensive searchable collection of the book plates in the text. I began this project by uploading ten book plates into CollectionBuilder’s GitHub. To continue this project, I would need to add to the metadata organized in a Google Sheet, including the standard “tombstone” data along with the file identifier. This data can then be converted into a CSV file to be uploaded into CollectionBuilder. This project would not be possible without accessible, data analysis tools.

            Incorporating digital tools into the field of art history does not reduce the role of the scholar. In fact, they can aid in analysis and increase accessibility to this scholarship. There are also creative aways to maintain art history’s ambiguity or at least methods to maintain transparency. Through clean data and data analysis, art historians can integrate digital tools into their methodology, continuing make their scholarship more accessible and innovative.


[1] Karl W. Broman and Kara H. Woo, “Data Organization in Spreadsheets,” The American Statistician 72, 1 (2018): 2-10.; Susan Elizabeth Gagliardi and Constantine Petridis, “Mapping Senufo: Making Visible Debatable Information and Situated Knowledge,” in Perspectives on Data, ed. Emily Lew Fry and Erin Canning (Art Institute of Chicago, 2022).

Getting Permission: Who has the right to make archives public?

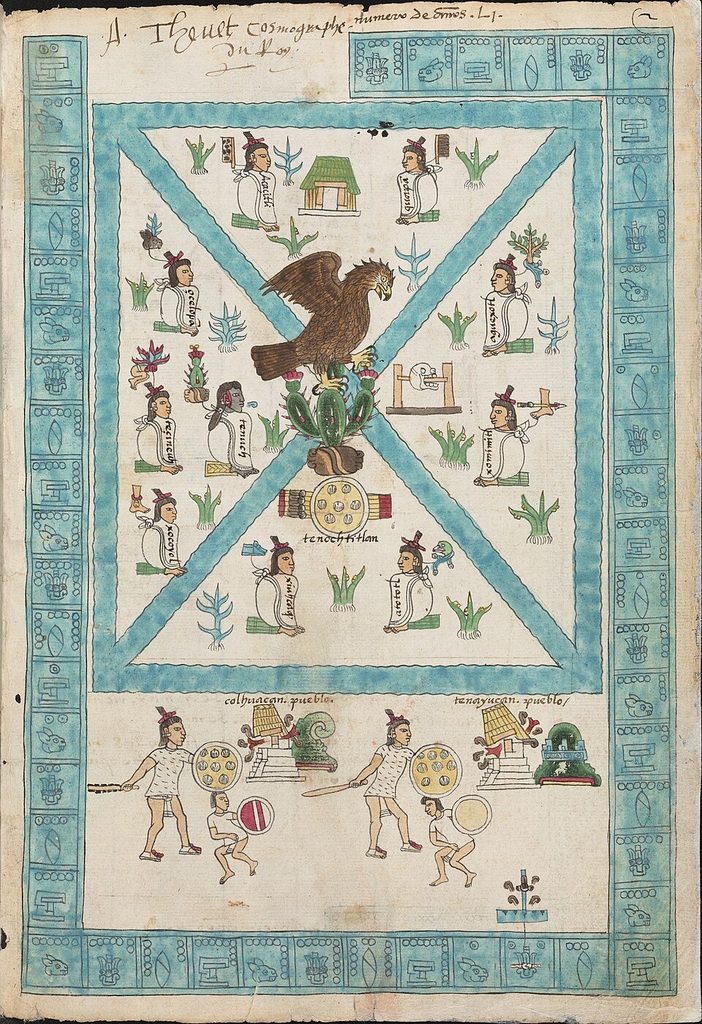
Codex Zouche-Nuttall (source: Michel Wal, GFDL, via Wikimedia Commons)
Week FOur, 9/8/2026

This week, we’re thinking about developing digital collections, and the issues posed by using photos that do not necessarily belong to you. It’s easy to see the connection between these two topics—in order for students to utilize programs like Omeka to create class projects, they often have to pull images and other files from outside sources, like archives and museums. While I was creating my Omeka project as an undergrad, I was lucky enough (or perhaps unlucky enough?) to have photographed and processed all of those images myself, such that our readings which outline scholars’ general anxiety about permissions and images surprised me. 

Once again I’m drawing from my own experience with Omeka, which can be viewed in my projects page.

However, an issues report on “Copyright, Permissions, and Fair Use among Visual Artists and the Academic and Museum Visual Arts Communities,” sponsored by CAA, detailed quite convincingly that not only are the majority of scholars anxious about using images, but that this anxiety can really hinder research. The report notes that scholars simply are unaware of how copyright law actually functions, and therefore that their “work is constrained and censored, most powerfully by themselves, because of that confusion and the resulting fear and anxiety.”1 (CAA Report, 7) 

Much of the report is spent advocating for the understanding of fair-use images, and images in the public domain. Essentially, while scholars might be worried that they’d face legal repercussions for not gaining permission to use a specific image, oftentimes they are well within their legal right to use said image under fair-use policy. I imagine this is equally, if not moreso, the case for students who create publicly available projects as part of their coursework. In those cases, there’s a clear educational motive behind the use of whichever image.

One such example is the work done by art historian Lauren Kilroy-Ewbank, who began implementing Omeka into her classroom to explore the pre-Columbian Mixtec Codex Zouche-Nuttall.2 In her article, “Doing Digital Art History in a Pre-Columbian Art Survey Class: Creating an Omeka Exhibition Around the Mixtec Codex Zouche-Nuttall,” Kilroy outlines how and why Omeka specifically was her collection-builder of choice for students. The interface is fairly beginner-friendly (though it definitely has its frustrating aspects) and students can organize different pages under one larger exhibition. This means that although each student was learning and writing about the same Codex, they would make their specific page about only one aspect of the codex—say, one specific symbol or theme.

Further, this visually-forward platform allows art history students to equally value images and text as aspects of their scholarship, which is sometimes lost in traditional essays. Kilroy also mentioned that she had an assignment which trained students in DublinCore, the language conventions widely-used by archivists. I thought that not only was this a potentially useful skill for the job market, but also that it’s a great way to get students thinking about some of the fundamentals of art objects. “What is this object made of?” and “what is it used for?” might appear to be an obvious question, but it is essential that we begin with those considerations when we’re discussing art objects. 

Codex Mendoza (public domain via Wikimedia Commons). Note: I was lucky enough to handle a real codex, very similar to the early-colonial era codex seen above, at the Benson Latin American Library while I was a student a UT Austin. It was pretty awesome.

Finally, in class this week we began to explore CollectionBuilder, an open-source model for creating digital collections using metadata and linked files. Like all good digital art history tools (see Omeka above), CollectionBuilder is free and open to use by the public. A similar model to this can be found in ArchivesSpace, which is also open-source, but is more focused on internal data management rather than user interface, and is most often used by institutions as opposed to individuals. CollectionBuilder finds much of its strength in its relative accessibility, and seems to be most useful for pulling public domain and fair-use files from different sources to be compiled in one exhibit. Another strength of CollectionBuilder is the built-in user interface: it’s simple but effective, and it automatically creates a timeline.

It must be said, however, that the biggest weakness of CollectionBuilder is the fact that it relies heavily on HTML coding. Despite the digital prowess and training that archivists generally have, often those abilities manifest in their use of specific programs like the aforementioned ArchivesSpace, or the popular TheMuseumSystem. Further, us art historians often seem like luddites in comparison to our more computationally-minded colleagues in the archives, meaning that CollectionBuilder’s heavy reliance on code is even more of a barrier to access. While I understand that one cannot ask too much for a free-to-use and communally created software, the fact that users have to navigate code and coding in order to develop a collection makes the software somewhat more inaccessible. Even so, I am excited to start building my own collection using CollectionBuilder, with my fair-use and public domain images of course!

  1. Patricia Aufderheide, et al. Copyright, Permissions, and Fair Use among Visual Artists and the Academic and Museum Visual Arts Communities: An Issues Report (College Art Association, 2014) ↩︎
  2. Lauren G. Kilroy-Ewbank, “Doing Digital Art History in a Pre-Columbian Art Survey Class: Creating an Omeka Exhibition Around the Mixtec Codex Zouche-Nuttall,” Journal of Interactive Technology and Pedagogy, no. 12 (February 2018) ↩︎

What makes a successful digital collection?

While I had some cursory knowledge about digital collections and exhibits, it was great to take this week’s topic as an opportunity to really dig into what goes into making them work well. In her article “Doing Digital Art History in a Pre-Columbian Art Survey Class: Creating an Omeka Exhibition Around the Mixtec Codex Zouche-Nuttall,” Lauren G. Kilroy-Ewbank very clearly lays out her thought processes for why Omeka is such a great tool for teaching her undergraduate students how to think on a deeper level about both the Mixtec Codex Zouche-Nuttall and the ways in which its presentation affects its meaning. The codex’s nonlinear and non-textual narrative is uniquely suited to the benefits a digital exhibit can offer; it is a highly visual and modular presentation method. Pieces are easily rearranged, recontextualized, annotated, described, and compared. Working in Omeka right off the bat, while sometimes challenging for her students, also acts as a digital veil-lifting of sorts; as beginner students of art history, it is likely that many of these students have done most of their artwork viewing digitally. By having students investigate and explore metadata on their own, it immediately becomes apparent that everything they had seen about artworks online previously has been highly constructed, and suddenly every decision made from the classification of the object down to the digitized image itself becomes apparent. I had never thought about using this process as a pedagogical tool, but Kilroy-Ewbank makes an excellent case for using this type of digital curation to teach both textual and metatextual readings of artwork.

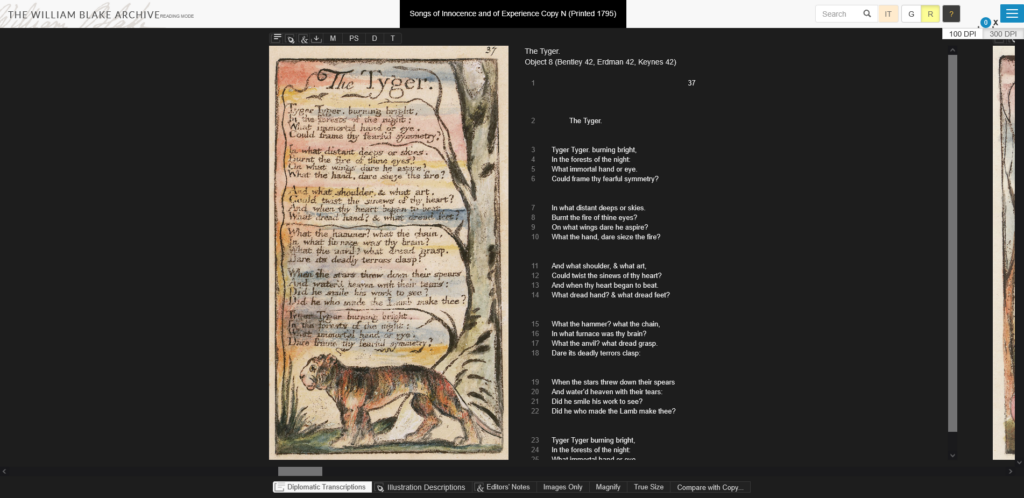
We also took a look at the William Blake Archive, which is a digital collection of both the poetry and visual art of William Blake maintained by the UNC Chapel Hill Libraries and ITS. The site contains both a searchable/browsable collection of his works as well as curated exhibitions with interpretive commentary from scholars. This archive is laid out very thoughtfully, and I particularly enjoyed looking at the documentation for the project! I had never seen a project lay out their past and present standards so clearly before, which is a shame because transparency is something that many archives are trying to improve. Not only does transparency help other institutions and collections know what you have (and its quality) so that your collection can be advertised via word of mouth, it helps build trust from your users when they can see how you decide what should be included in the collection and who took part in that decision-making. I also thought that the interface was well-chosen since it allows the user to toggle between written and visual information via a “gallery” and “reading” mode. When viewing a piece, the list of related pieces (with thumbnails) in that same series is also available below the main image viewer.

The William Blake Archive in “Reading” mode.

And, to make comparison even easier, the site has a lightbox feature! After hearing about how the lightbox of slides is a dying method of building theses in art history, I appreciated that the developers of this site still saw its value. Of course, it’s not a perfect site by any means (some of the dropdown menus could be better streamlined, etc), but as far as a custom-built interface for a narrowly-focused collection goes, this was a good one. I feel like I’m always saying that whenever anything isn’t tailor-made to a collection, no matter whether it’s something technical like a collection interface or something more bureaucratic like policy, it definitely shows. And while I’m not a scholar of William Blake, I can easily see how this resource would be a staple reference to return to. 

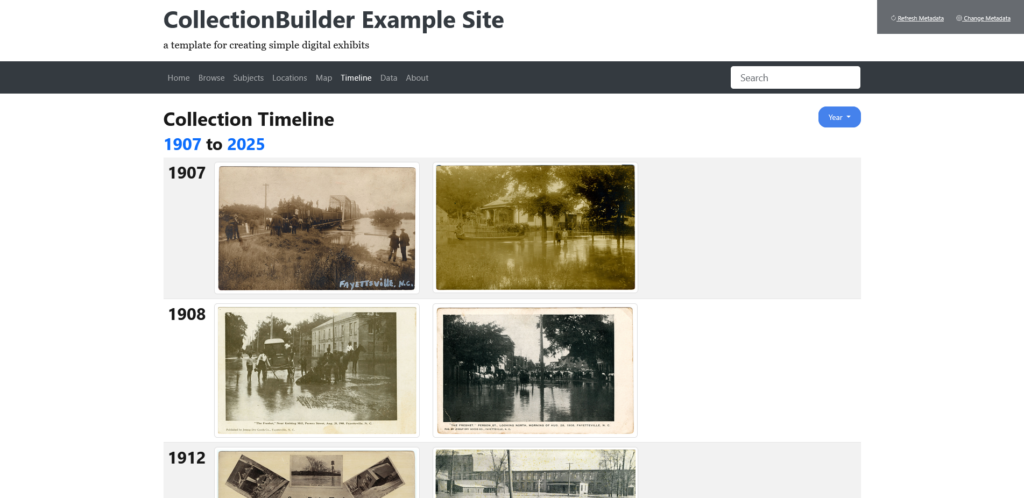
After looking more deeply at what makes a good digital tool, we also started out on our first project: to make our own mini-exhibit in CollectionBuilder. I had heard of CollectionBuilder before, and it was actually a system we had considered using in my practicum project (organizing, cataloging, and partially scanning hundreds and hundreds of slides encompassing 50+ years of work from Chapel Hill-born photographer Avery Danziger) but ultimately decided not to use because we didn’t believe it would be sustainable long-term for the artist to run on his own (and he preferred an offline system). I somewhat regret that now after seeing how easy it is to build, and it would have worked great with his goals of being able to view his work by subject, date, and location! I was kind of shocked at how easy it was- all you really have to do is have a GitHub account, make a copy of the template containing the source code and file directory, and link up a google spreadsheet to let that data populate on the site. It’s pretty difficult to mess up, and you don’t need to do a ton of ground-up web design to make it usable- plus it’s even open source! The basic template allows for browsing by a number of different methods (via map, subject, date, and even just in a list), which is a feature I have particularly appreciated on all of the collection interfaces I’ve found to be successful. No gimmicks, just clear, thorough metadata that offers a few predetermined ways of getting a collection overview. So, in a user experience sense, I really like CollectionBuilder.

The timeline from the example site we built in class with a test dataset.

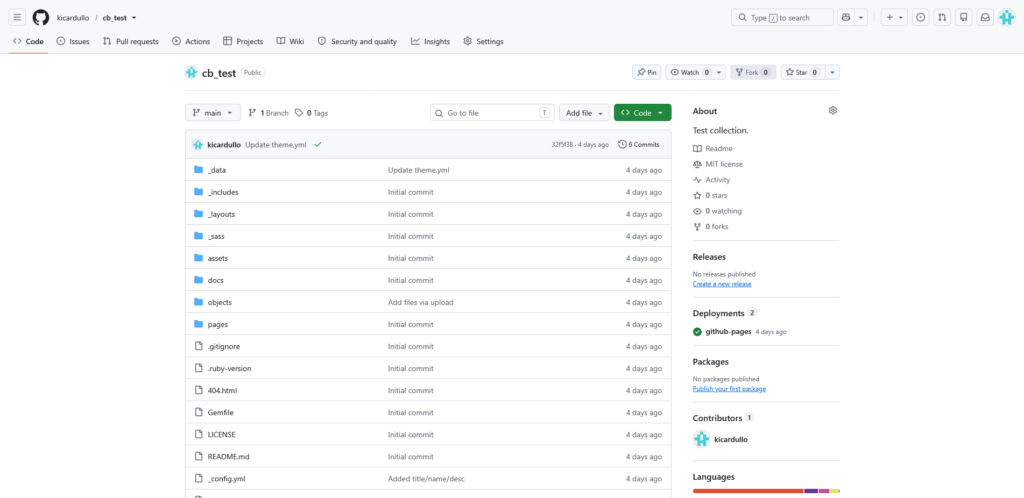
I do, however, see a few drawbacks with it. Firstly is that it is entirely dependent on GitHub, which is a for-profit company now owned by Microsoft. If you know anything about digital preservation, you know that this can put a huge wrench in longevity plans- it’s unclear how long Microsoft will continue to support GitHub or what would happen to it if Microsoft decided to abandon the site. It seems to be safe for the foreseeable future because it is a massively popular code repository (that even a lot of digital preservation tools are hosted on!), but as with anything for-profit, longevity is not guaranteed. Secondly, without coding experience, it can be difficult to change the basic template sites to something custom. From what I understand from looking at the documentation (I am not a code-minded person!), the benefit of using Jekyll as a basis for your site is that it takes a lot of the work out of coding an HTML site from scratch by using layouts and modular blocks. This is both a pro and a con- it’s fool-proof to use, but ultimately you’re kind of limited by what you’re given to work with.

The CollectionBuilder file directory for the template in GitHub. Kind of scary if you don’t know what you’re looking at.

As I work more in CollectionBuilder this week, I’ll be curious to see how my opinion changes!

Kilroy-Ewbank, Lauren G. “Doing Digital Art History in a Pre-Columbian Art Survey Class: Creating an Omeka Exhibition around the Mixtec Codex Zouche-Nuttall: Doing Digital Art History in a Pre-Columbian Art Survey Class: Creating an Omeka Exhibition around the Mixtec Codex Zouche-Nuttall.” Re-viewing Digital Technologies and Art History, February 21, 2018. https://cuny.manifoldapp.org/read/doing-digital-art-history-in-a-pre-columbian-art-survey-class-creating-an-omeka-exhibition-around-the-mixtec-codex-zouche-nuttall-9ecc5e1c-2062-4cd4-9ede-a7589404cd17/section/2ec0cf43-4333-4c25-aeba-d9aefb521d3b.

Relevance Searching for Images Using Different Platforms

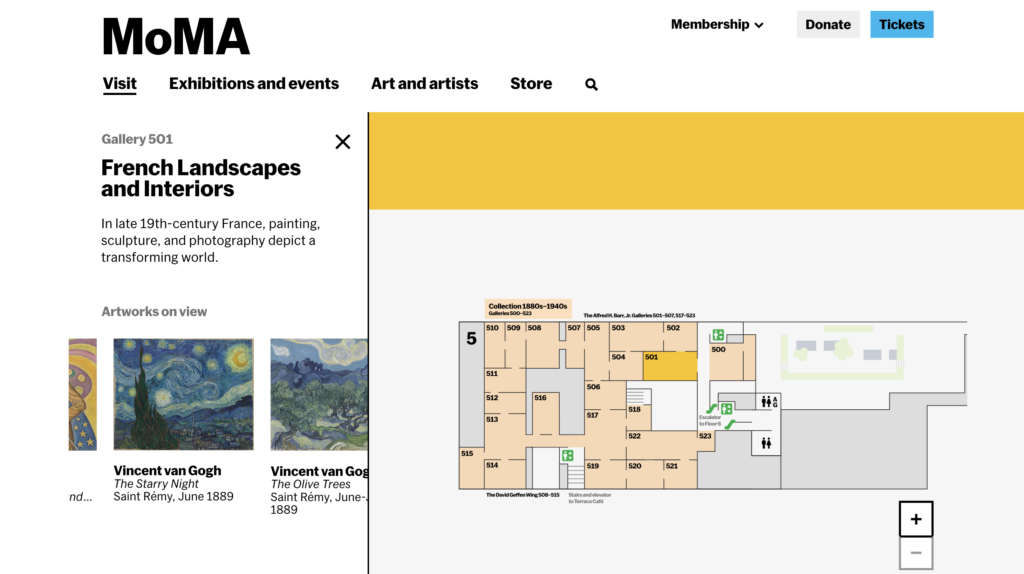
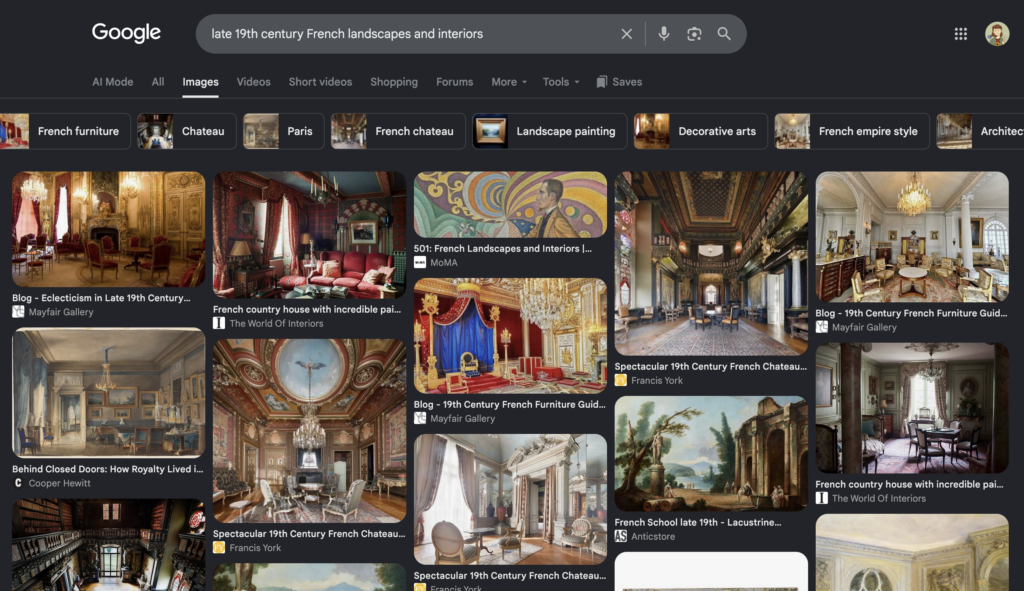
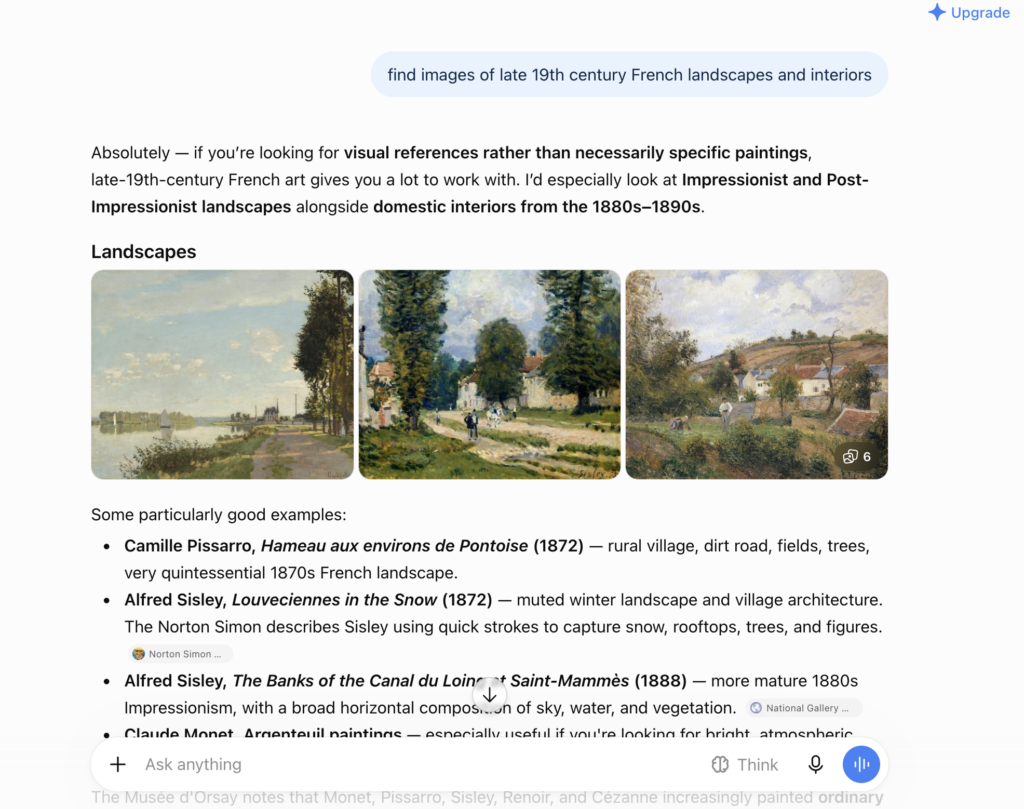
Google has been around since 1998, but I recently found out that Google Images has only been around since 2001. Even further, reverse image searching was only added as a function to Google Images in 2011. The internet seems so built around images, but search functionality is entirely built on text infrastructure. Finding relevant images with a Google search is a game of careful search engine optimization and it is a game that the user has to master. Finding relevant images from a search inquiry is a skill that we have come accustomed to, but are there other ways we can find images? Consider a museum as an analogy to consider alternative image search options. We may go to the MoMA looking to see Starry Night and Starry Night only. We can go to the help desk and inquire, “where is Starry Night?” and we would get an exact answer to find our image. This is akin to a traditional text-based image search inquiry. Consider instead someone who is interested in seeing late 19th century French landscapes and interiors. Upon inquiry, they will be delighted to know that someone at the MoMA has already curated an entire gallery of works that are relevant to their needs. Their inquiry is more broad, so with a traditional image search inquiry might produce a wide variety of results ranging in relevance. Importantly, in a traditional search, the user has to vet these images for relevance. In the museum example, the curator of the museum has already done the vetting. The museum has eliminated the possibility of finding irrelevant works. Intentionally curated image collections change how we are able to find relevant images.

For this blog post, I will explore how search image results vary depending on which platform the inquiry is made. The search platforms I will use are Google, the built in search function on the Museum of Modern Art website, and ChatGPT. I then will assess the results for their relevance to the inquiry, their ease of use, and any other noteworthy observations. For consistency of results, I will use the same search inquiry for all platforms: “late 19th century French landscapes and interiors.”


The Museum of Modern Art

Screencapture of Museum of Modern Art Map https://www.moma.org/visit/guide/map?location=501. Accessed September 13, 2026.
Screencapture from Gallery 501 https://www.moma.org/calendar/galleries/5695. Accessed September 13, 2026.

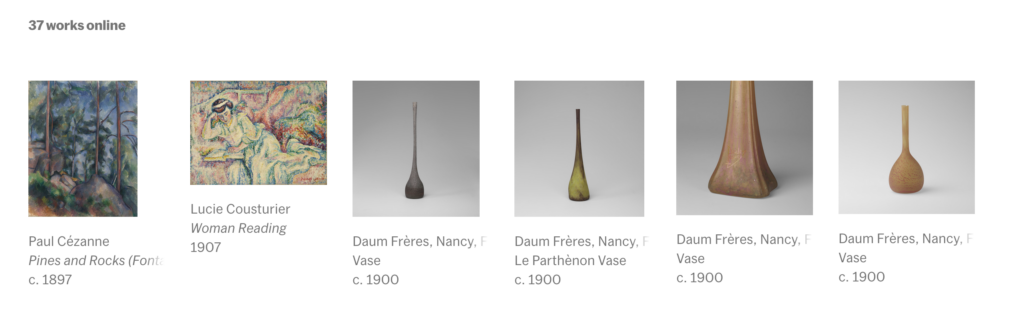
The Museum of Modern Art, like many museums with an online presence, have digitized the pieces from their on-display collection.


Google


ChatGPT

Digital Art History in the Undergraduate Classroom

            Lauren Kilroy-Ewbank’s article “Doing Digital Art History in a Pre-Columbian Art Survey Class: Creating an Omeka Exhibition Around the Mixtec Codex Zouche-Nuttall” unites the themes that we have been discussing as a class since the beginning of the semester.[1] Within her experimental integration of digital art history into a Pre-Columbian art survey class, Kilroy-Ewbank notes the challenges, successes, and potential for using a digitally centered project as a part of her pedagogical methodology. We can see the product of educating students in building digital repositories through interfaces like The William Blake Archive. Introducing digital tools to practice digital art history earlier in art history students’ educations will facilitate new and innovative projects.

            The objective of Kilroy-Ewbank’s project for her students was to create an interactive digital exhibition investigating various characteristics of the Pre-Columbian Mixtec Codex Zouche-Nuttall. Kilroy-Ewbank explained that students often had trouble understanding the pictorial nature of written Mixtec communication. She saw the creation of this interactive exhibition as a method for students to meaningfully interact with the piece in order to achieve greater comprehension of the work as well as Mixtec art and communication more broadly. By dividing students into teams to learn how to create their exhibit from a new digital tool, Omeka, she made collaboration necessary to the classroom rather than the more traditional research paper completed individually.

            Alison Langmeade also wrote about how digital art history encourages collaboration in her example of the University of Pittsburgh’s Visual Media Workshop (VMW).[2] Through this organization of students, Langmeade explained how the VMW allowed students to collaborate on projects together rather than conduct research in isolation. Kilroy-Ewbank’s Omeka project for her students functions in the same way. She notes that even outside the project, she encouraged collaborative research and study made possible by Google Apps suitable for sharing notes with whole classes. She also acknowledges, like Langmead and Paul Jaskot, that digital analysis is useful for macroanalysis and for finding spatial and temporal patterns in works but that it is the human’s responsibility to explain the pattern.[3] The pictorial nature of the Codex Zouche-Nuttall also lends itself to be analyzed and explained well through a digital project.

            Without knowing a lot about the Codex Zouche-Nuttall itself, its overwhelming amount of images remind me of Hieronymus Bosch’s Garden of Earthly Delights. Last week, I also mentioned Bosch’s work and the Netherlands’ subsequent digital humanity project that creates an audio-visual experience where the user can zoom in and click on details for further information.[4] I can imagine students creating a similar digital project for the Codex Zouche-Nuttall. Kilroy-Ewbank notes how students were responsible for collecting comparative images and the potential to integrate geographical or topographical data into their exhibitions. The practice of creating, arranging, and constructing a digital exhibition not only allowed students to create a unique research project to learn more about a piece of Mesoamerican history, but it also introduced undergraduate students to digital tools to disseminate scholarship in an age inundated with digital images.

            One challenge that Kilroy-Ewbanks noted was students’ frustrations with using Omeka, a completely new tool for them, and the ensuing awkwardness or inconsistencies that manifested in the resulting exhibition. I am experiencing similar frustration technological frustration while using the digital repository-building tool, Collection Builder through GitHub. During my undergraduate studies, I had taken classes that did involve aspects of digital humanities and digital art history, but I mostly participated in the research and scholarship rather than the digital construction.

While studying abroad in Rome, Italy, I worked with fellow students in a Museum Studies class to create a digital exhibition of fake art confiscated by the Carabinieri de Tutelo di Patrimonio (the site is still active if you would like to check it out! Deception by Design: Lessons from Forgeries). A graduate student constructed the digital exhibition, while the undergraduate students researched and wrote about the objects. In her class, Kilroy-Ewbanks required the students to also be involved in the maintenance of metadata and construction of the digital exhibition.

            The creation of digital exhibitions and repositories like The William Blake Archive are helpful for sharing scholarship with a greater public and for creating new scholarship. Kilroy-Ewbanks notes in the conclusion of her article that some of her goals for the Codex Zouche-Nuttall project included having her students learn the importance of sharing scholarship and the fact that history is created through thoughtful research and synthesis. The William Blake Archive is an early example of a digital project aimed at increasing access and generating scholarship related to the art and writing of William Blake. Starting in 1995, The William Blake Archive unites the works of Blake across several repositories and features rotating digital exhibits that highlight different aspects of Blake’s lifetime as an artist, like an exhibition dedicated to his work in Sussex for William Hayley or his drawings of the pilgrims in Chaucer’s Canterbury Tales. The William Blake Archive is a great example of the past of digital projects, but it also inspires the future for even better digital repositories.

            The William Blake Archive is not without its faults. Likely because of its long life, issues of maintenance and uniformity inevitably become issues as contributors and editors come and go. I think that as more scholars experiment with creating digital tools, upkeep and maintenance will prove to be an important factor to consider as the life of the project persists.  

            Integrating digital art history methods into undergraduate art history curriculum, like Kilroy-Ewbanks’ assigned project, allows art history to adapt to the digital world. As scholarship is almost entirely shared and produced online, it is important for students of art history to learn about helpful digital tools for their own research interests—technological frustration and all.


[1] Lauren G. Kilroy-Ewbank, “Doing Digital Art History in a Pre-Columbian Art Survey Class: Creating an Omeka Exhibition around the Mixtec Codex Zouche-Nuttall,” Journal of Interactive Technology and Pedagogy, no. 12 (February 2018).

[2] Alison Langmead, “Art and Architectural History and the Performative, Mindful Practice of the Digital Humanities,” Journal of Interactive Technology and Pedagogy, no. 12 (February 2018).

[3] Paul B. Jaskot, “Digital Art History as the Social History of Art: Towards the Disciplinary Relevance of Digital Methods,” Visual Resources 35:1-2 (2019), 26.

[4] Pieter van Huystee Film, NTR, Jheronimus Bosch, the Garden of Earthly Delights (Pieter van Huystee Film, NTR, 2016), https://archief.ntr.nl/tuinderlusten/en.html#.

« Older posts Newer posts »